



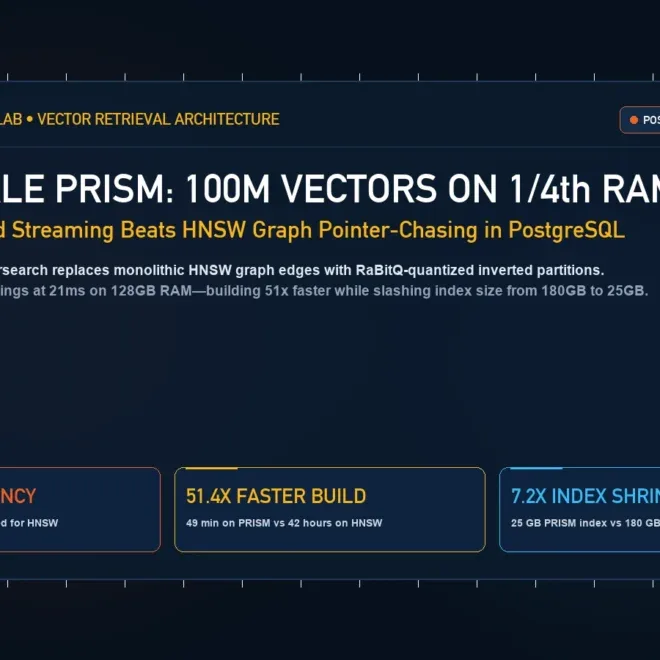
Timescale PRISM: Run 100M Vectors on 1/4th Postgres RAM

Timescale pg_vectorsearch and PRISM replace HNSW graphs with RaBitQ-quantized partitions, serving 100M vectors at 21ms on 128GB RAM with 51x faster builds.
EyesTech Context & Retrieval Desk, analyzing vector database architectures, dense retrieval pipelines, and long-context needle-in-haystack dynamics. Editorial Standards: https://eyestech.in/editorial-policy/
Timescale pg_vectorsearch and PRISM replace HNSW graphs with RaBitQ-quantized partitions, serving 100M vectors at 21ms on 128GB RAM with 51x faster builds.
A vLLM report shows decode speed dropping to 0.5–5 tok/s during long prefills. Learn what the data proves, what it does not, and how to diagnose it.
OpenAI announced Dots on September 29. Its documented goals, app access and approval rules replace earlier speculation about filters and biometric controls.

An empirical systems audit of HNSW vs. IVF-PQ indexing across 100 million 1536-dimensional vectors. Benchmarking Qdrant, OpenSearch, Milvus, and Faiss on RAM footprint, Recall@10, QPS throughput, and NVMe disk-spilling economics.