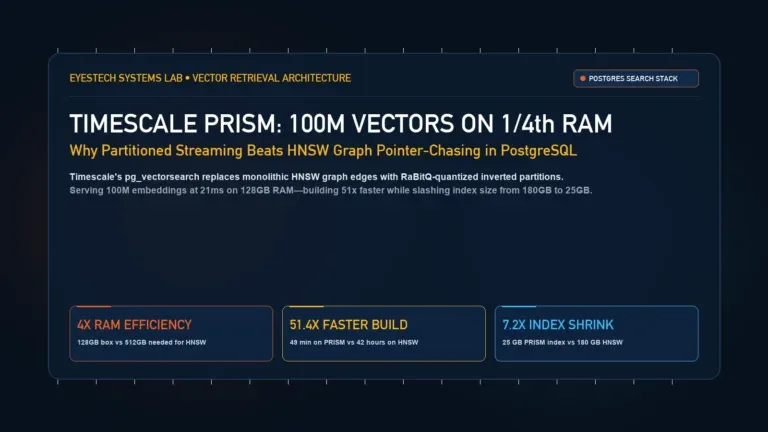

Timescale pg_vectorsearch and PRISM replace HNSW graphs with RaBitQ-quantized partitions, serving 100M vectors at 21ms on 128GB RAM with 51x faster builds.
Silicon architectures, VRAM requirements, GPU benchmarks, Apple Silicon unified memory, and local LLM deployment.
Timescale pg_vectorsearch and PRISM replace HNSW graphs with RaBitQ-quantized partitions, serving 100M vectors at 21ms on 128GB RAM with 51x faster builds.
Google’s TPU v7 Ironwood scales to 9,216 chips and 1.77 PB of HBM. We examine optical circuit switching, long-context KV cache demands and memory limits.
d1-omni-600M returns typed decisions without generated text. Image and audio scores need separate validation, with 30-second speech and input limits.
MiniCPM-V 4.7 1B needs a 672 MB language file plus a 1.11 GB vision projector. Get the Ollama tag, llama.cpp recipe and visual-compression settings.
pg-jev evaluates Postgres rows through a decision API. Batches of 20 and session caches change cost; LIMIT 3 does not guarantee three billed rows.
MiniCPM-V 4.7 reports 13+ tokens/s in 3GB phone memory. Expert loading, quantization and speculation explain why that is not its total weight size.
Muse Wonder costs $4/$20 per million input/output tokens. Full requires a Muse Code plan; max reasoning changes effort, not the model you access.
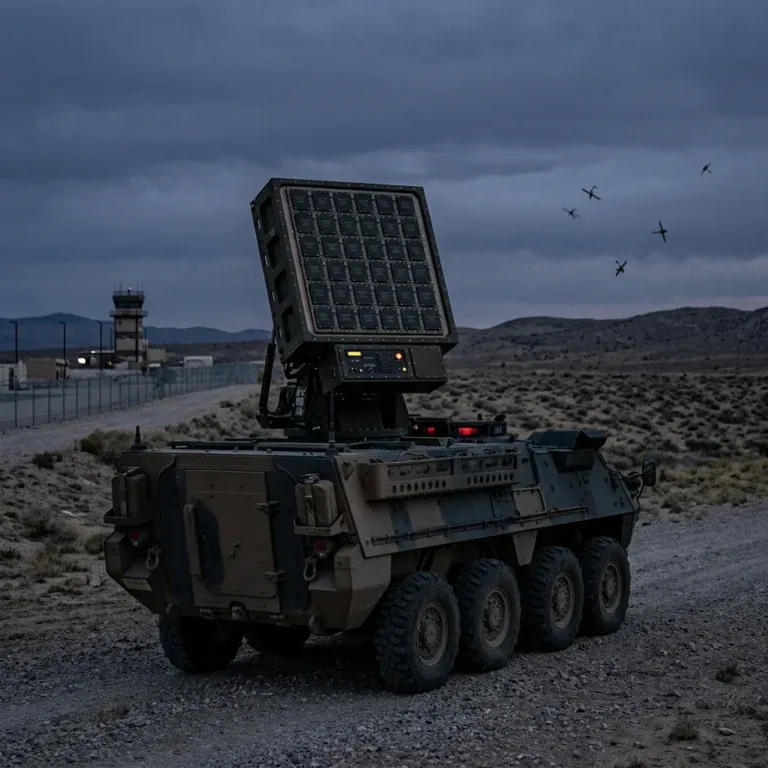
Solid-state GaN HPM arrays disable dozens of drones in microseconds, bypassing 3-5s laser dwell limits and frying unshielded PCB traces at 15-30V surges.
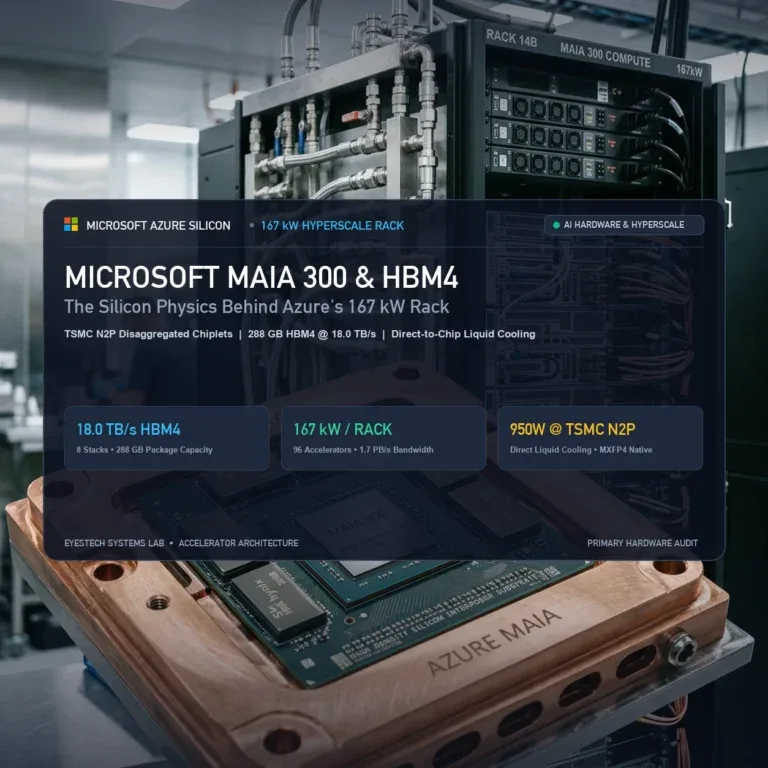
Microsoft Maia 300 pairs 288GB HBM4 at 18 TB/s on TSMC N2P across 96-chip 167 kW racks, bypassing Nvidia memory walls via direct-to-chip liquid cooling.
NVIDIA Research’s Low-Rank Gradient Sketches (LoGRA) algorithm reduces reinforcement learning optimizer VRAM consumption by 45.7% on 7-billion-parameter…