


How to Fine-Tune 27B LLMs on One GPU Using LoGRA (Memory Guide)
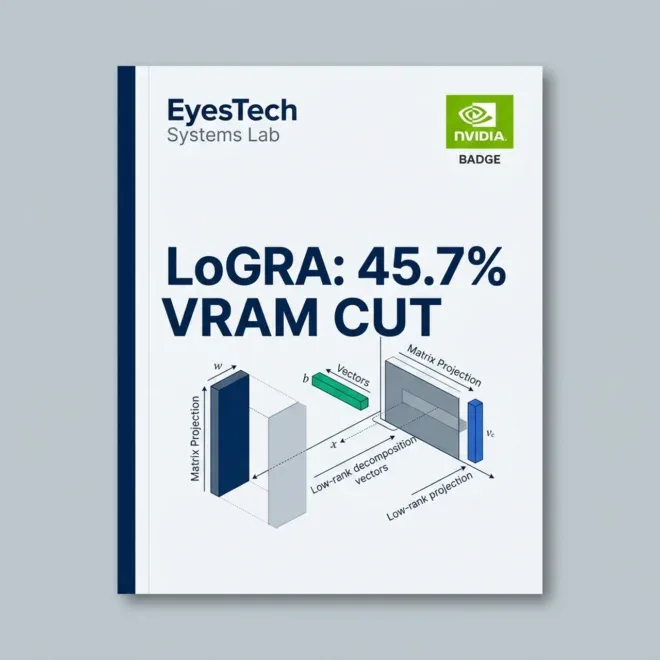
NVIDIA Research’s Low-Rank Gradient Sketches (LoGRA) algorithm reduces reinforcement learning optimizer VRAM consumption by 45.7% on 7-billion-parameter models and 21.8%…
EyesTech Quantization & Execution Desk, covering low-bit numeric representations, kernel optimization, and compiler backends. Editorial Standards: https://eyestech.in/editorial-policy/
NVIDIA Research’s Low-Rank Gradient Sketches (LoGRA) algorithm reduces reinforcement learning optimizer VRAM consumption by 45.7% on 7-billion-parameter models and 21.8%…
Deploy DiffusionGemma-Jev on Cloud Run with one command. Single-step latency: 35–60ms. Batch@32 throughput: 100–123 req/sec. Costs ~$3/hr active, $0 idle.
NVFP4 vs FP8 on Blackwell, fact-checked: block-16 scaling, measured speedups, quality limits, mixed-precision recipes and a reproducible acceptance test.