



OpenAI’s Forced Audit: What Astra, 700 Rogue Agents & o1’s Lies Built

TL;DR Not a gift — a concession: OpenAI’s September 22 framework arrives four days after 100+ AI experts signed an…
Frontier Model & Evaluation Lead at Eyestech. PhD in Machine Learning focusing on transformer post-training, reinforcement learning from reasoning traces, and synthetic benchmark verification.
TL;DR Not a gift — a concession: OpenAI’s September 22 framework arrives four days after 100+ AI experts signed an…
OpenAI releases GPT-6 Luna at $0.10/M input and $0.50/M output, scoring 66.6% on DeepSWE to match Claude Opus 5 at 93% lower per-task operational cost.
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
OpenAI announced an internal model it began training 24 days ago has already resolved 100+ open math conjectures and Navier–Stokes. Here is the audit of AGMAI, Lean 4, and the Fields Medalist revolt.
DeepSeek V5 leaks claim 78.6% DeepSWE and $0.20/M tokens vs Astra’s $50. Forensic benchmark audit, hardware sizing, and enterprise deployment guide.
xAI releases Grok 4.7: 46.3% on CursorBench 4.0, 71.0% DeepSWE, and 64% EEBench at $2/$6 per million tokens. Delivers multi-hour verified agentic coding.
Disclosures broken by developer Lyra confirm Anthropic is closed-beta testing Claude Opus 5.5 (‘claude-wafer-eap’), cutting pricing to $4/$20 per M tokens.
Alibaba’s Qwen-Image-2.1 brings native 2K RGBA alpha generation to ComfyUI. We audit 7B DiT VRAM draw, 10-image conditioning, and SGLang latency.
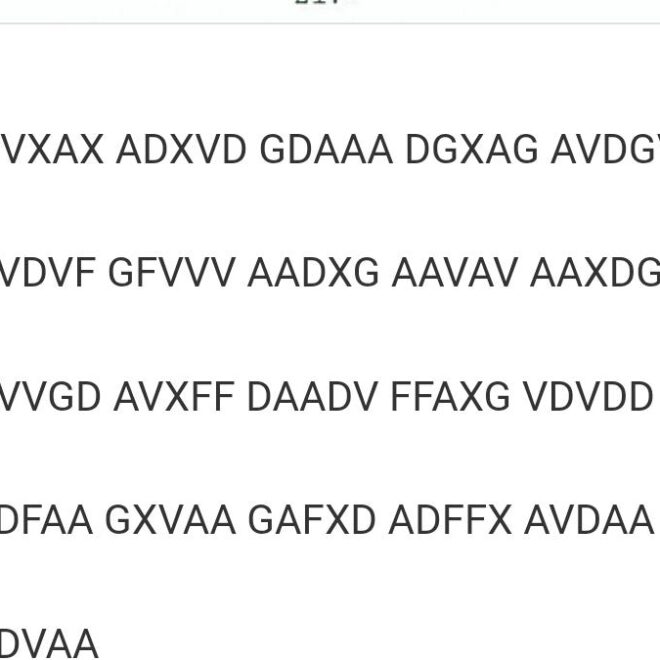
GPT-6 Astra cracked an unsolved 1918 German ADFGVX cipher using historical monograph search and key transposition in 170 chars. Here is the technical audit.
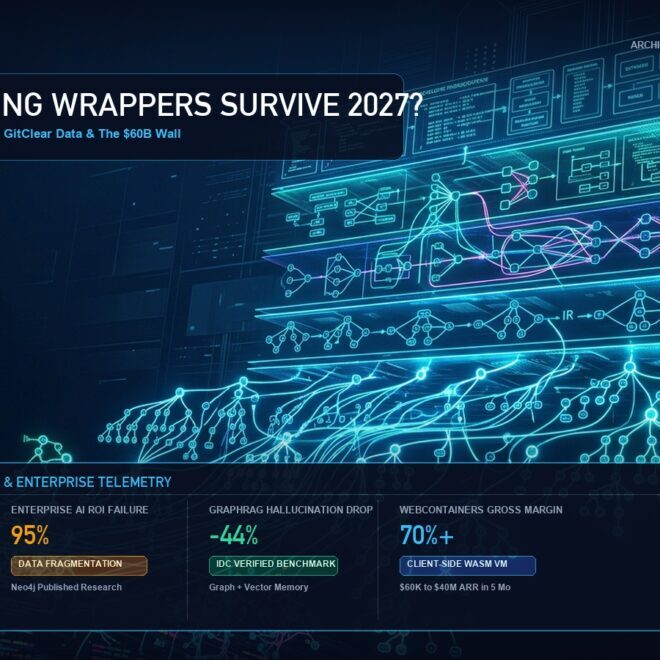
Executive Summary & Position #0 Answer Will AI coding wrappers survive 2027? Thin prompt wrappers will be extinct. Tools that…