


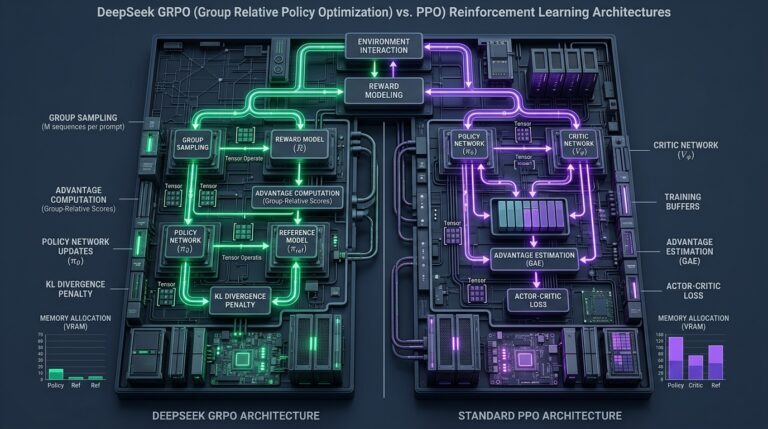

Scaling Reinforcement Learning from Human Feedback (RLHF) to multi-thousand-token reasoning models encountered an insurmountable systems bottleneck: the…
Scaling Reinforcement Learning from Human Feedback (RLHF) to multi-thousand-token reasoning models encountered an insurmountable systems bottleneck: the…
Qwen3.8 Flash-Next vs GLM-5.3 Flash: the short version Qwen3.8 Flash-Next and GLM-5.3 Flash are not “small models”…

If you have been reading the headlines over the last few months, you might be convinced that…
