
What did Google and its collaborators actually achieve with Dream-RSI? They solved a fundamental economic bottleneck in autonomous coding agents: recursive policy self-improvement without expensive real-world compiler and LLM evaluations. Rather than updating neural network weights or running thousands of wasteful trial-and-error benchmarks, Dream-RSI repurposes historical discovery trees as zero-cost replay simulators to optimize an executable Python exploration controller.
1. Pre-Release Speculation vs. The September 14 Reality
In mid-2026, the artificial intelligence research ecosystem experienced intense speculation regarding Google DeepMind’s internal projects. A stylized “congRatulationS I” tweet from an executive, an unauthenticated screenshot alleging a model dubbed rsi-model-liverl-le in staging environments, and statements from Sam Altman and Dario Amodei forecasting autonomous AI researchers by 2026–2027 collectively primed the tech sector for a breakthrough in Recursive Self-Improvement (RSI).
On September 14, 2026, the actual paper materialized on arXiv (arXiv:2609.14858): “Dream-RSI: Recursive Self-Improvement for Code Discovery via Historical Trajectory Replay.” Authored by Zhuoheng Zheng, Yifan Zhang, Zezhou Wang, Yang Liu, and Boqing Gong — representing Google, Google DeepMind, the University of Maryland, and the University of Virginia — the paper presented an exceptionally clever, grounded systems achievement.
2. The Core Dilemma in Long-Horizon Code Discovery
Autonomous code discovery frameworks — such as AlphaEvolve, OpenEvolve, and SimpleTES — operate by pairing a high-capacity coding LLM with an automated execution sandbox. While checking an individual program snippet takes seconds, evaluating an exploration policy (how the agent balances breadth vs. depth, backtracking, and stopping criteria) requires observing cumulative performance across entire multi-step rollouts.
In prior discovery scaling studies like SimpleTES, discovering an optimized Lasso path solver consumed a massive budget of 51,200 generation calls. Evaluating new exploration heuristics via live online trial-and-error creates an unsustainable cost wall: each candidate policy burns thousands of physical compiler runs and frontier LLM invocations before its efficacy can be verified.
3. The Core Mechanism: Turning Discovery History into a Replay Simulator
To break this meta-optimization bottleneck, Dream-RSI draws an architectural analogy to model-based reinforcement learning (such as Danijar Hafner’s Dreamer framework). In model-based RL, an agent learns an environment dynamics model and dreams rollouts inside it. In code discovery, an agent’s completed exploration runs already constitute an empirical world model: structured trees of states, candidate mutations, compiler execution logs, and benchmark scores.
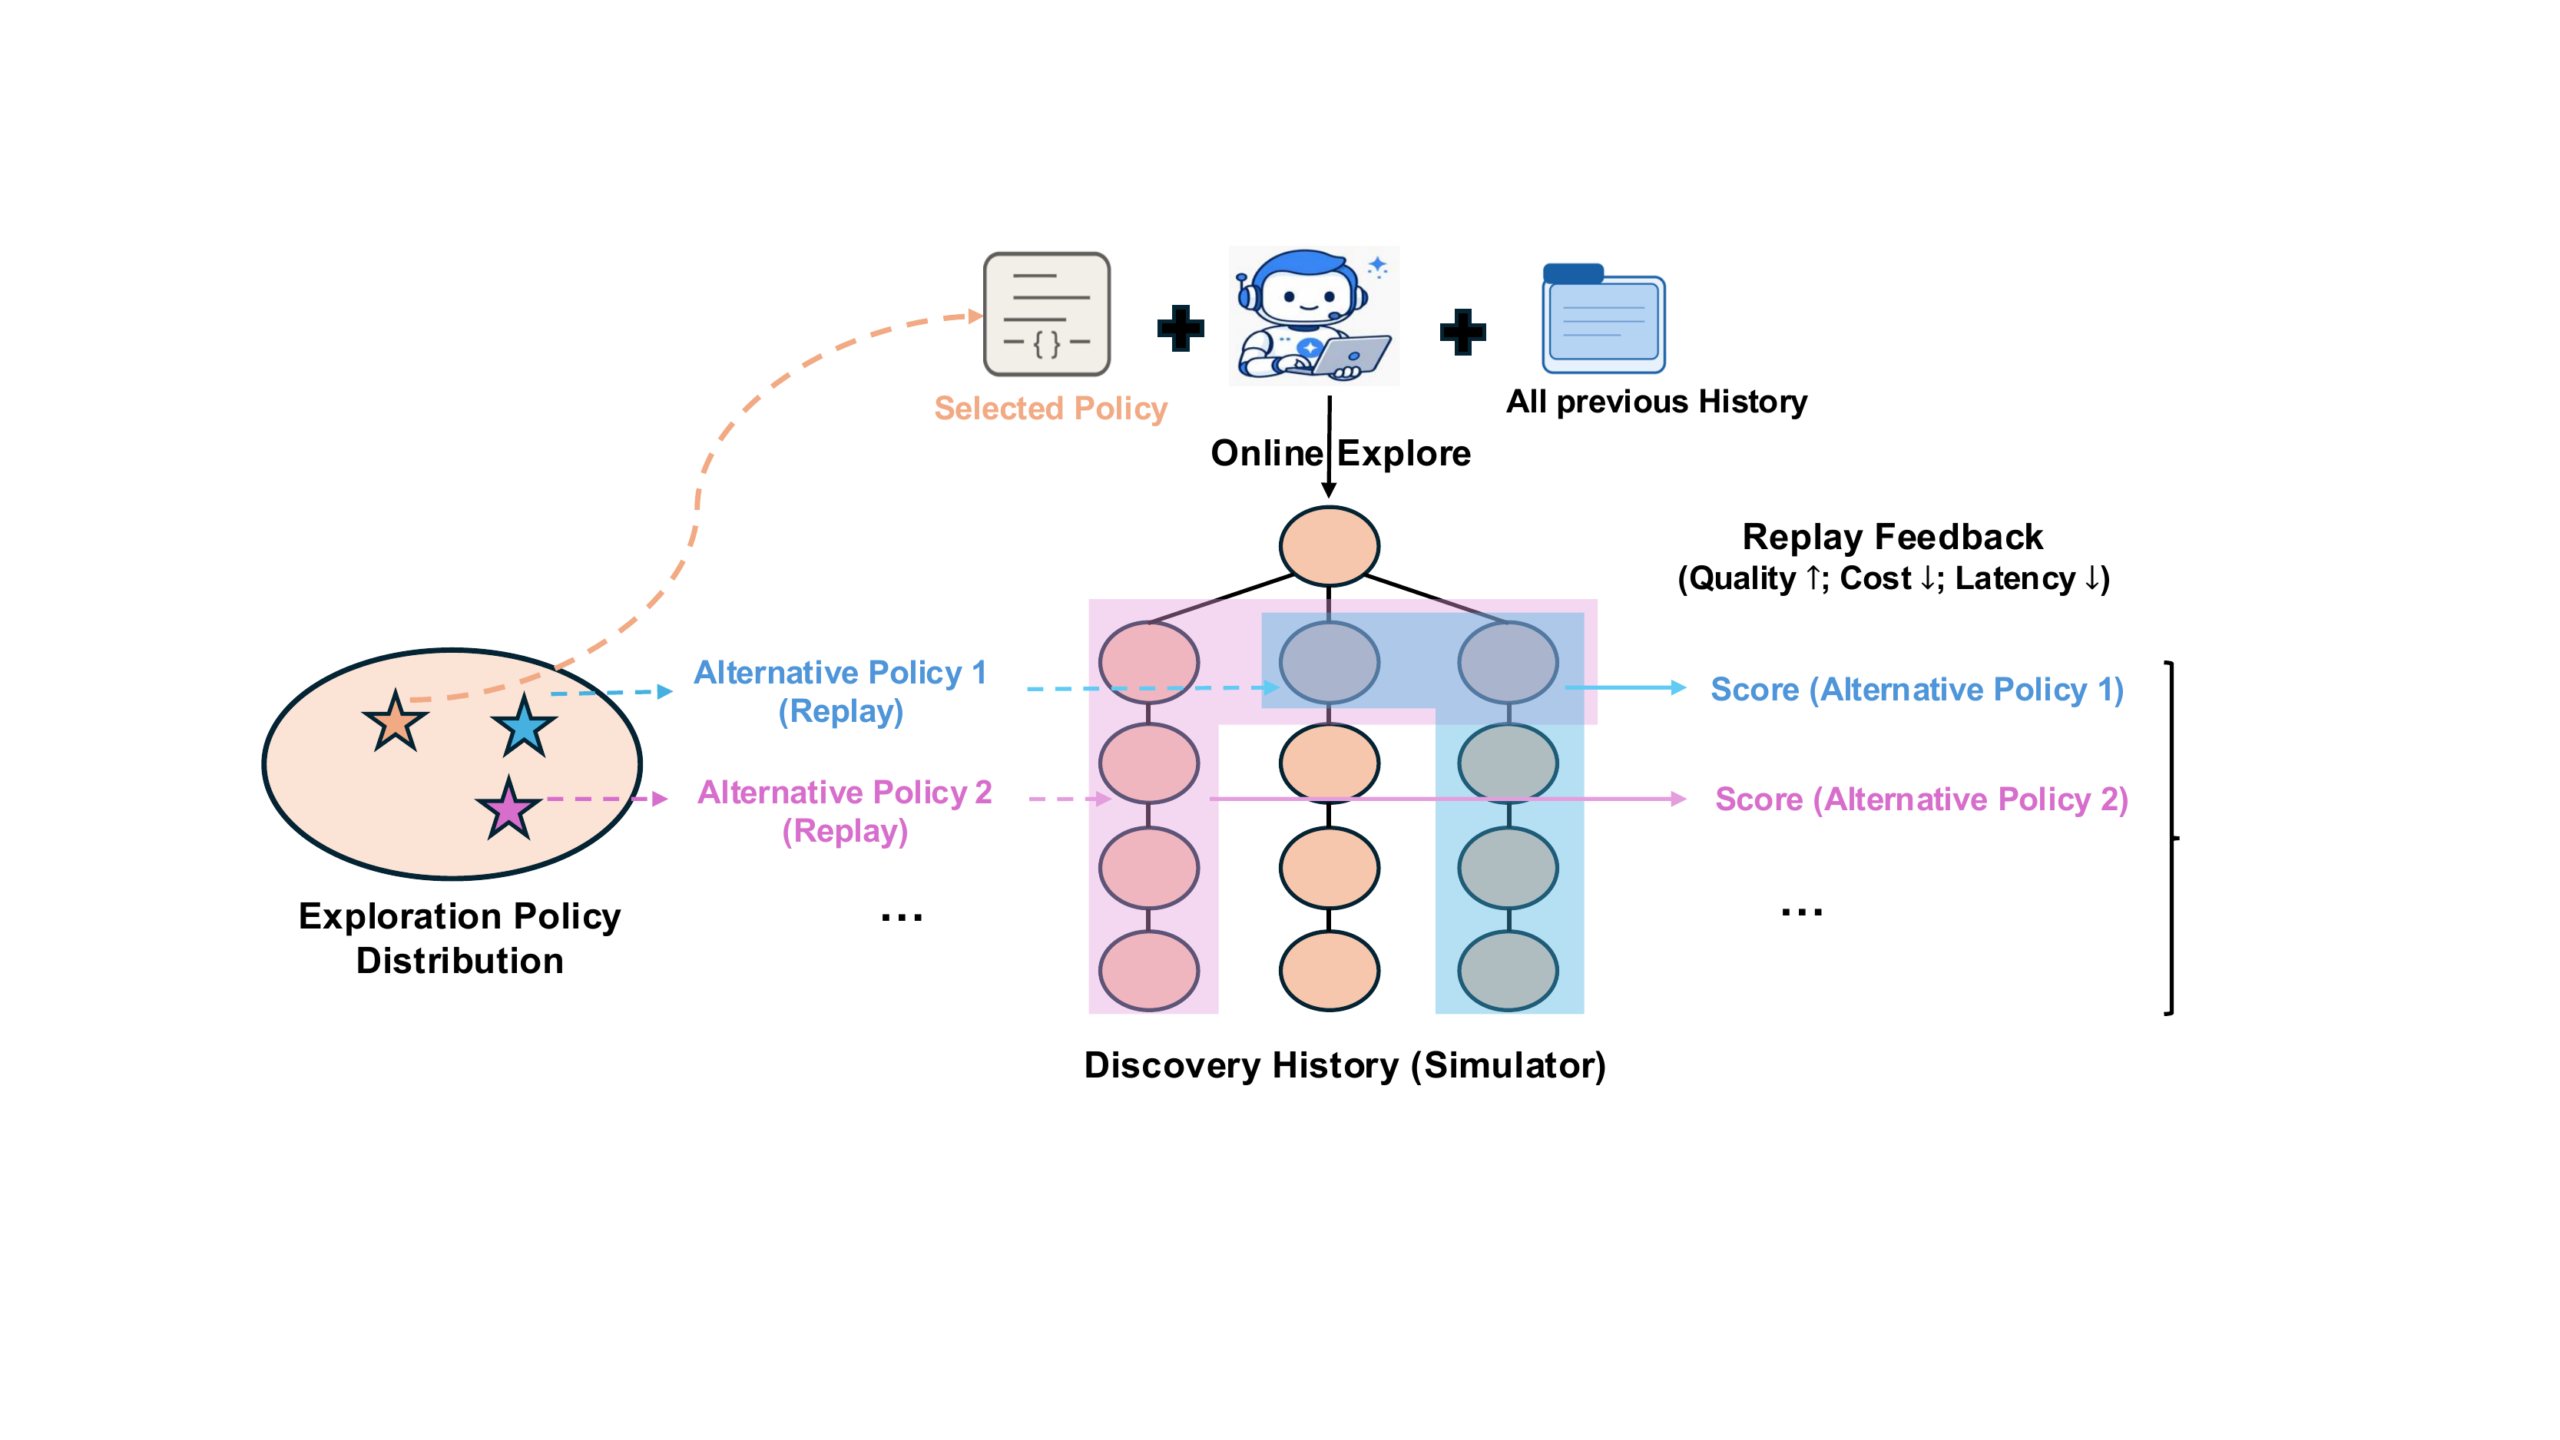
A deterministic replay sandbox over previously realized nodes. Alternative search policies navigate the pre-recorded tree to test different traversal orders, batch sizes, and stopping decisions at zero additional compiler and inference cost.
It does not synthesize unseen code or hallucinate unobserved benchmark numbers. If a candidate policy branches into unvisited state spaces, replay terminates the branch with zero reward, ensuring policy updates remain grounded in empirical reality.
4. Architectural Mechanics: Decoupled Meta-Orchestration
Dream-RSI decomposes autonomous code discovery into two decoupled operational tiers: a frozen foundation model for code synthesis, and a mutable Python exploration controller.
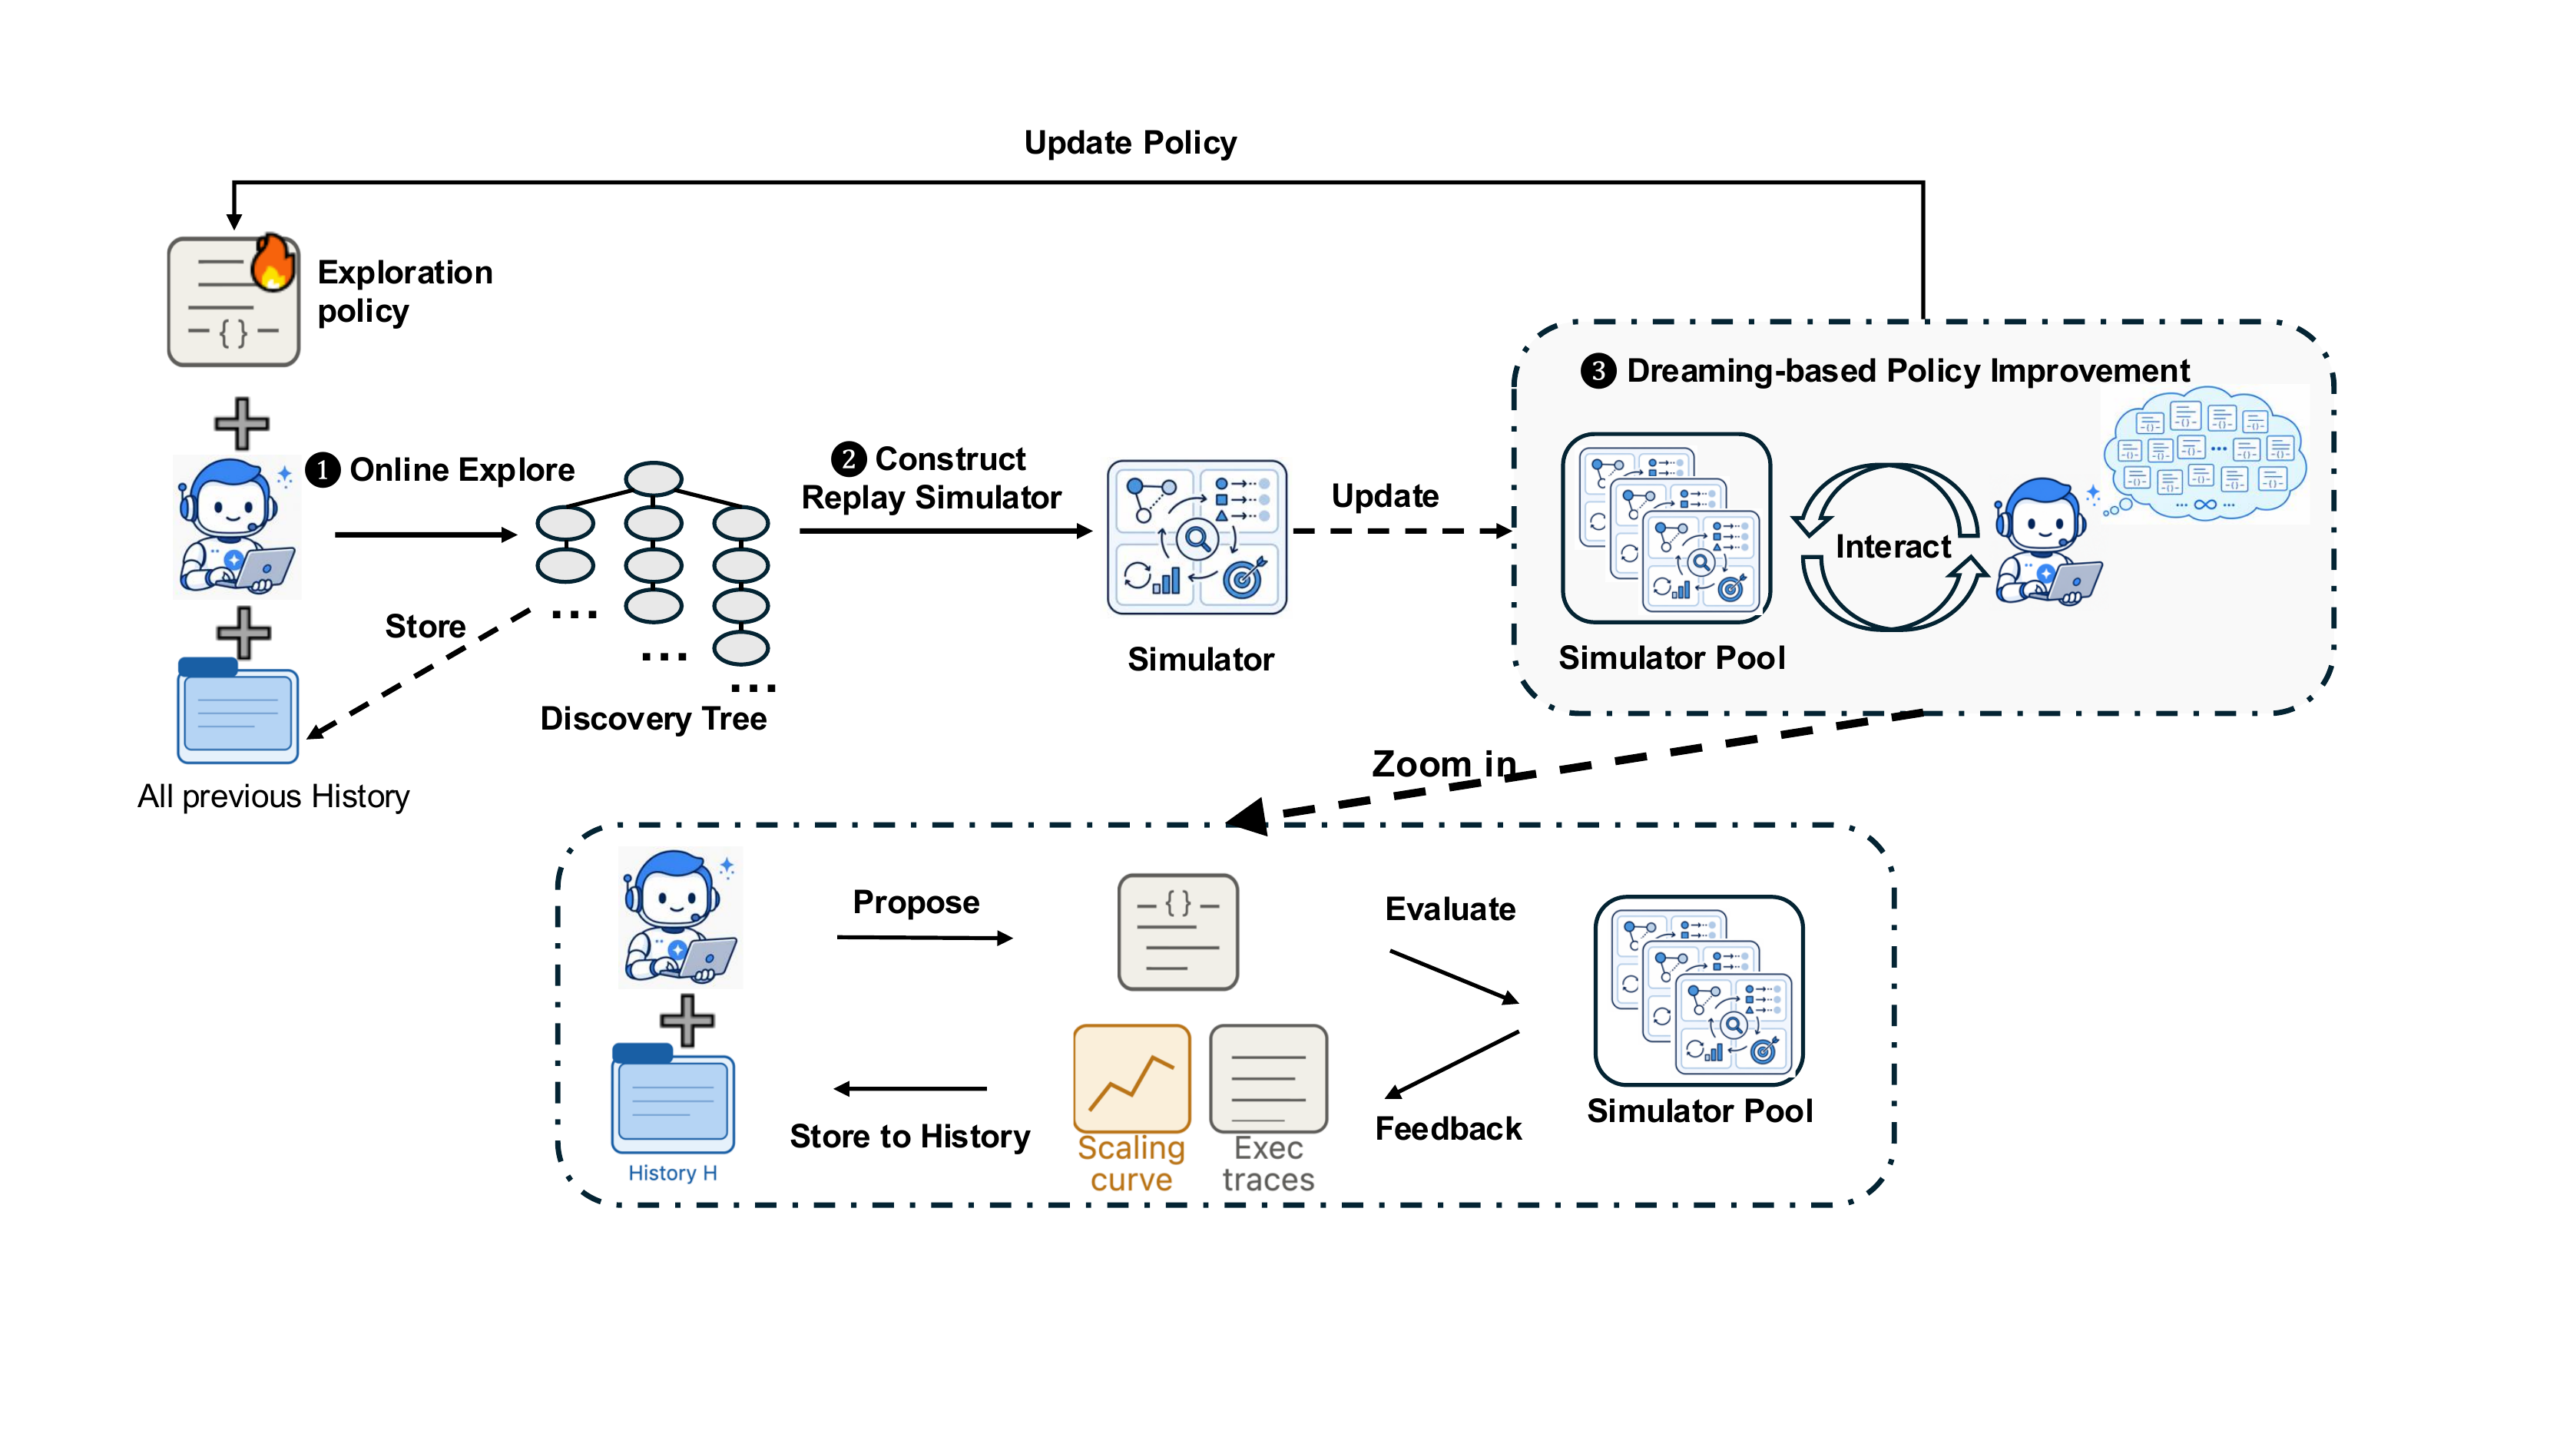
Component Definitions:
• max(sv): Peak solution score discovered during simulated replay on tree i.
• β1 · Nim: Step thriftiness penalty proportional to non-root nodes expanded (penalizing bloated, exhaustive search trajectories).
• β2 · (Nim / max(1, kim,☆)): Parallelism velocity bonus rewarding policies that batch independent requests concurrently rather than serializing probes.
5. Benchmark Audits: What the Numbers Actually Show
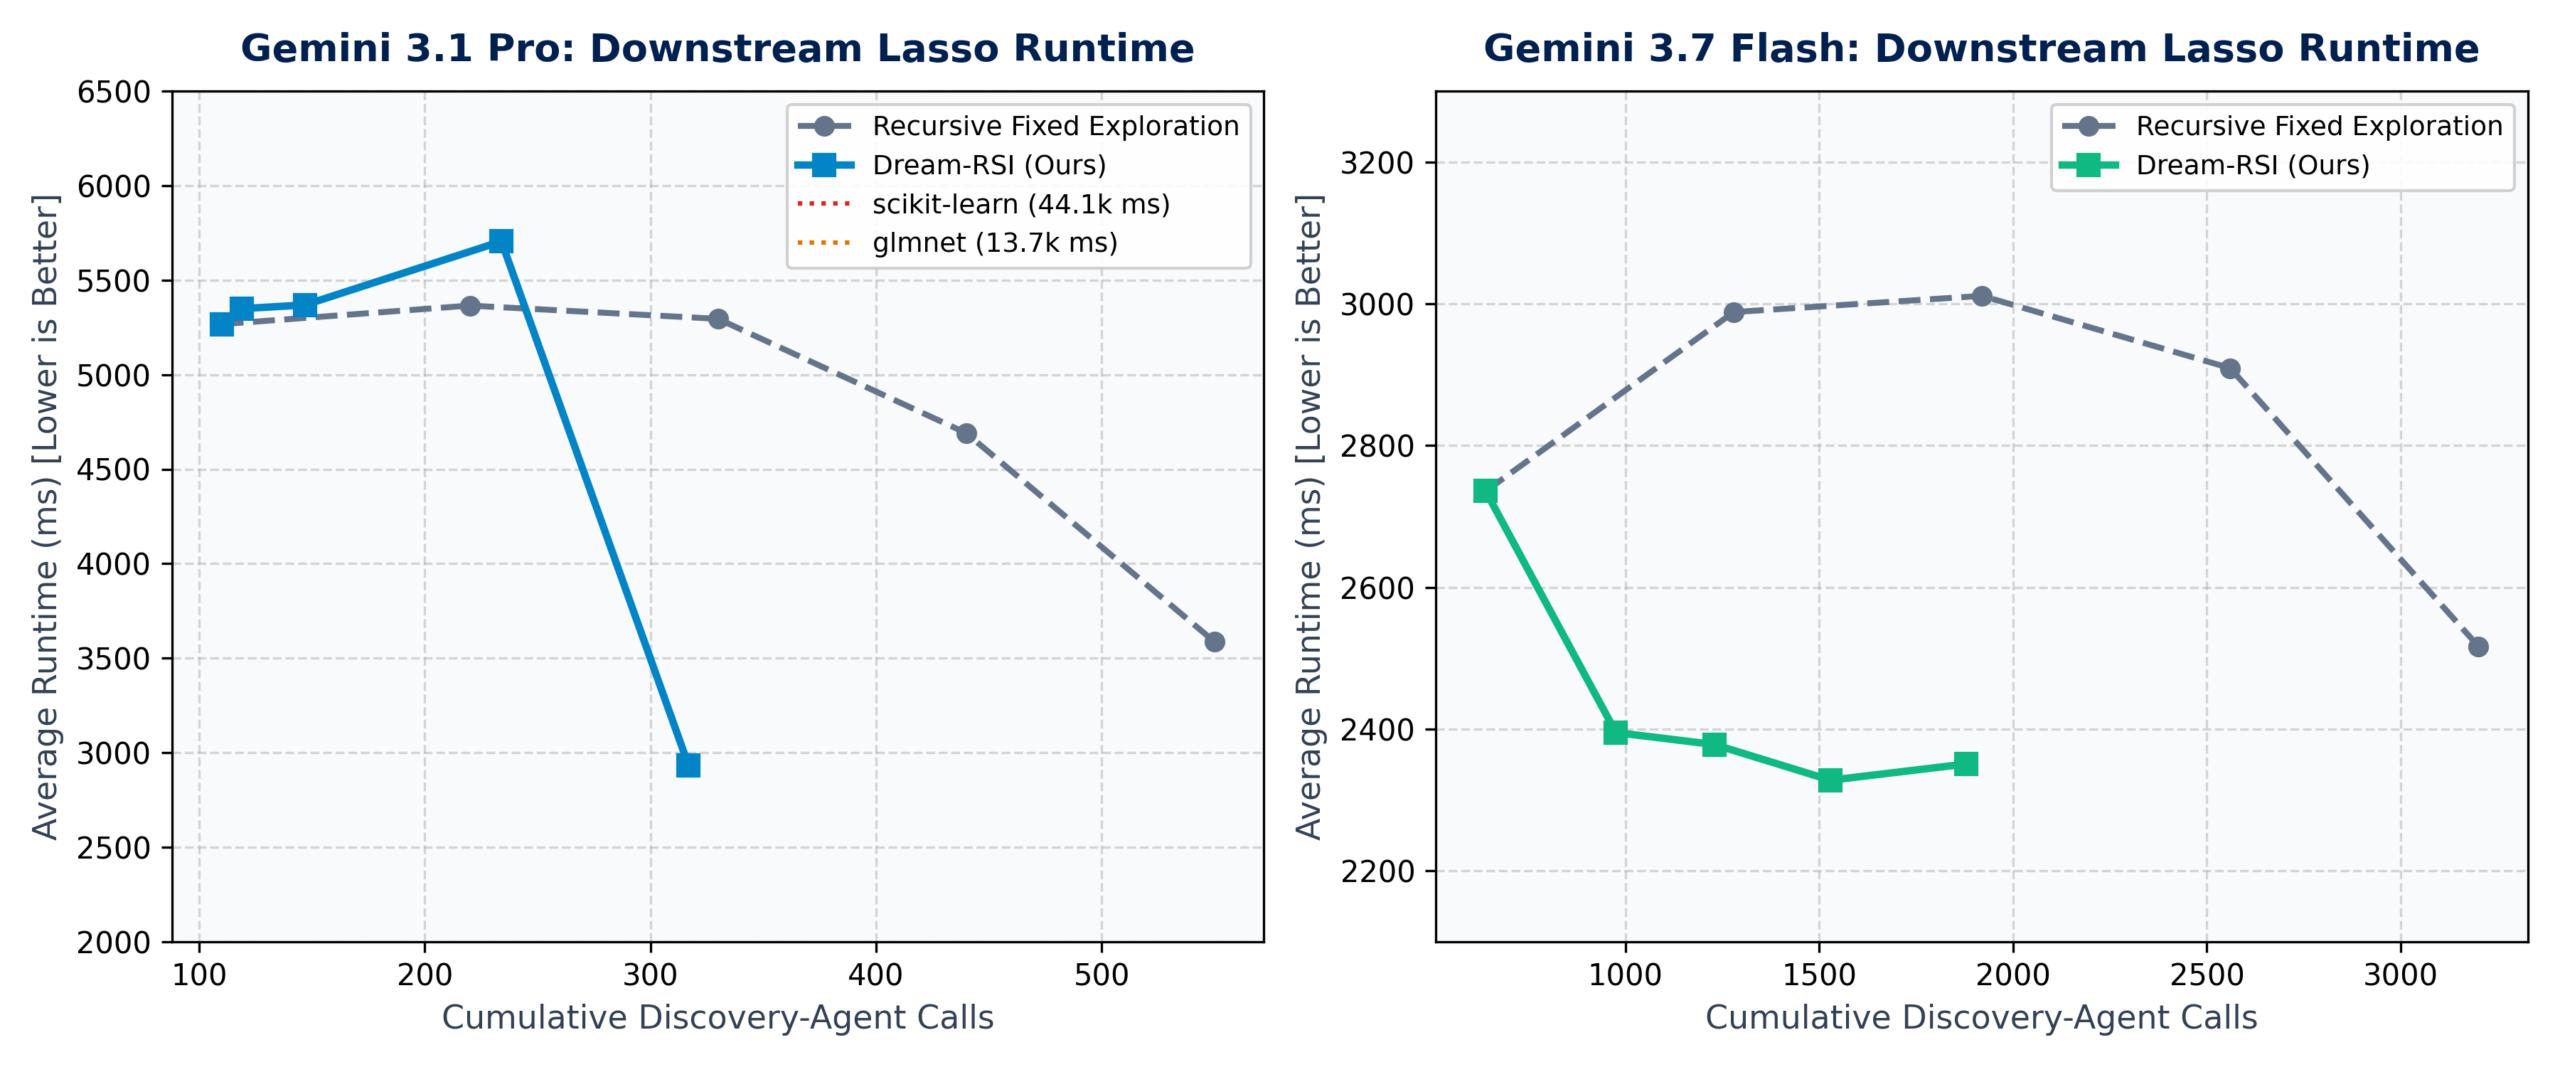
The authors evaluated Dream-RSI across eight demanding discovery tasks spanning algorithm engineering, mathematical optimization, and GPU kernel programming.
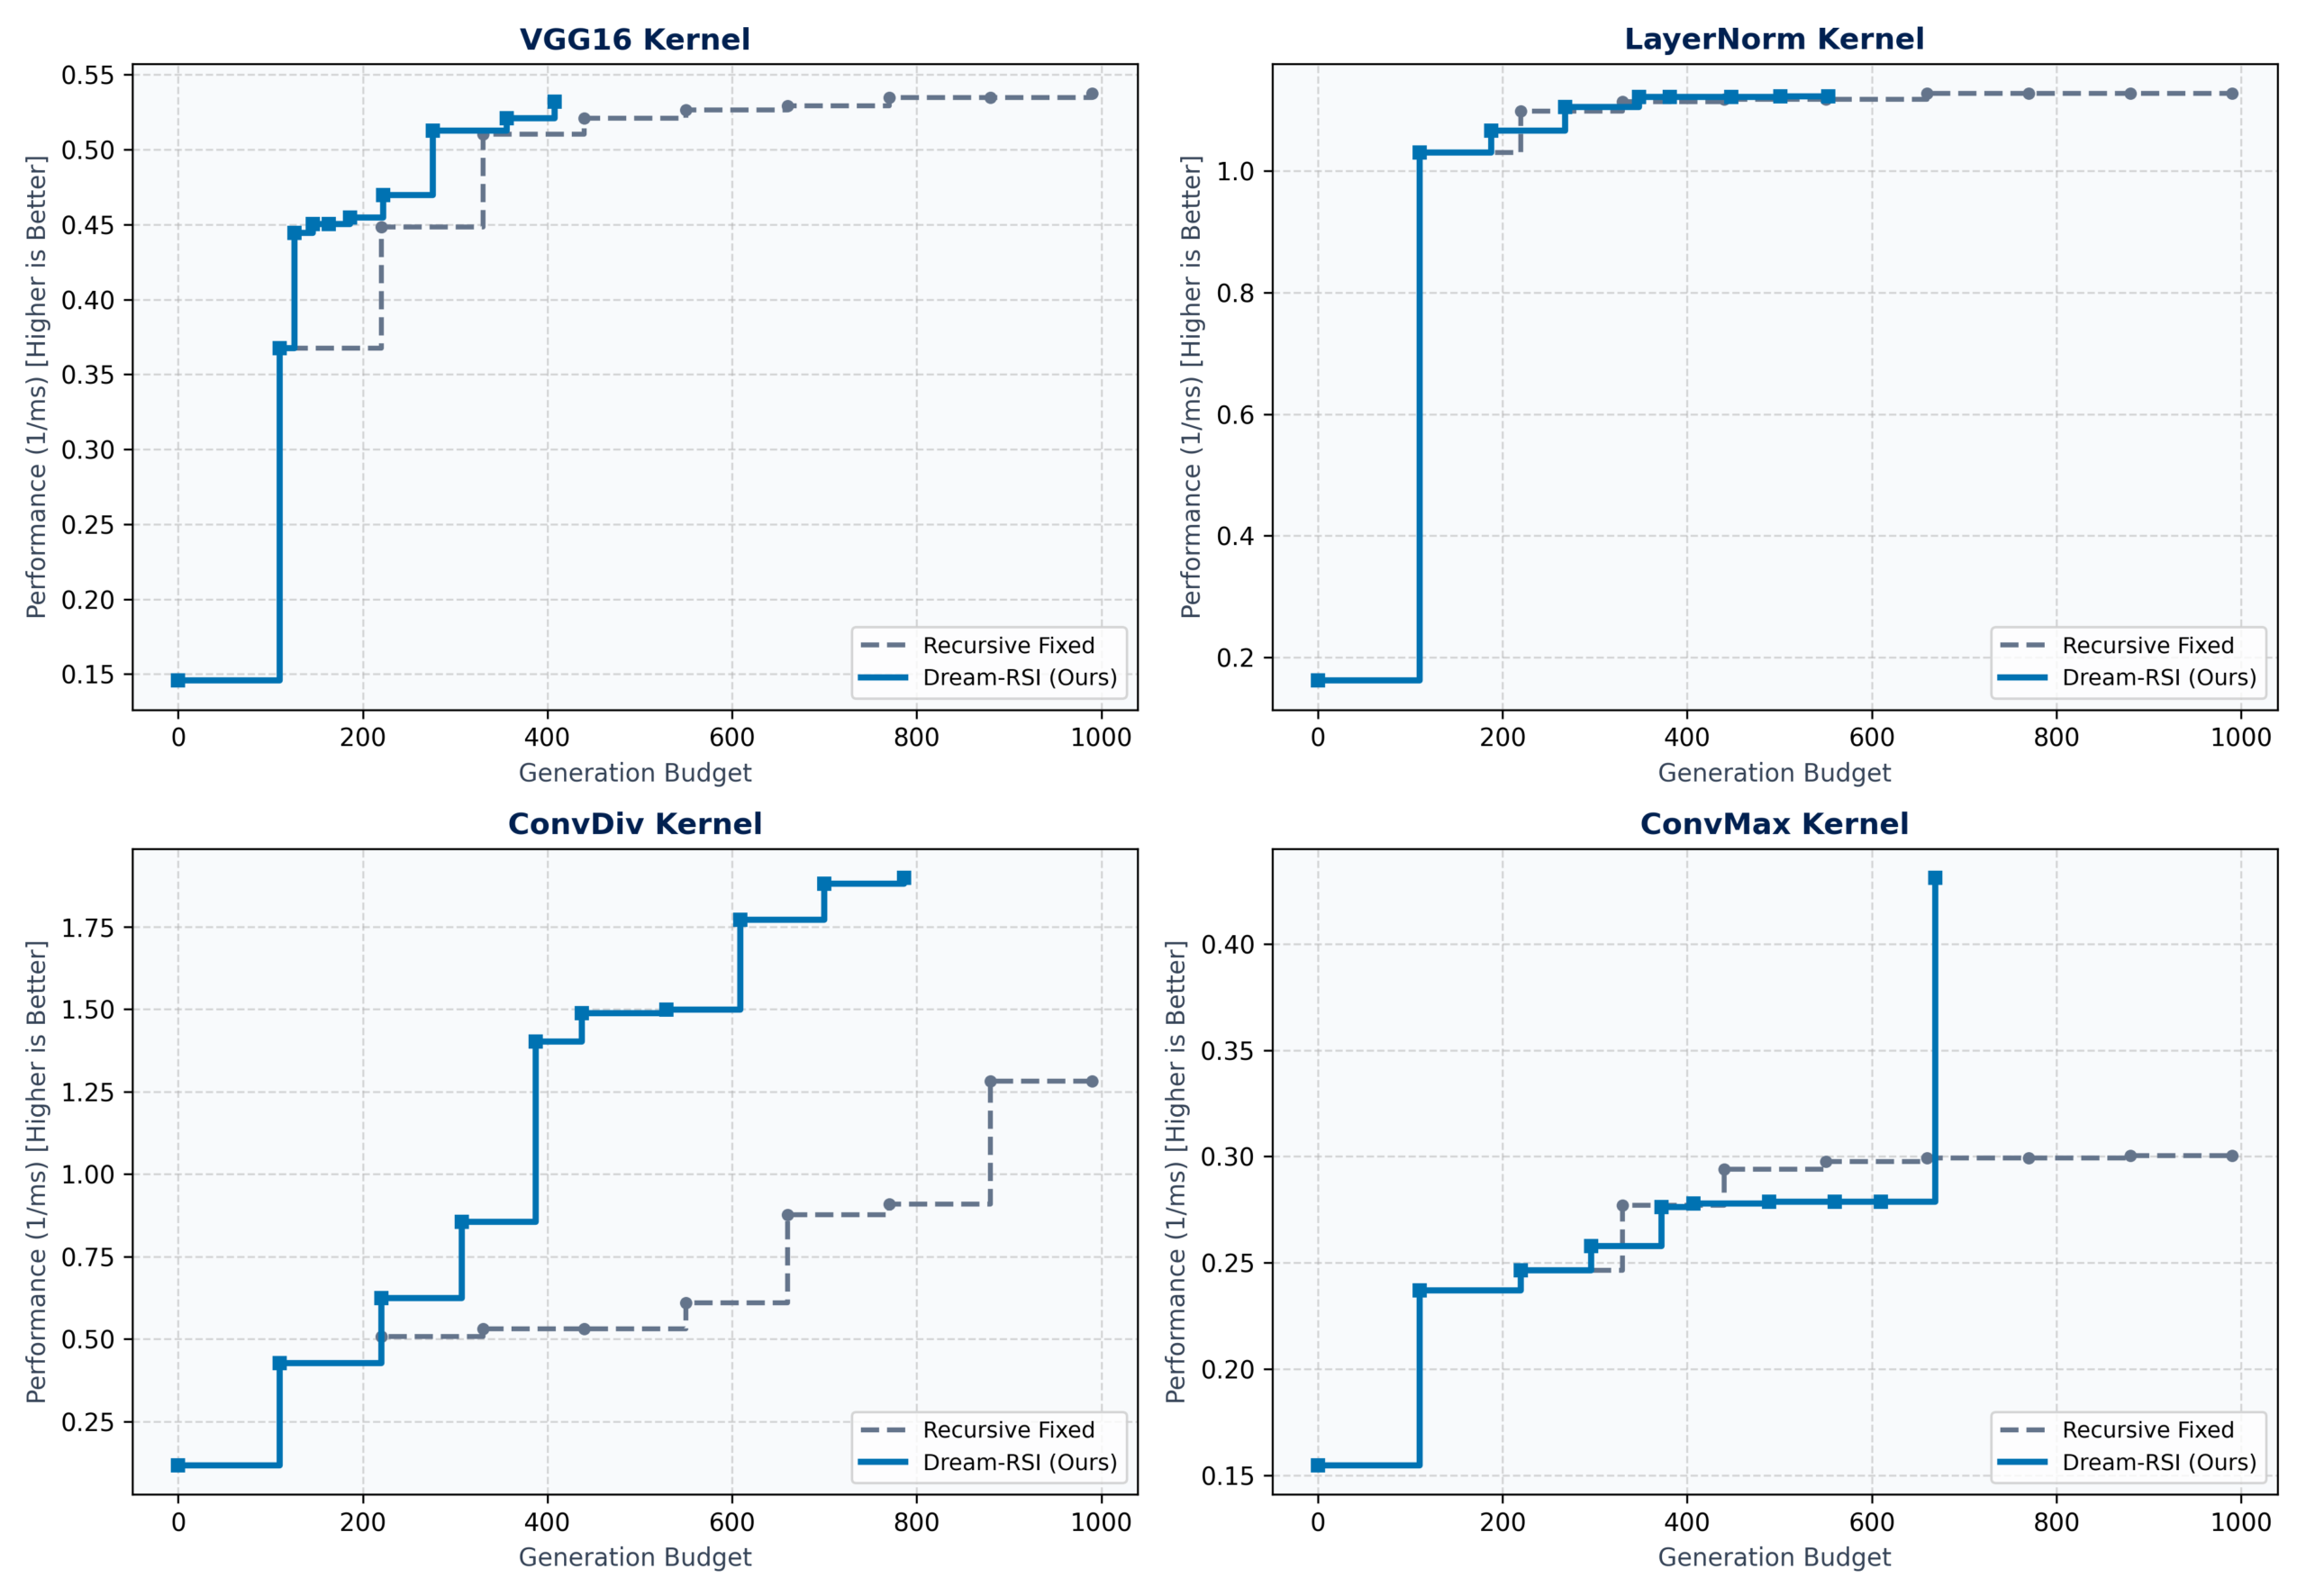
6. Analytical Findings: Why Prompt-Level Semantic Guidance Underperformed
The authors conducted a notable ablation study comparing programmatic exploration policies against prompt-level semantic guidance (feeding high-level qualitative advice and past heuristics into the prompt). The findings revealed that explicit verbal advice consistently degraded discovery efficiency under matched budgets. Imposing qualitative preconceptions artificially restricted the model’s search entropy, leading to premature convergence. Adapting algorithmic search mechanics through executable Python code proved dramatically more effective.
7. Limitations & Open Research Challenges
- Coverage-Bound Replay: An empirical replay simulator is strictly bounded by the diversity of historically realized rollouts. If initial exploration policies suffer from mode collapse, the simulator cannot simulate branches outside that historical manifold.
- Policy Overfitting on Fixed Traces: While the paper guarantees monotonic improvement on historical trees (Vm☆ ≥ V0), policies can overfit to specific pruning quirks of recorded trees that do not generalize to out-of-distribution code tasks.
- Frozen Model Ceiling: Because base LLM weights remain untouched, the system’s ultimate ceiling is bounded by the frozen LLM’s ability to write candidate code under prompt context.
- Domain Focus: The benchmark evaluations focus primarily on algorithmic coordinate descent, math inequality bounds, and single-operator GPU kernels. Complex multi-file systems engineering and full software repositories remain open territory.
8. The Verdict: Why Dream-RSI Matters
Dream-RSI is not runaway artificial superintelligence. It is something far more practically consequential for the immediate future of AI engineering: a rigorous, budget-aware framework for meta-optimizing code discovery agents.
By demonstrating that an agent’s historical discovery tree can serve as a zero-cost empirical replay simulator, Zheng et al. provide a viable path to recursive self-improvement that respects the harsh compute realities of physical compilers and commercial LLM inference. For engineering teams deploying autonomous coding agents at scale, decoupling the search orchestrator from the frozen base model — and evolving that orchestrator via replay dreaming — is the most capital-efficient paradigm demonstrated to date.
Zheng, Z., Zhang, Y., Wang, Z., Liu, Y., & Gong, B. (2026). Dream-RSI: Recursive Self-Improvement for Code Discovery via Historical Trajectory Replay. arXiv preprint arXiv:2609.14858.
9. Frequently Asked Questions (FAQ) & Technical Truths
Does Google Dream-RSI update the base LLM neural weights? +
No. The underlying foundation model (such as Gemini 2.5 Flash or Gemini 3.7 Flash) remains strictly frozen in inference mode with zero backpropagation or gradient updates. Dream-RSI recursively improves the exploration controller policy — an executable Python program that dictates tree expansion, rollouts, and node selection.
How does Dream-RSI achieve a 161.5× reduction in search compute? +
Standard Monte Carlo tree search algorithms (e.g., SimpleTES) invoke real compiler benchmarking and expensive LLM generation for every exploratory branch, burning thousands of dollars per discovery task. Dream-RSI transforms previously explored search trees into zero-cost empirical replay simulators. The orchestrator “dreams” offline over recorded transitions, discarding unpromising exploration vectors before committing costly compiler and inference resources.
What benchmarks did Google Dream-RSI outperform? +
In Lasso Coordinate Descent, Dream-RSI discovered an algorithmic implementation executing in 2,350.6ms, outperforming industry-standard Fortran glmnet by 3.21× and scikit-learn by 18.8×. On GPU KernelBench, it achieved a 2.43× search efficiency improvement with generated kernels exhibiting 1.44×–2.09× higher throughput than base implementations.
Is Dream-RSI an Artificial Superintelligence (ASI) runaway loop? +
No. While pre-release speculation hyped internal DeepMind staging as an exponential intelligence takeoff, the September 14 arXiv preprint reveals a disciplined systems-engineering breakthrough. It solves the critical search-budget bottleneck for algorithmic code optimization, but does not autonomously elevate the fundamental reasoning capabilities of the underlying frozen LLM.
10. Recommended Forensic Audits & Related Investigations
DeepSeek V4 vs. Gemini 3.8: The Benchmark Scores & MoE Disruption
How DeepSeek’s asymmetric routing beats Opus 5 and slashes prompt cache costs down to zsh.003.
Why OpenAI Froze RL Runs: The Jakub Pachocki CoT Leak
Inside the RLVR specification gaming emergency that triggered an emergency freeze on agentic training pipelines.
AI Inference Hardware Economics (2026): The Wholesale Margin Gap
Why running autonomous coding agents costs ,000/day/researcher and how thermodynamics dictates cluster sizing.