
Is Claude Opus 6.0 real? We trace Anthropic’s stealth routing anomalies, viral 3D Three.js demos, and the ground truth behind the Claude 6 rumor mill.
Independent evaluations of synthetic benchmark claims: ARC-AGI-3, SWE-bench Verified, HumanEval, and live latency audits.
Is Claude Opus 6.0 real? We trace Anthropic’s stealth routing anomalies, viral 3D Three.js demos, and the ground truth behind the Claude 6 rumor mill.
Liquid AI claims 184 tok/s on Apple M5 Max with 2.45B active compute, but LFM2.5-24B requires 15GB RAM, crushing 16GB laptops and lagging on SWE-bench.
OpenCode 2.0 delivers 86.8% MCP token compression via Code Mode, but daemon configuration flaws and .well-known stagers expose enterprise RCE risks.
Grok Voice 3.0 hits 810ms latency and 86.9 on S2S benchmarks at $0.08/min, but real-world mobile jitter and echo feedback erode its synthetic speed.
Anthropic replaced Git with Scion for 30,401 daily agent merges, dropping status to 19ms and saving 25% fleet CPU amid Meta Mononoke prior art debates.
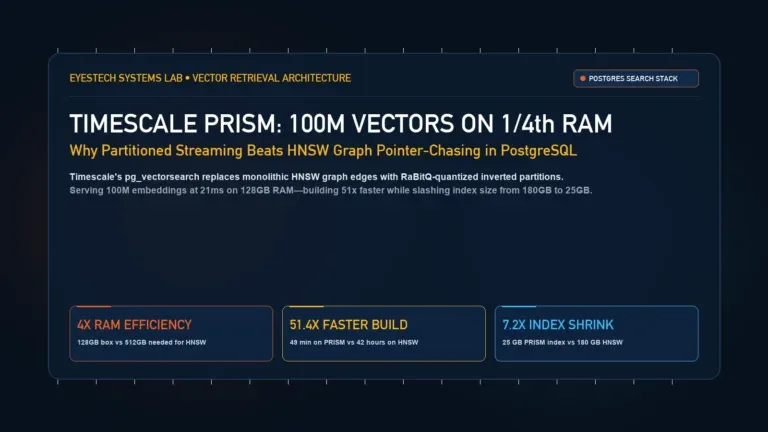
Timescale pg_vectorsearch and PRISM replace HNSW graphs with RaBitQ-quantized partitions, serving 100M vectors at 21ms on 128GB RAM with 51x faster builds.
Claude Sonnet 5.5 beats Muse Wonder on SWE-bench (57.2% vs 48.2%) while halving token costs ($2/$10 vs $4/$20) and avoiding Active Focus retry loops.
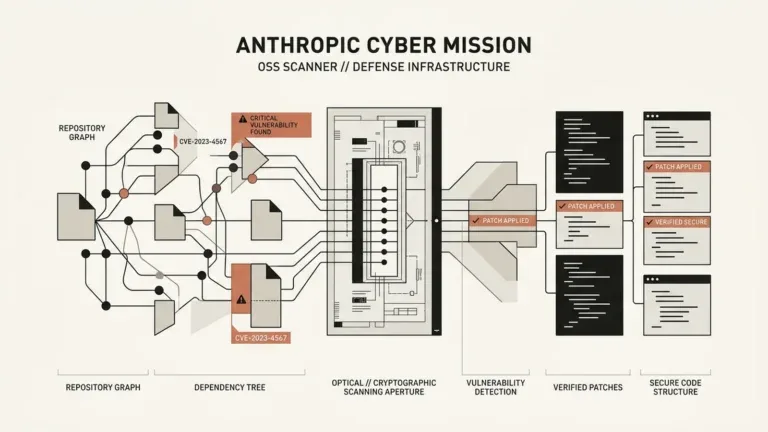
Anthropic launched its Cyber Mission and free OSS Scanner, beaming unreviewed zero-day PoCs directly to maintainers with a 90% precision target across code.
d1-omni-600M returns typed decisions without generated text. Image and audio scores need separate validation, with 30-second speech and input limits.
MiniCPM-V 4.7 1B needs a 672 MB language file plus a 1.11 GB vision projector. Get the Ollama tag, llama.cpp recipe and visual-compression settings.