
GPT-6.1 Sol cache reads cost $0.10 per million tokens, but writes cost $2.50. Worked examples show when reuse lowers the complete request bill.
KV-cache discount mechanics, context window compaction ROI, enterprise AI FinOps, and inference budget forecasting.
GPT-6.1 Sol cache reads cost $0.10 per million tokens, but writes cost $2.50. Worked examples show when reuse lowers the complete request bill.
Tsinghua University’s ICLR 2026 Cache-to-Cache (C2C) neural fuser eliminates inter-agent text generation to accelerate multi-LLM inference by…
Benchmarking Apple M5 Max/Ultra Mac Studio (oMLX, Qwen 3.8 27B, Bonsai 2 27B, qwen-image-2.1) against Thunderobot’s Ryzen AI Max+ 395 120B MoE SSD laptop.
Claude Sonnet 5.5 leaks reveal Anthropic’s roadmap. See Theo’s GPT-6 Astra audit, the 4.4x token bloat trap, and Jev routing cutting agent costs by 80%.
Gemini 3.8 Flash takes on GPT-6 Luna. Compare 73.7% vs 66.6% DeepSWE, $0.10/M token pricing, TPU v6e vs Astra routing, and 2.8% deception rates.
OpenAI drops GPT-6 Sol at $2/M input with 50% fewer errors, hitting 68.8% on DeepSWE v1.1 to match Claude Fable 5 at 80% lower cost. Full tech breakdown.
OpenAI releases GPT-6 Luna at $0.10/M input and $0.50/M output, scoring 66.6% on DeepSWE to match Claude Opus 5 at 93% lower per-task operational cost.
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
Reasoning token cost decides whether test-time AI is an upgrade or an expensive reliability problem. This audit…
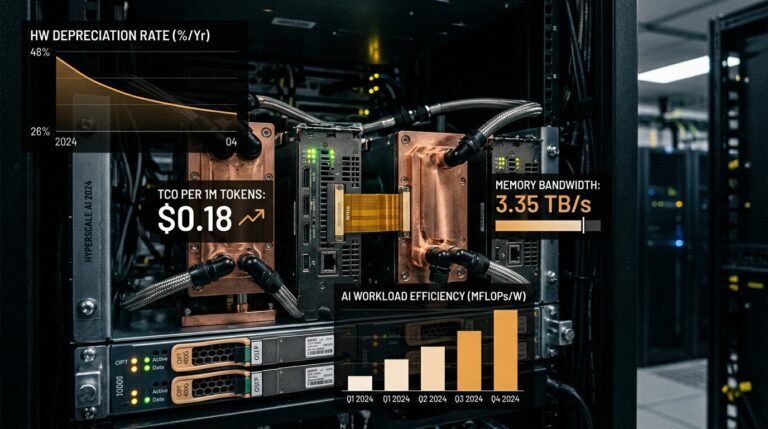
55+ verified benchmarks on AI inference cost, latency, GPU cluster failure rates, and memory bandwidth walls. Download raw 2026 telemetry data.