



onPanda Cuts Annotation Time by Correcting the First Bad Token
onPanda is an open-source annotation interface that lets a human replace the first wrong token in a model response, then…
EyesTech editorial profile covering inference economics. Articles distinguish source reporting, analysis and documented tests. EyesTech uses AI assistance; this coverage profile is not a verified professional résumé. Corrections: https://eyestech.in/contact/
onPanda is an open-source annotation interface that lets a human replace the first wrong token in a model response, then…
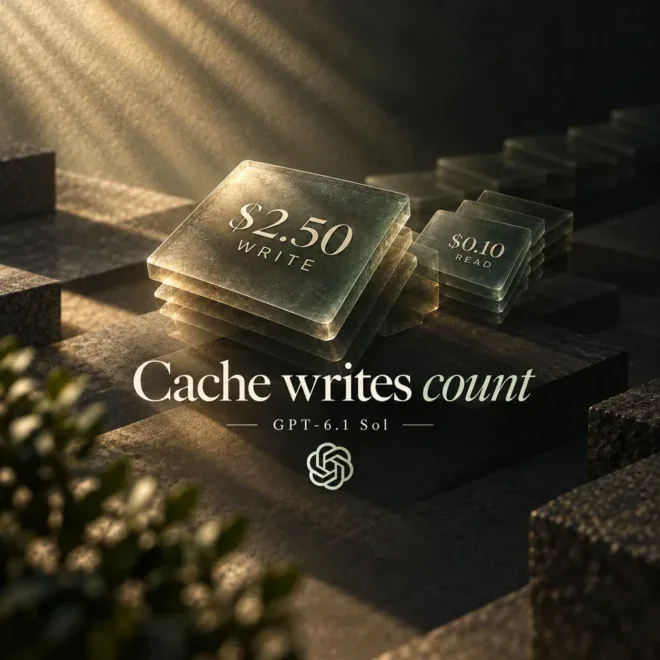
GPT-6.1 Sol cache reads cost $0.10 per million tokens, but writes cost $2.50. Worked examples show when reuse lowers the complete request bill.
OpenAI reopens its $200 Pro plan with a 50% cut in API spend value, removes the 5-hour limit, and splits throughput between Sol and flagship Astra.
55+ verified benchmarks on AI inference cost, latency, GPU cluster failure rates, and memory bandwidth walls. Download raw 2026 telemetry data.
Forensic investigation into DeepSeek’s unit economics: why no Western cloud could match the pre-August $0.28 price, why DeepSeek temporarily hiked rates on August 16 after an 8-trillion-token surge, how V4.1-Flash’s 890-byte CED attention enables Western startups to hit $0.66 profitably today, and why American Big Tech hyperscalers charge a 4,000% markup to service legacy debt.

OpenAI has paused new sign-ups and upgrades for the $200/mo ChatGPT Pro tier as power users leveraging the 20X token capacity multiplier on GPT-6 Astra burn through 15M to 30M reasoning tokens per month, creating up to a -$1,240/month deficit per seat.
Cursor pricing in 2026, explained: plans ($20 Pro, $60 Pro+, $200 Ultra, ₹649 Start), fast requests vs slow queues, API credits, overages, and practical ways to control your bill.