


How to Install and Run MiniCPM-V 4.7 1B in Ollama (Setup Guide)
MiniCPM-V 4.7 1B needs a 672 MB language file plus a 1.11 GB vision projector. Get the Ollama tag, llama.cpp recipe and visual-compression settings.
EyesTech Local Model Usability Desk, focusing on consumer hardware quantization, on-device GGUF execution, and edge homelab deployments. Editorial Standards: https://eyestech.in/editorial-policy/
MiniCPM-V 4.7 1B needs a 672 MB language file plus a 1.11 GB vision projector. Get the Ollama tag, llama.cpp recipe and visual-compression settings.
MiniCPM-V 4.7 reports 13+ tokens/s in 3GB phone memory. Expert loading, quantization and speculation explain why that is not its total weight size.
Saluki packs Qwen3.8-27B into 7.89GB. Its 88/120 tool score hides lost and gained tasks, parser sensitivity and memory costs beyond the model file.
Strata runs 125B Qwen3.8-Flash-Next on 12GB VRAM at 45 tok/s using predictive expert prefetching and io_uring. Here is the PCIe math and setup.
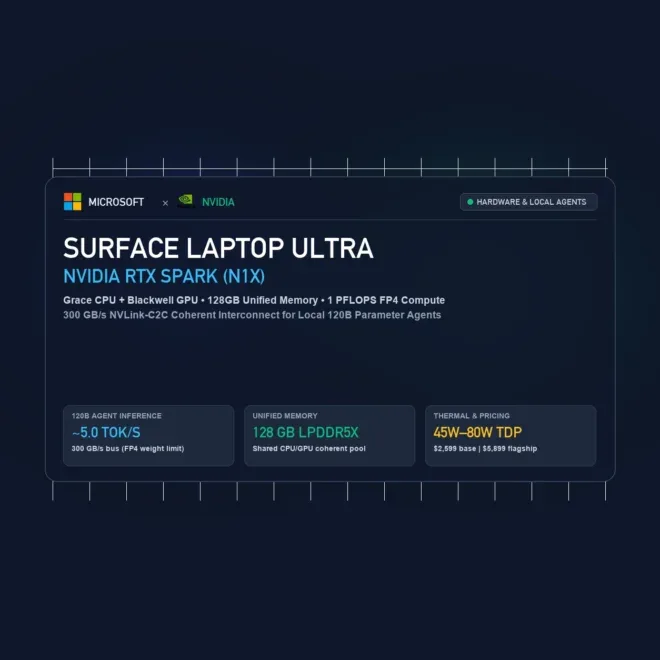
Microsoft and NVIDIA’s Surface Laptop Ultra pairs an Arm Grace CPU and Blackwell GPU via 300 GB/s NVLink-C2C. Here is what 128GB unified memory and 1 PFLOPS FP4 mean for 120B local agents.
Janus bundles llama.cpp Vulkan DLLs into a 50MB Go binary for cross-vendor GGUF local LLM inference across AMD, Intel, and Nvidia GPUs without Python or Docker.
Backblaze reports 1.73% annualized failures for Q2 2026. Drive-days, fleet age and sample size explain why that figure is not a home-NAS forecast.
China Telecom’s Xing4.0-29B-A4B activates about 4 billion parameters for each token, but it stores 29 billion parameters in total. That…
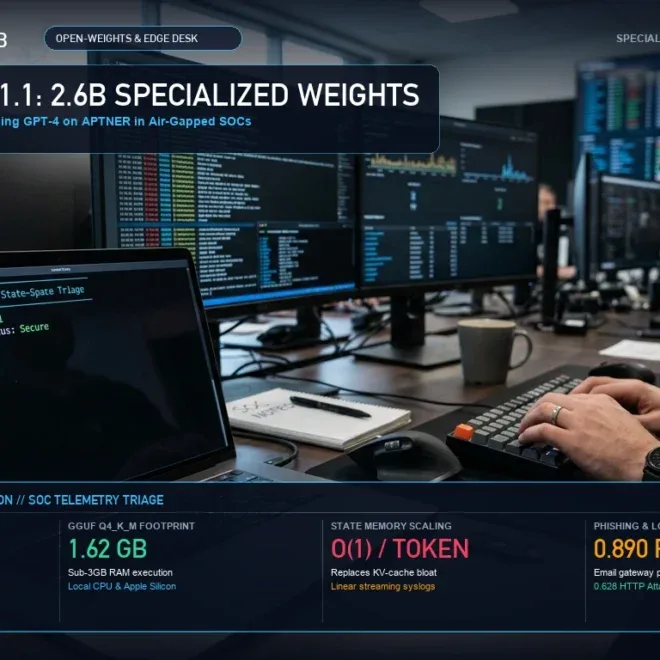
Cyber-Prime 1.1 is a specialized 2.6-billion-parameter language model developed by security researcher Akahsizrr. Built directly on Liquid AI’s Liquid Foundation…
Benchmarking Apple M5 Max/Ultra Mac Studio (oMLX, Qwen 3.8 27B, Bonsai 2 27B, qwen-image-2.1) against Thunderobot’s Ryzen AI Max+ 395 120B MoE SSD laptop.