



In autonomous agentic coding, the most expensive mistake is assigning frontier reasoning models to operational plumbing. On…
In autonomous agentic coding, the most expensive mistake is assigning frontier reasoning models to operational plumbing. On…
OpenAI’s GPT-6.1 Sol matches flagship Astra on DeepSWE v1.1 at $0.65 per task—a 7x cost reduction—while cutting autonomous computer-use safety violations from 17.4% to 4.3% and dropping cached input pricing to $0.10/1M tokens.
GPT-6 Luna is free on Freebuff for eligible users. Here’s the five-hour catch, how to check your account, start coding, and protect private code.
OpenAI GPT-6 Luna faces Xiaomi MiMo-V2.6-Pro. Compare 71.9% DeepSWE, $0.10/M tokens, 1.02T open MoE architecture, and enterprise TCO economics.
OpenAI drops GPT-6 Sol at $2/M input with 50% fewer errors, hitting 68.8% on DeepSWE v1.1 to match Claude Fable 5 at 80% lower cost. Full tech breakdown.
OpenAI releases GPT-6 Luna at $0.10/M input and $0.50/M output, scoring 66.6% on DeepSWE to match Claude Opus 5 at 93% lower per-task operational cost.
DeepSeek V5 leaks claim 78.6% DeepSWE and $0.20/M tokens vs Astra’s $50. Forensic benchmark audit, hardware sizing, and enterprise deployment guide.
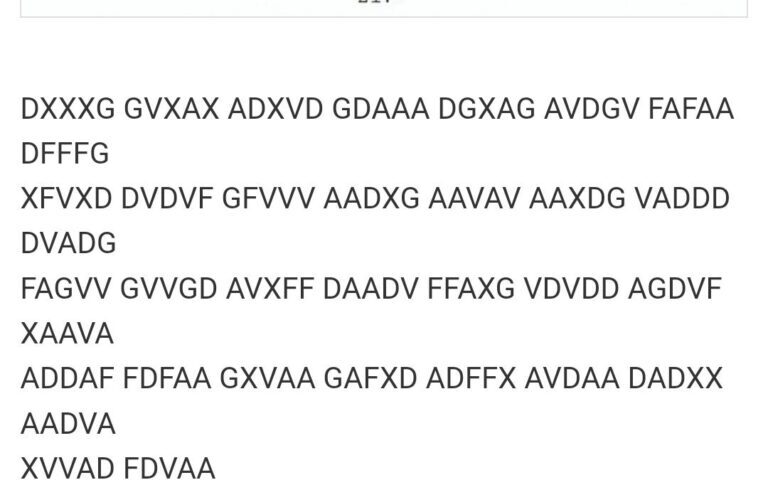
GPT-6 Astra cracked an unsolved 1918 German ADFGVX cipher using historical monograph search and key transposition in 170 chars. Here is the technical audit.
Leaked GPT-6 Sol generates 72k tokens in 9 mins—3x faster than Astra. Here is why titan-alpha unlocks applied recursive self-improvement without runaway AGI.
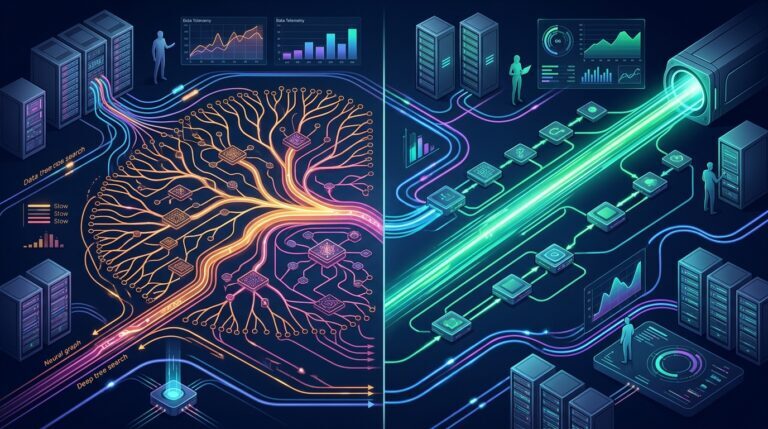
Why running autonomous coding agents on GPT-6 Astra leads to 19-minute execution freezes, and how leaked alpha benchmarks of GPT-6 Sol running 6.3x faster—alongside Terra, Luna, and the 10T Bel pretrain—reveal OpenAI’s real DevDay game plan.

