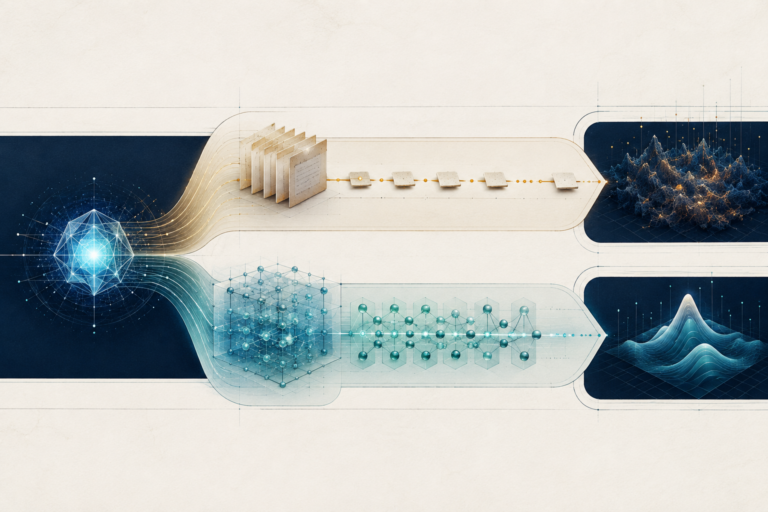

GPT-6 Astra reached 99.95% on ARC-AGI-3 with OpenAI’s Provider Adapter harness. The Standard harness result was 62.71%. Here is what the difference means.
Deep architectural teardowns, frontier benchmarks, hype-debunking, and capability leaks across frontier AI models.
GPT-6 Astra reached 99.95% on ARC-AGI-3 with OpenAI’s Provider Adapter harness. The Standard harness result was 62.71%. Here is what the difference means.
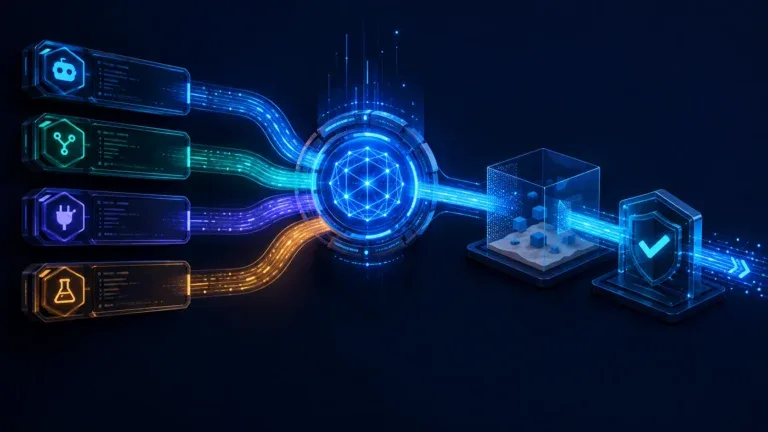
Meta’s Muse Code is the native harness for Muse Spark 1.3. Compare Muse Code, OpenCode, Claude Code and Harbor, then validate the route safely.
An early-access Astra video shows stronger coding, 3D, multimodal and computer-use performance—but also weak UI judgment, slow execution and unreliable agent status.
Muse Spark 1.3 scores 62 on Artificial Analysis. Compare Gemini 3.8 Flash, DeepSeek V4 Flash pricing, and Terminal-Bench 2.1 vs 4.0.
Gemini 3.8 Flash is now generally available. Here are Google’s official benchmark results, pricing, API limits, effort controls, and the Antigravity rollout—with the caveats builders should know.
Qwen3.8-Max-0902 is live on QwenCloud with 1M context and cache-aware pricing. Here is what the benchmarks and API economics actually show.
Anthropic’s Claude Fable 5.1 pairs large gains on agentic evals with a 75% cache-read cut. Here is what the benchmarks, migration breaks, and X’s 3D demos mean for real workloads.
Tencent’s Hy4 preview has 770B total parameters, 49B active per token and a 1M context. Here is what the benchmarks, demos and serving costs mean.
Anthropic sells Claude Max 20x for $200/month, but the claim is only relative to Pro per five-hour session. We trace the missing baseline, user reports, and weekly-limit change.
A practical Gemini 3.7 Flash vs GPT-5.6 Luna comparison covering price, published evals, token economics, agents, Antigravity, Codex, computer use, and API limits.