


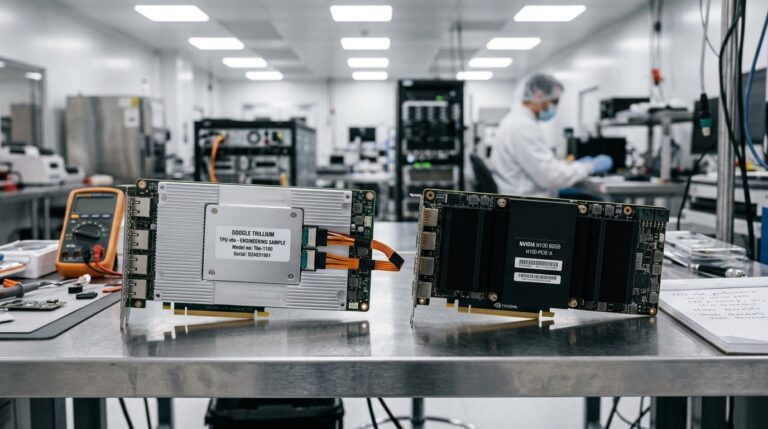

Gemini 3.8 Flash takes on GPT-6 Luna. Compare 73.7% vs 66.6% DeepSWE, $0.10/M token pricing, TPU v6e vs Astra routing, and 2.8% deception rates.
Gemini 3.8 Flash takes on GPT-6 Luna. Compare 73.7% vs 66.6% DeepSWE, $0.10/M token pricing, TPU v6e vs Astra routing, and 2.8% deception rates.
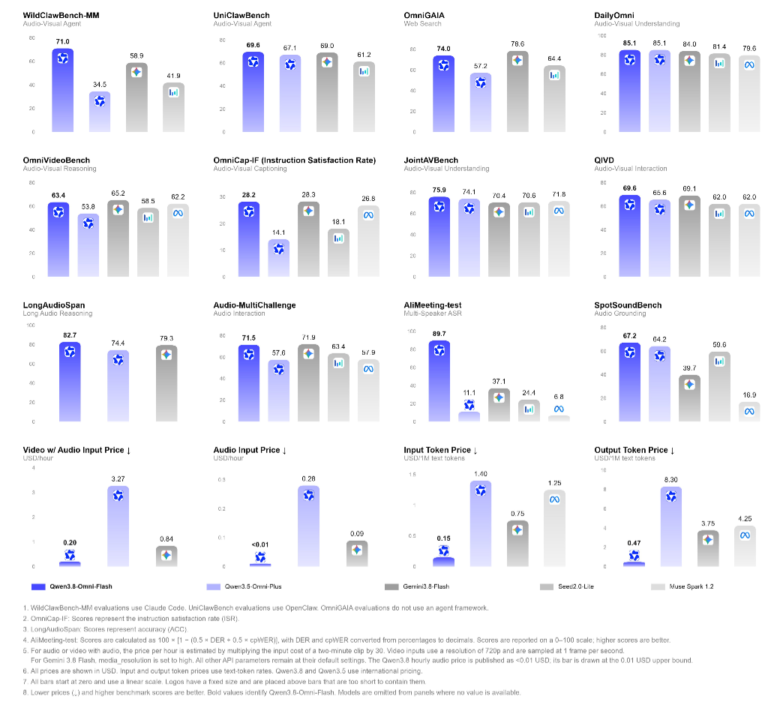
Qwen3.8-Omni-Flash beats Gemini 3.8 Flash on WildClawBench (71.0 vs 58.9) and AliMeeting (89.7 vs 37.1) at 4.2x lower video cost. Read our full teardown.
Google DeepMind is stealth-testing Gemini 4 Pro under gemini-3.8-flash in LMArena. Forensic audit of the 3D voxel pagoda, SVG pelican, and TPU speed.

Within eight days in early September 2026, DeepSeek-V4.1-Flash and Gemini 3.8 Flash toppled previous-generation $90/M-token flagship models on DeepSWE v1.1. Here is the forensic engineering breakdown: 890-byte KV cache, CED topology, RLVR benchmaxxing, and real-world agent TCO.
Muse Spark 1.3 scores 62 on Artificial Analysis. Compare Gemini 3.8 Flash, DeepSeek V4 Flash pricing, and Terminal-Bench 2.1 vs 4.0.
A source-led Gemini 3.8 Flash leak tracker separating confirmed Google documentation from secondary reports, rumored specifications, timing, and verification steps.
