
TL;DR The “Ollama Moment” for Decision AI: Just as Ollama unlocked local execution for generative transformers (Llama,…
TL;DR The “Ollama Moment” for Decision AI: Just as Ollama unlocked local execution for generative transformers (Llama,…
Apple’s M5 Ultra Mac Studio introduces a quad-die silicon packaging topology delivering 1.2 TB/s of unified memory…
Benchmarking Apple M5 Max/Ultra Mac Studio (oMLX, Qwen 3.8 27B, Bonsai 2 27B, qwen-image-2.1) against Thunderobot’s Ryzen AI Max+ 395 120B MoE SSD laptop.
Google Antigravity SDK now runs local models offline. Use this interactive CLI trick to run Ollama, LM Studio, or Gemma 4 LiteRT on your local machine.
Break free from cloud filters. Discover the 5 best uncensored AI image models to run locally in 2026—from FLUX.1 to Qwen 2.1 and Chroma. Full VRAM benchmarks.
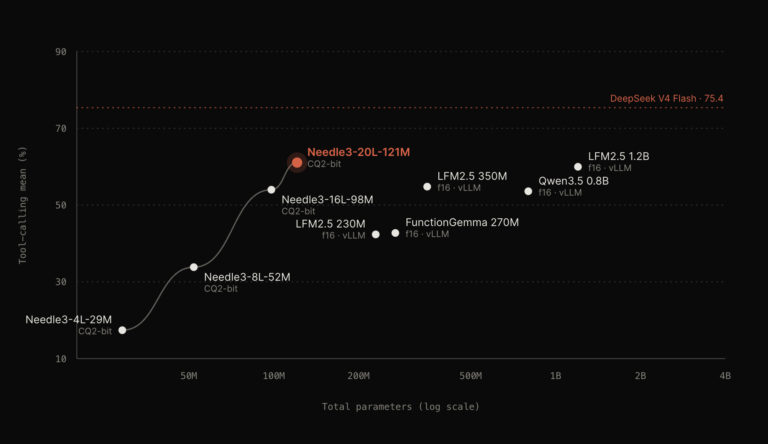
Needle 3 delivers 86% tool accuracy in an 8MB–29MB binary at 4,000 tok/sec. Cactus Compute’s laddered architecture replaces generative chat with edge automation.
Quick Answer · Featured Snippet Target What is PrismML Ternary Bonsai 2 27B? It is a 1.76-bit…
For three years, the undisputed gospel of the homelab AI community was brutally simple: buy a used…
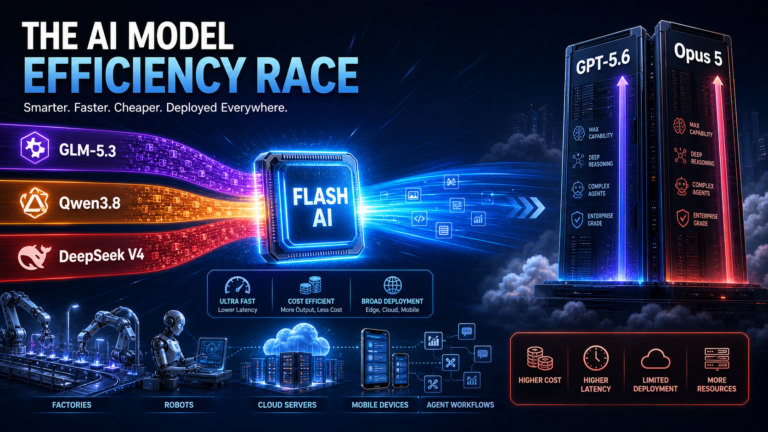
China’s Flash AI models are not a retreat from frontier AI. They are a deployment strategy built around cheaper inference, domestic chips and agents.
Qwen3.8-Flash-Next previews Qwen4 with 6B active parameters, QSA sparse attention and 1M context. We examine benchmarks, caveats and local hardware.