


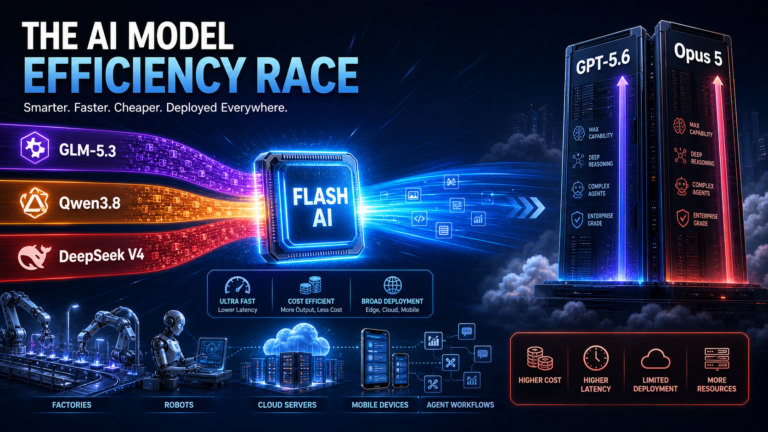

China’s Flash AI models are not a retreat from frontier AI. They are a deployment strategy built around cheaper inference, domestic chips and agents.
China’s Flash AI models are not a retreat from frontier AI. They are a deployment strategy built around cheaper inference, domestic chips and agents.
Qwen3.8-Flash-Next previews Qwen4 with 6B active parameters, QSA sparse attention and 1M context. We examine benchmarks, caveats and local hardware.

Imagine a world where you can deploy a model with the reasoning depth of Claude 4.5 Opus,…