
DeepSeek V5 rumors unmasked: V4.1-Flash brings Causal Enc-Dec, 890B/tok KV cache & 8B/16B MoE at $0.15/M on 160K Ascends. Frontier AI at 10X lower cost.
DeepSeek V5 rumors unmasked: V4.1-Flash brings Causal Enc-Dec, 890B/tok KV cache & 8B/16B MoE at $0.15/M on 160K Ascends. Frontier AI at 10X lower cost.
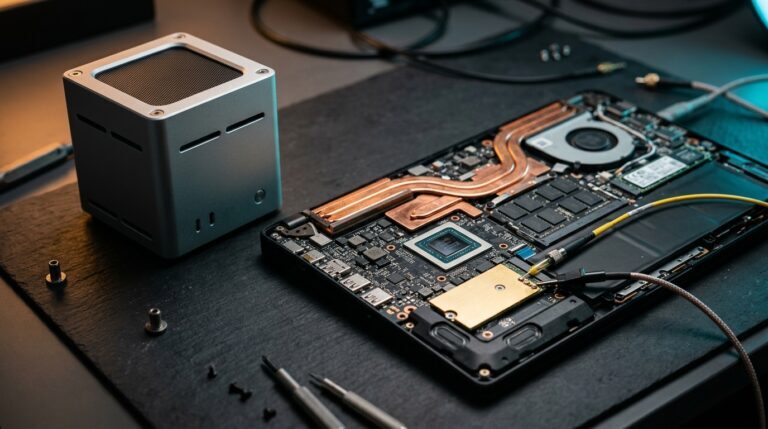
Benchmarking Apple M5 Max/Ultra Mac Studio (oMLX, Qwen 3.8 27B, Bonsai 2 27B, qwen-image-2.1) against Thunderobot’s Ryzen AI Max+ 395 120B MoE SSD laptop.
Xiaomi streamed its $3.5M real-time RL run for MiMo-V2.6. An architectural audit of live cluster telemetry, fatal OOM restarts, GRPO mechanics, and benchmark tops.
DeepSeek is training an 8-trillion-parameter MoE model on 160,000 Huawei Ascend 950DT chips. CEO Liang Wenfeng told investors the domestic chip bet “has to work.”
Step 5 Preview redefines the AI Pareto frontier. With a 600B/27B sparse MoE and 1M context, it matches Kimi K3 Max (AA Index 44) at ~$0.71 task cost.
Forensic audit of stealth/union-alpha: 74% DeepSWE score, MoA gateway architecture, Austrian Compunect GmbH trail, and developer outputs from X.
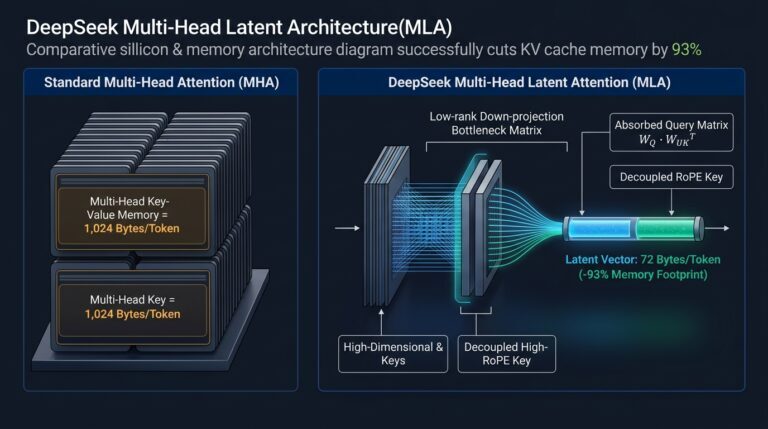
DeepSeek Multi-Head Latent Attention compresses KV cache down to 0.16 KB/token/layer. Here is the low-rank projection math and 128k context serving economics.
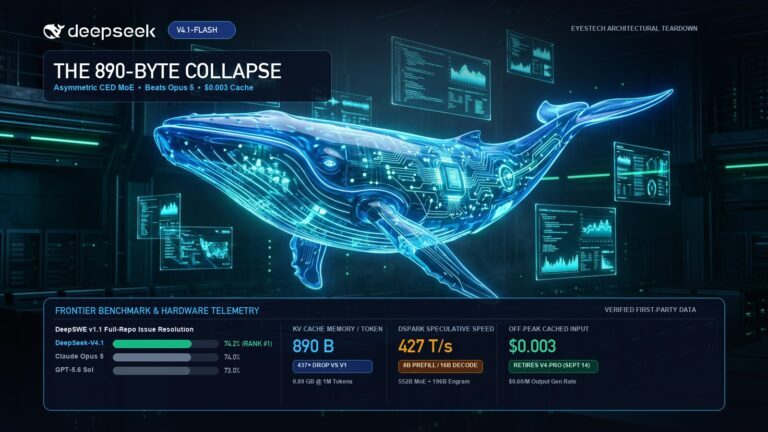
At 11:40 AM on September 10, 2026, DeepSeek dropped what may be the most consequential architectural disruption…
Leaked specifications and canary tests for xAI’s upcoming Grok 4.7 disclose a 2.1T parameter MoE architecture, supplemental pre-training on SpaceX telemetry, Pareto dominance over Claude Fable on CursorBench, and the physical limits of the 200,000-GPU Colossus supercluster.
Tencent’s Hy4 preview has 770B total parameters, 49B active per token and a 1M context. Here is what the benchmarks, demos and serving costs mean.