



Livenerf is collecting an Opus 5.5 baseline, with six days logged as of September 29. Its protocol cannot yet establish a post-release regression.
Independent evaluations of synthetic benchmark claims: ARC-AGI-3, SWE-bench Verified, HumanEval, and live latency audits.
Livenerf is collecting an Opus 5.5 baseline, with six days logged as of September 29. Its protocol cannot yet establish a post-release regression.
OpenAI’s GPT-6.1 Sol matches flagship Astra on DeepSWE v1.1 at $0.65 per task—a 7x cost reduction—while cutting autonomous computer-use safety violations from 17.4% to 4.3% and dropping cached input pricing to $0.10/1M tokens.
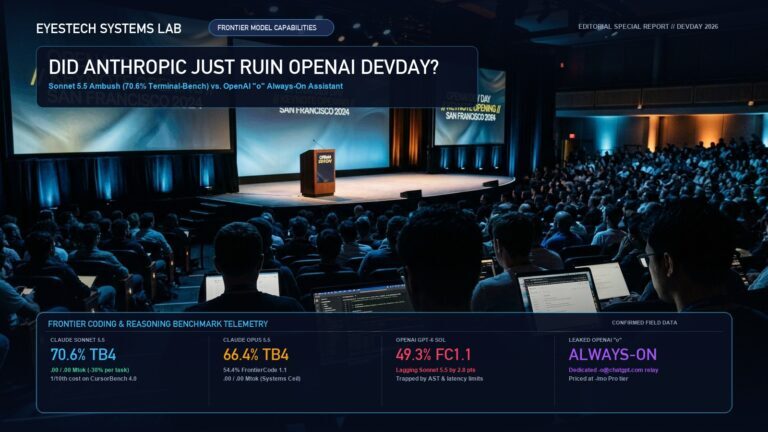
Anthropic dropped Claude Sonnet 5.5 hours before OpenAI DevDay 2026. With 70.6% Terminal-Bench scores, can the leaked ‘o’ always-on assistant save Sam Altman from an engineering ambush?
Sonnet 5.5 costs $2 per million input tokens and $10 per million output tokens. Compare attributed benchmarks, effort settings and migration requirements.
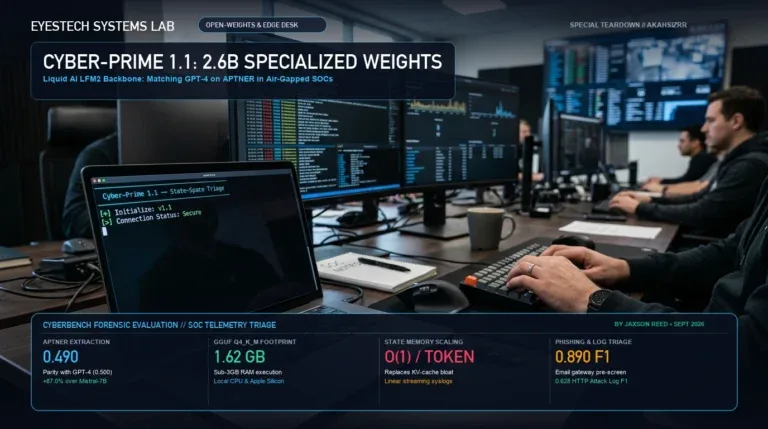
Cyber-Prime 1.1 is a specialized 2.6-billion-parameter language model developed by security researcher Akahsizrr. Built directly on Liquid…
MiniMax M3.1 leaks point to a preview, while Space Bunny’s tokenizer match and mixed SVG and Minecraft demos raise questions about its identity and coding.
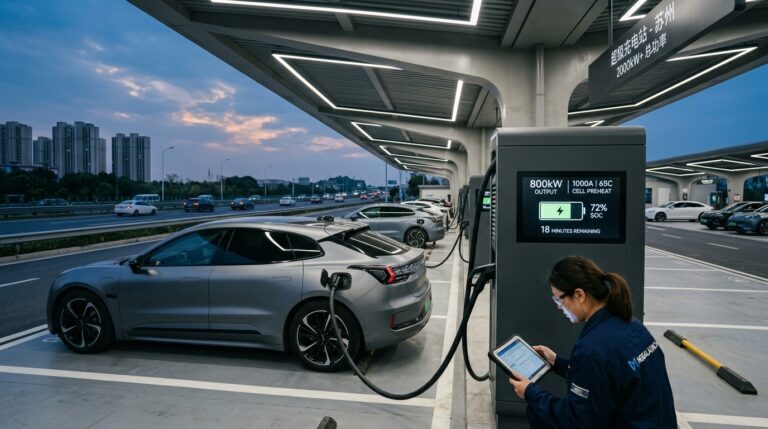
Geely achieves 10% to 70% EV charge in 4.5 minutes using 65°C thermal preheat, 2,250kW AI smart pulsing, and 12C LFP cells. Why US 150kW grid tech lags.
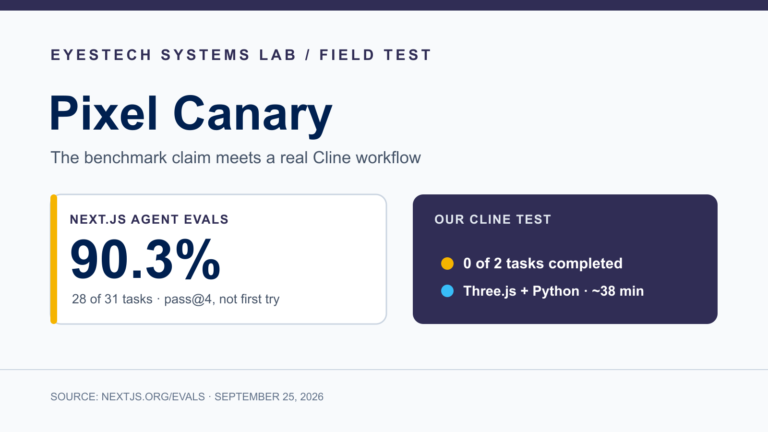
Pixel Canary’s 90% pass@4 benchmark met a different reality in Cline: two runs, 38 minutes of wall time, socket errors, and no code to test.
Benchmarking Apple M5 Max/Ultra Mac Studio (oMLX, Qwen 3.8 27B, Bonsai 2 27B, qwen-image-2.1) against Thunderobot’s Ryzen AI Max+ 395 120B MoE SSD laptop.
Claude Sonnet 5.5 leaks reveal Anthropic’s roadmap. See Theo’s GPT-6 Astra audit, the 4.4x token bloat trap, and Jev routing cutting agent costs by 80%.


