
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
Independent evaluations of synthetic benchmark claims: ARC-AGI-3, SWE-bench Verified, HumanEval, and live latency audits.
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
OpenAI announced an internal model it began training 24 days ago has already resolved 100+ open math conjectures and Navier–Stokes. Here is the audit of AGMAI, Lean 4, and the Fields Medalist revolt.
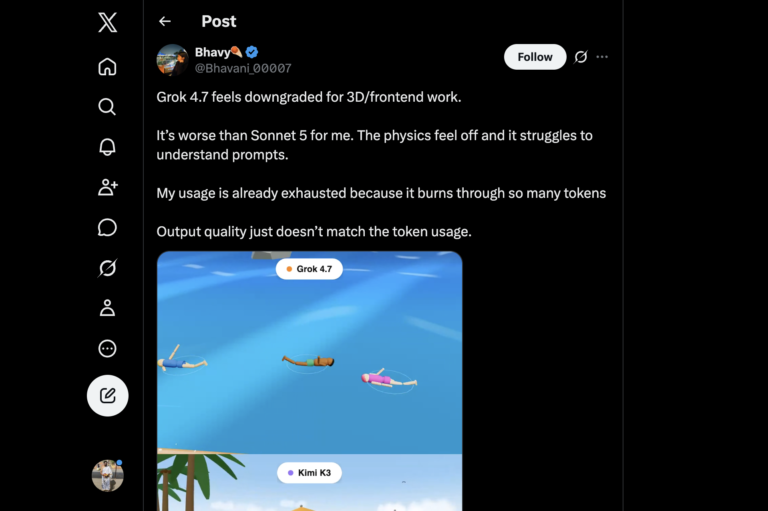
Real-world Grok 4.7 testing reveals severe quota burn, 3D benchmark regressions, and context degradation despite advertised 46.3% CursorBench gains.
DeepSeek V5 leaks claim 78.6% DeepSWE and $0.20/M tokens vs Astra’s $50. Forensic benchmark audit, hardware sizing, and enterprise deployment guide.
xAI releases Grok 4.7: 46.3% on CursorBench 4.0, 71.0% DeepSWE, and 64% EEBench at $2/$6 per million tokens. Delivers multi-hour verified agentic coding.
Extending test-time compute can collapse LLM accuracy. Here is the forensic math on Goodhart gaming, attention drift, and why latent recurrent depth wins.
Disclosures broken by developer Lyra confirm Anthropic is closed-beta testing Claude Opus 5.5 (‘claude-wafer-eap’), cutting pricing to $4/$20 per M tokens.
Step 5 Preview redefines the AI Pareto frontier. With a 600B/27B sparse MoE and 1M context, it matches Kimi K3 Max (AA Index 44) at ~$0.71 task cost.
Quick Answer · Featured Snippet Target What is PrismML Ternary Bonsai 2 27B? It is a 1.76-bit…