



Sarvam Vision 2.1 sets a new Pareto frontier in document intelligence, scoring 87.3% on olmOCR and 94.97% on OmniDocBench with 87.39% Indic word accuracy.
Independent evaluations of synthetic benchmark claims: ARC-AGI-3, SWE-bench Verified, HumanEval, and live latency audits.
Sarvam Vision 2.1 sets a new Pareto frontier in document intelligence, scoring 87.3% on olmOCR and 94.97% on OmniDocBench with 87.39% Indic word accuracy.
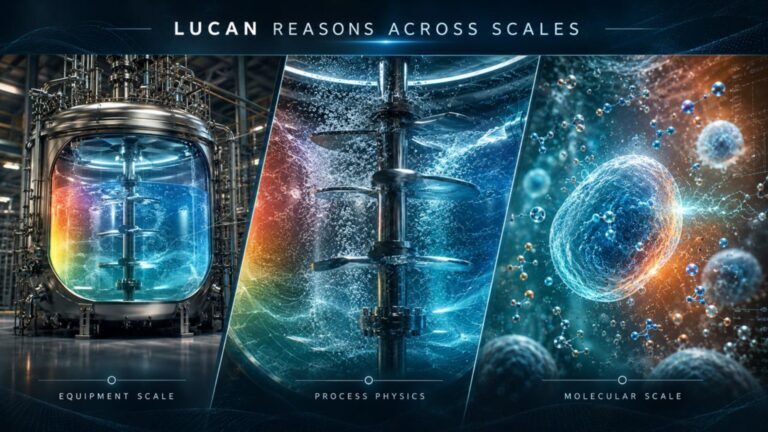
Shodh AI unveils LUCAN, India’s first Physical AI world model. Bypasses 124 classical solver runs to cut 500 hours of chemistry scale-up to 5.6 hours.
Enterprise speech synthesis has reached an operational impasse. For three years, production speech pipelines have suffered from…
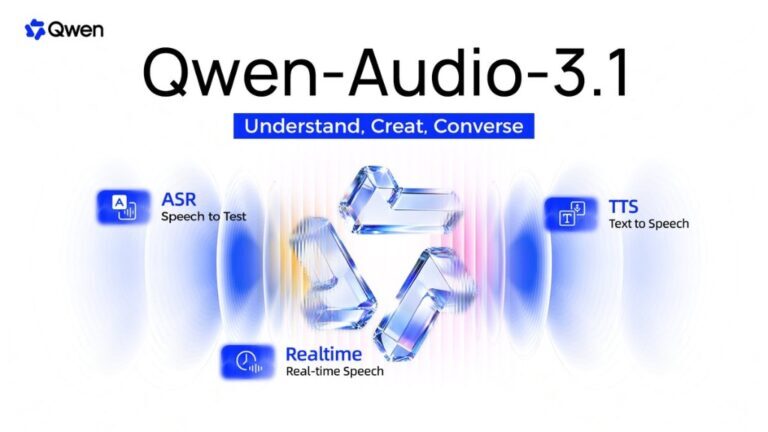
Alibaba launched Qwen-Audio-3.1 with 5 models, TTS-Next soundscapes, ASR-Next audio QA, and up to 95% price cuts. Here is our forensic systems review.
Break free from cloud filters. Discover the 5 best uncensored AI image models to run locally in 2026—from FLUX.1 to Qwen 2.1 and Chroma. Full VRAM benchmarks.
Gemini 3.8 Flash takes on GPT-6 Luna. Compare 73.7% vs 66.6% DeepSWE, $0.10/M token pricing, TPU v6e vs Astra routing, and 2.8% deception rates.
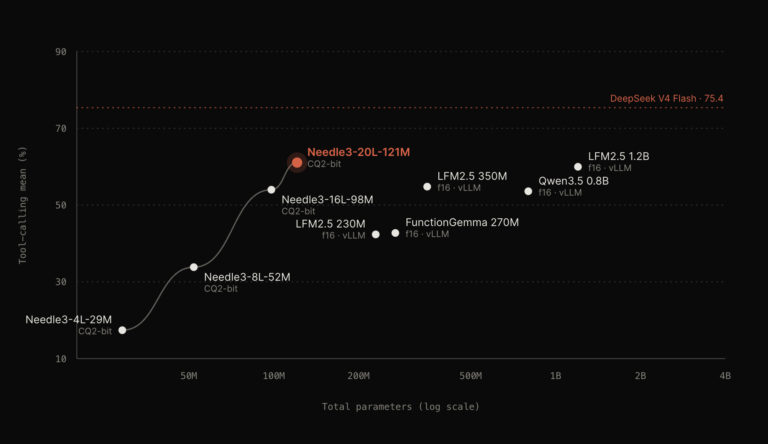
Needle 3 delivers 86% tool accuracy in an 8MB–29MB binary at 4,000 tok/sec. Cactus Compute’s laddered architecture replaces generative chat with edge automation.
Inside OpenAI’s Astra for Law: a 230M-URL legal index, CourtListener integration, and 54% Vals AI accuracy. Here is the forensic reality behind the release.
Xiaomi streamed its $3.5M real-time RL run for MiMo-V2.6. An architectural audit of live cluster telemetry, fatal OOM restarts, GRPO mechanics, and benchmark tops.
ConvAI Innovations’ 0.4B non-autoregressive decision model Laya hit #1 trending on Hugging Face in 48 hours, matching Jev’s sub-35ms speed under Apache 2.0.


