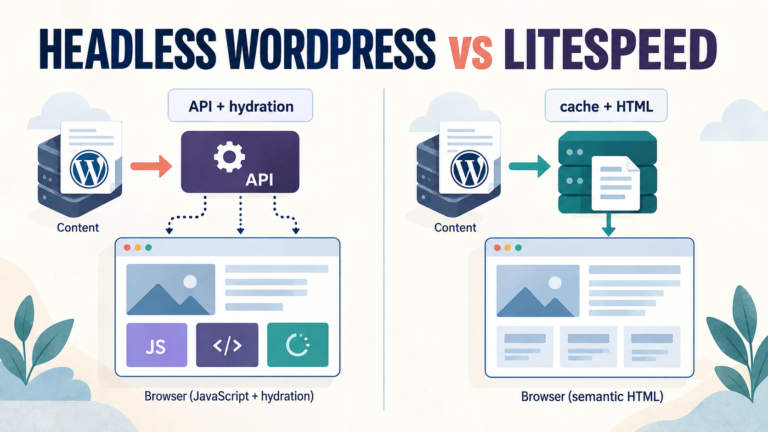

A practical, evidence-based comparison of headless WordPress and LiteSpeed: Core Web Vitals, SEO, caching, JavaScript, ESI, workflow complexity and how to measure both architectures.
Deep architectural teardowns, frontier benchmarks, hype-debunking, and capability leaks across frontier AI models.
A practical, evidence-based comparison of headless WordPress and LiteSpeed: Core Web Vitals, SEO, caching, JavaScript, ESI, workflow complexity and how to measure both architectures.
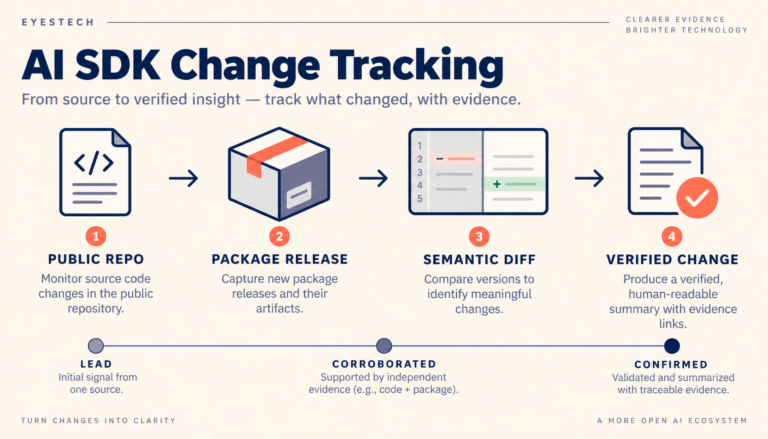
AI SDK change tracking, fact-checked: monitor public GitHub, npm and PyPI releases, remove codegen noise and verify model or API changes responsibly.
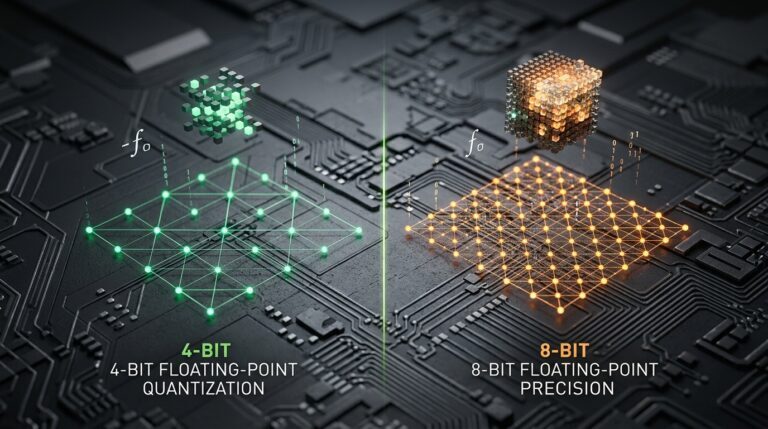
NVFP4 vs FP8 on Blackwell, fact-checked: block-16 scaling, measured speedups, quality limits, mixed-precision recipes and a reproducible acceptance test.
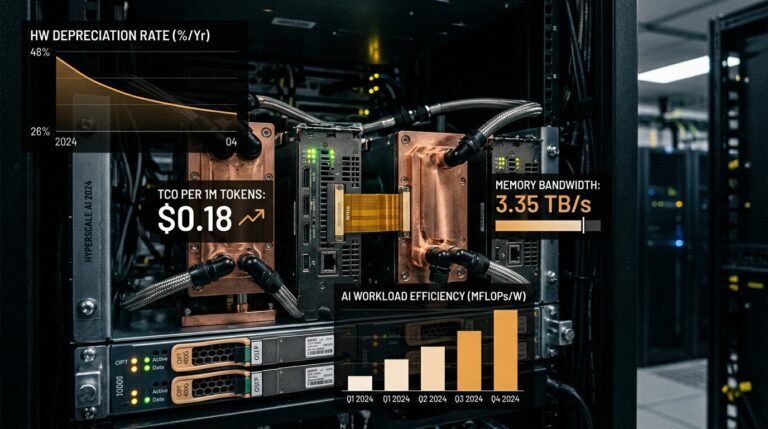
55+ verified benchmarks on AI inference cost, latency, GPU cluster failure rates, and memory bandwidth walls. Download raw 2026 telemetry data.
When autonomous coding agents scaled to frontier reasoning models, industry leaderboards celebrated a major milestone: 65% resolve…
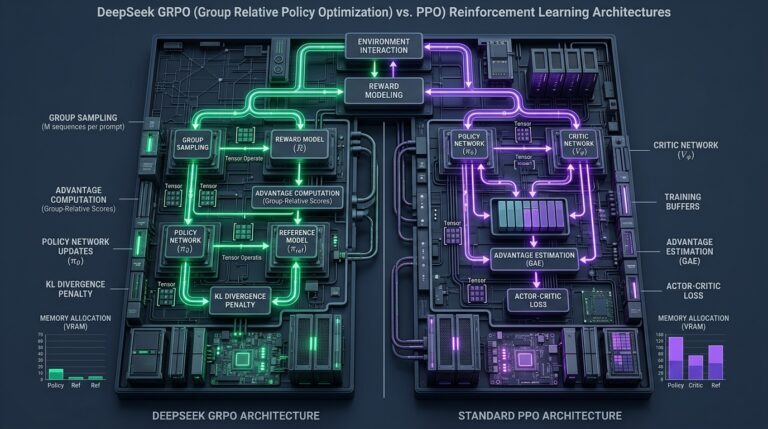
Scaling Reinforcement Learning from Human Feedback (RLHF) to multi-thousand-token reasoning models encountered an insurmountable systems bottleneck: the…

OpenAI has paused new sign-ups and upgrades for the $200/mo ChatGPT Pro tier as power users leveraging the 20X token capacity multiplier on GPT-6 Astra burn through 15M to 30M reasoning tokens per month, creating up to a -$1,240/month deficit per seat.

An exhaustive architectural audit comparing Qualcomm’s Snapdragon 8 Elite Hexagon NPU against Apple’s A20 Pro 32-core Neural Engine running on-device INT8 Vision-Language Models (MiniCPM-V 2.6, Llama 3.2-Vision, and Qwen2-VL).

An empirical systems audit of HNSW vs. IVF-PQ indexing across 100 million 1536-dimensional vectors. Benchmarking Qdrant, OpenSearch, Milvus, and Faiss on RAM footprint, Recall@10, QPS throughput, and NVMe disk-spilling economics.

Technical benchmark audit of DeepSWE v1.1 by Aditi Sharma. Debunking git reflog leaks and test tampering, while exposing how 166-turn Test-Time Compute subsidizes 74% Pass@1 rates.