Xiaomi streamed its $3.5M real-time RL run for MiMo-V2.6. An architectural audit of live cluster telemetry, fatal OOM restarts, GRPO mechanics, and benchmark tops.
Real-time AI API pricing, prompt caching math, inference TCO, and enterprise token budget optimization.
Xiaomi streamed its $3.5M real-time RL run for MiMo-V2.6. An architectural audit of live cluster telemetry, fatal OOM restarts, GRPO mechanics, and benchmark tops.
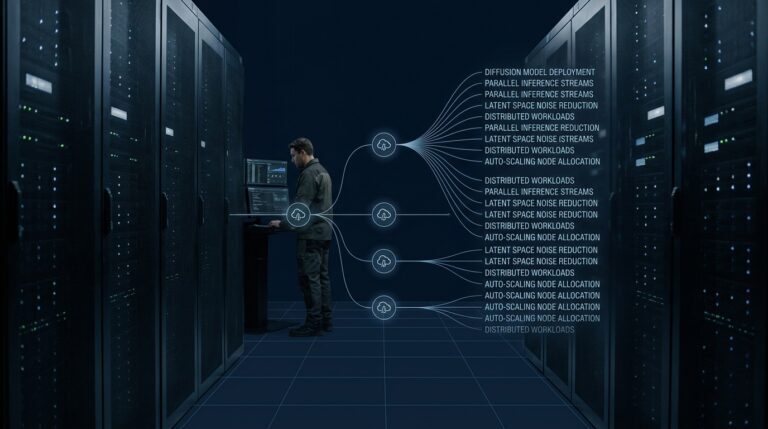
Deploy DiffusionGemma-Jev on Cloud Run with one command. Single-step latency: 35–60ms. Batch@32 throughput: 100–123 req/sec. Costs ~$3/hr active, $0 idle.
OpenAI GPT-6 Luna faces Xiaomi MiMo-V2.6-Pro. Compare 71.9% DeepSWE, $0.10/M tokens, 1.02T open MoE architecture, and enterprise TCO economics.
OpenAI drops GPT-6 Sol at $2/M input with 50% fewer errors, hitting 68.8% on DeepSWE v1.1 to match Claude Fable 5 at 80% lower cost. Full tech breakdown.
OpenAI releases GPT-6 Luna at $0.10/M input and $0.50/M output, scoring 66.6% on DeepSWE to match Claude Opus 5 at 93% lower per-task operational cost.
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
JPMorgan capped Claude Code at $2,000/mo. Here is the Devspace sandbox architecture, token purchasing power math, and the 3-tier enterprise budget matrix.
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
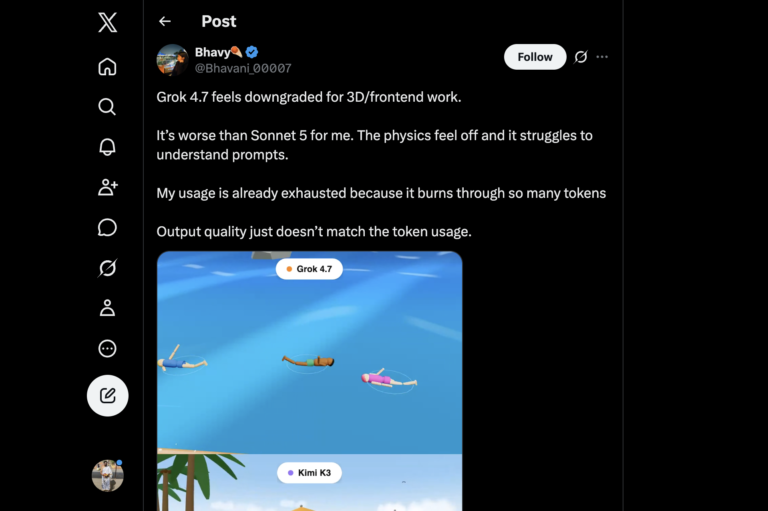
Real-world Grok 4.7 testing reveals severe quota burn, 3D benchmark regressions, and context degradation despite advertised 46.3% CursorBench gains.
DeepSeek V5 leaks claim 78.6% DeepSWE and $0.20/M tokens vs Astra’s $50. Forensic benchmark audit, hardware sizing, and enterprise deployment guide.