
xAI releases Grok 4.7: 46.3% on CursorBench 4.0, 71.0% DeepSWE, and 64% EEBench at $2/$6 per million tokens. Delivers multi-hour verified agentic coding.
Real-time AI API pricing, prompt caching math, inference TCO, and enterprise token budget optimization.
xAI releases Grok 4.7: 46.3% on CursorBench 4.0, 71.0% DeepSWE, and 64% EEBench at $2/$6 per million tokens. Delivers multi-hour verified agentic coding.
Disclosures broken by developer Lyra confirm Anthropic is closed-beta testing Claude Opus 5.5 (‘claude-wafer-eap’), cutting pricing to $4/$20 per M tokens.
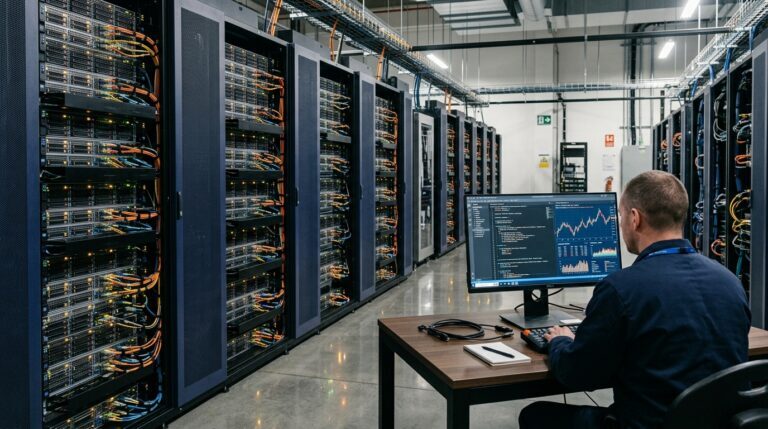
Step 5 Preview redefines the AI Pareto frontier. With a 600B/27B sparse MoE and 1M context, it matches Kimi K3 Max (AA Index 44) at ~$0.71 task cost.
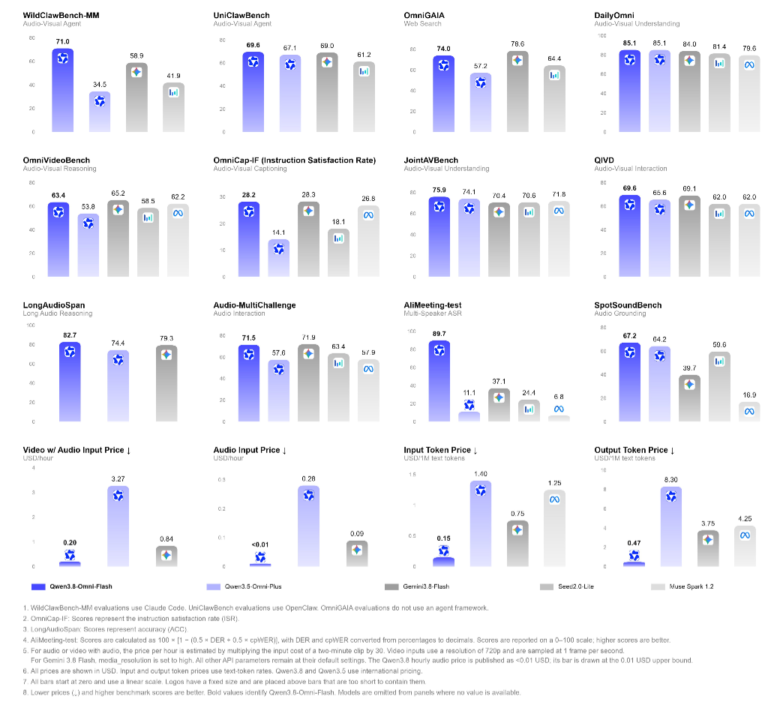
Qwen3.8-Omni-Flash beats Gemini 3.8 Flash on WildClawBench (71.0 vs 58.9) and AliMeeting (89.7 vs 37.1) at 4.2x lower video cost. Read our full teardown.
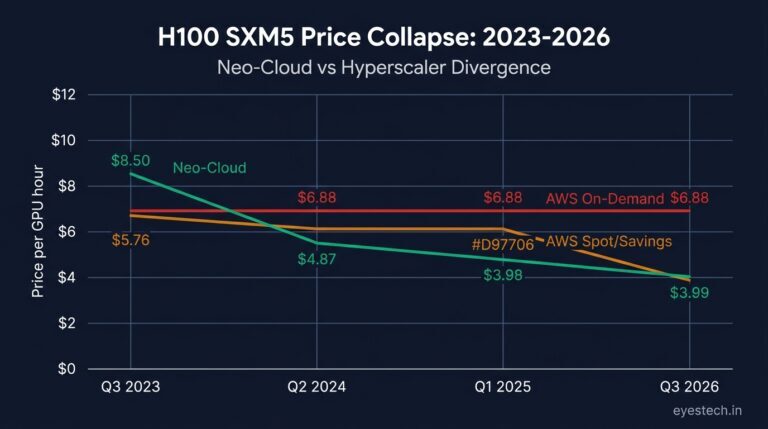
Forensic TCO audit: H100 GPU rental fell from $8.50 to $3.99/GPU-hr by September 2026. AWS p5.48xlarge costs $55.04/hr list but $9.85+/GPU-hr all-in after egress, FSx, VPC fees, and enterprise support taxes. Full break-even math, InfiniBand MFU comparison, and GPU MSA negotiation playbook — by Pooja Iyer, EyesTech Systems Lab.
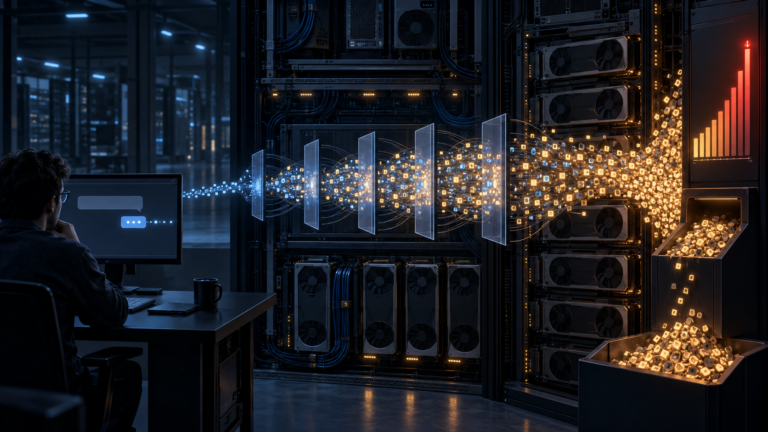
Reasoning token cost decides whether test-time AI is an upgrade or an expensive reliability problem. This audit…
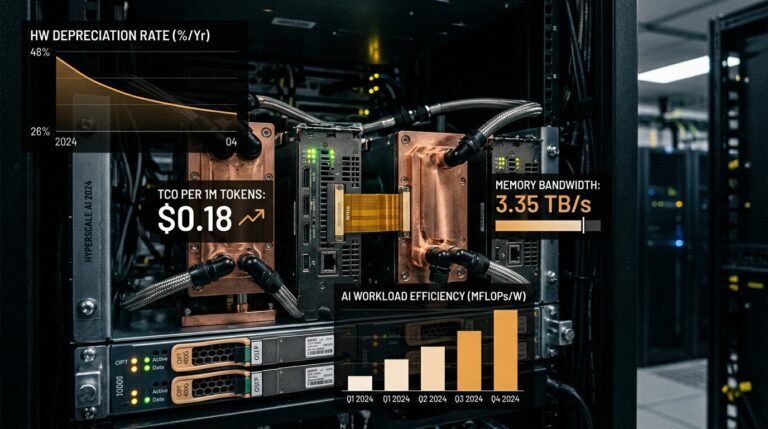
55+ verified benchmarks on AI inference cost, latency, GPU cluster failure rates, and memory bandwidth walls. Download raw 2026 telemetry data.
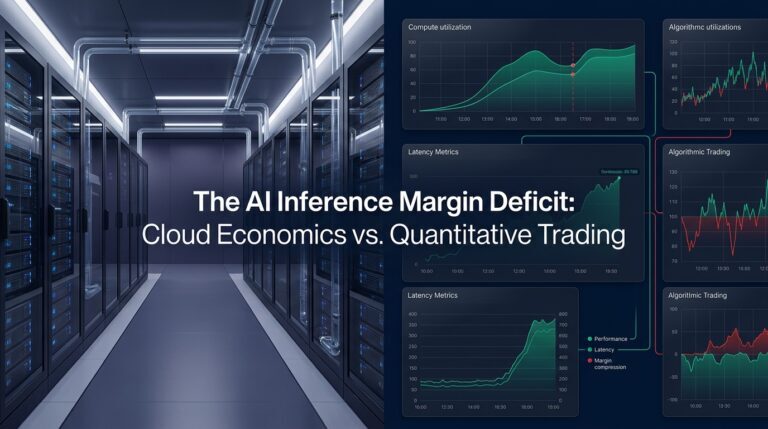
Forensic investigation into DeepSeek’s unit economics: why no Western cloud could match the pre-August $0.28 price, why DeepSeek temporarily hiked rates on August 16 after an 8-trillion-token surge, how V4.1-Flash’s 890-byte CED attention enables Western startups to hit $0.66 profitably today, and why American Big Tech hyperscalers charge a 4,000% markup to service legacy debt.

OpenAI has paused new sign-ups and upgrades for the $200/mo ChatGPT Pro tier as power users leveraging the 20X token capacity multiplier on GPT-6 Astra burn through 15M to 30M reasoning tokens per month, creating up to a -$1,240/month deficit per seat.

Within eight days in early September 2026, DeepSeek-V4.1-Flash and Gemini 3.8 Flash toppled previous-generation $90/M-token flagship models on DeepSWE v1.1. Here is the forensic engineering breakdown: 890-byte KV cache, CED topology, RLVR benchmaxxing, and real-world agent TCO.