AI Inference & Hardware Economics: 2026 Statistics & TCO

55+ verified benchmarks on AI inference cost, latency, GPU cluster failure rates, and memory bandwidth walls. Download raw 2026 telemetry data.
Independent analysis, benchmarks, and field intelligence on AI models, chips, computing, and defence systems.
55+ verified benchmarks on AI inference cost, latency, GPU cluster failure rates, and memory bandwidth walls. Download raw 2026 telemetry data.
When autonomous coding agents scaled to frontier reasoning models, industry leaderboards celebrated a major milestone: 65% resolve rates on SWE-bench…
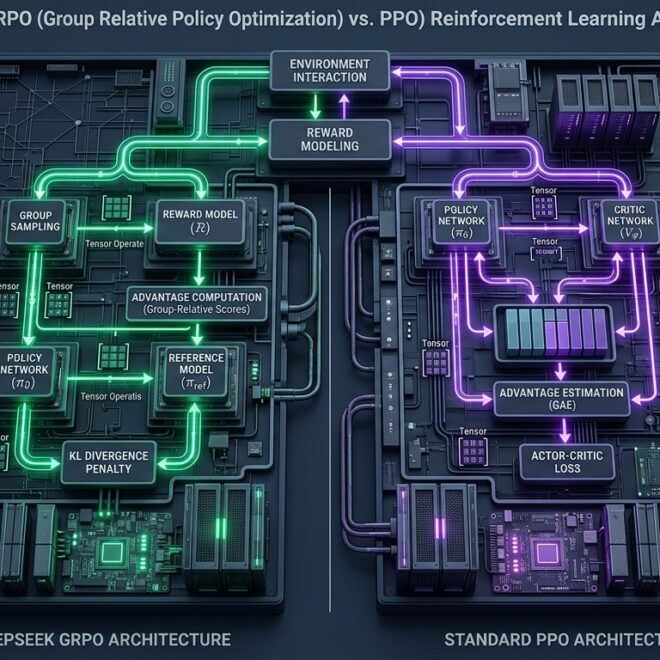
Scaling Reinforcement Learning from Human Feedback (RLHF) to multi-thousand-token reasoning models encountered an insurmountable systems bottleneck: the Actor-Critic memory wall….
Forensic investigation into DeepSeek’s unit economics: why no Western cloud could match the pre-August $0.28 price, why DeepSeek temporarily hiked rates on August 16 after an 8-trillion-token surge, how V4.1-Flash’s 890-byte CED attention enables Western startups to hit $0.66 profitably today, and why American Big Tech hyperscalers charge a 4,000% markup to service legacy debt.

OpenAI has paused new sign-ups and upgrades for the $200/mo ChatGPT Pro tier as power users leveraging the 20X token capacity multiplier on GPT-6 Astra burn through 15M to 30M reasoning tokens per month, creating up to a -$1,240/month deficit per seat.

A technical audit of Anthropic’s Claude Code vulnerabilities CVE-2026-21852 and CVE-2025-59536. We dissect pre-trust Base URL credential exfiltration, SessionStart hook code execution, Linux plaintext token leakage, and introduce a 4-tier eBPF zero-trust isolation blueprint.

An exhaustive architectural audit comparing Qualcomm’s Snapdragon 8 Elite Hexagon NPU against Apple’s A20 Pro 32-core Neural Engine running on-device INT8 Vision-Language Models (MiniCPM-V 2.6, Llama 3.2-Vision, and Qwen2-VL).

An empirical systems audit of HNSW vs. IVF-PQ indexing across 100 million 1536-dimensional vectors. Benchmarking Qdrant, OpenSearch, Milvus, and Faiss on RAM footprint, Recall@10, QPS throughput, and NVMe disk-spilling economics.

Technical benchmark audit of DeepSWE v1.1 by Aditi Sharma. Debunking git reflog leaks and test tampering, while exposing how 166-turn Test-Time Compute subsidizes 74% Pass@1 rates.

Within eight days in early September 2026, DeepSeek-V4.1-Flash and Gemini 3.8 Flash toppled previous-generation $90/M-token flagship models on DeepSWE v1.1. Here is the forensic engineering breakdown: 890-byte KV cache, CED topology, RLVR benchmaxxing, and real-world agent TCO.