Did Google Reach ASI Internally? Inside DeepMind’s RSI Leak

No, Google has not reached ASI. Forensic audit of DeepMind’s rsi-model-liverl-le leak reveals automated LiveRL loops, not runaway superintelligence.
Independent analysis, benchmarks, and field intelligence on AI models, chips, computing, and defence systems.
No, Google has not reached ASI. Forensic audit of DeepMind’s rsi-model-liverl-le leak reveals automated LiveRL loops, not runaway superintelligence.
A fact-checked analysis of TSMC’s 2nm allocation, what Apple’s early lead really means, and how yield, packaging and rival foundry roadmaps shape supply.
A fact-checked engineering analysis of fiber-optic FPV drones: why RF jammers fail, what the tether costs, how they are detected, and how layered counter-UAS defenses adapt.
A practical, evidence-based comparison of headless WordPress and LiteSpeed: Core Web Vitals, SEO, caching, JavaScript, ESI, workflow complexity and how to measure both architectures.
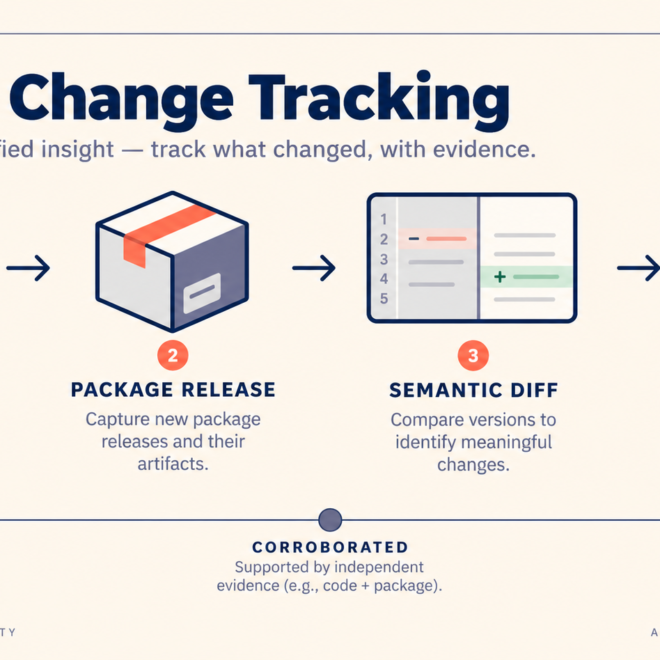
AI SDK change tracking, fact-checked: monitor public GitHub, npm and PyPI releases, remove codegen noise and verify model or API changes responsibly.
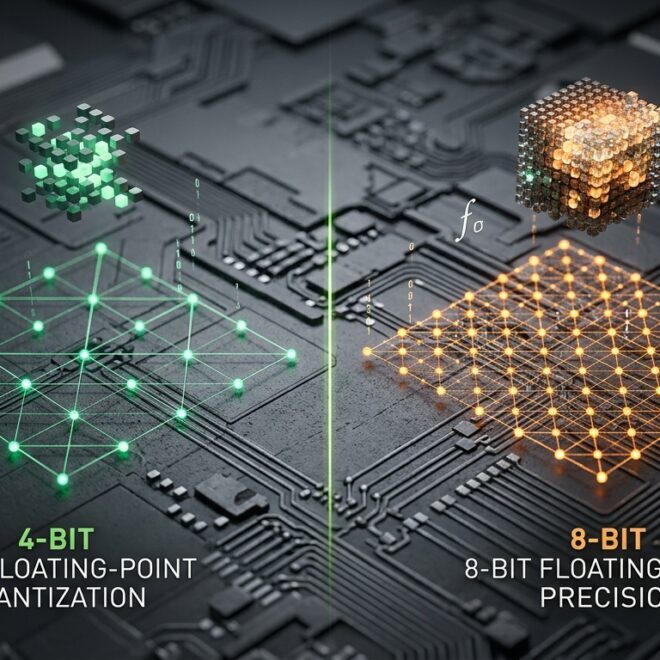
NVFP4 vs FP8 on Blackwell, fact-checked: block-16 scaling, measured speedups, quality limits, mixed-precision recipes and a reproducible acceptance test.
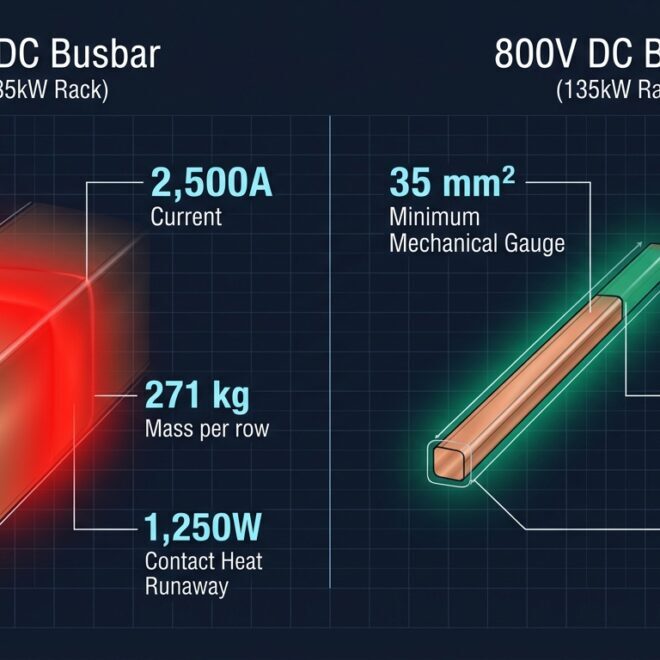
Forensic engineering audit: Why 120kW+ NVIDIA GB200 NVL72 and Rubin clusters trigger transformer core saturation, di/dt power surges, and substation fires. The mathematical case for 800V DC busbars, Silicon Carbide Solid-State Circuit Breakers, and 96% copper mass reduction.
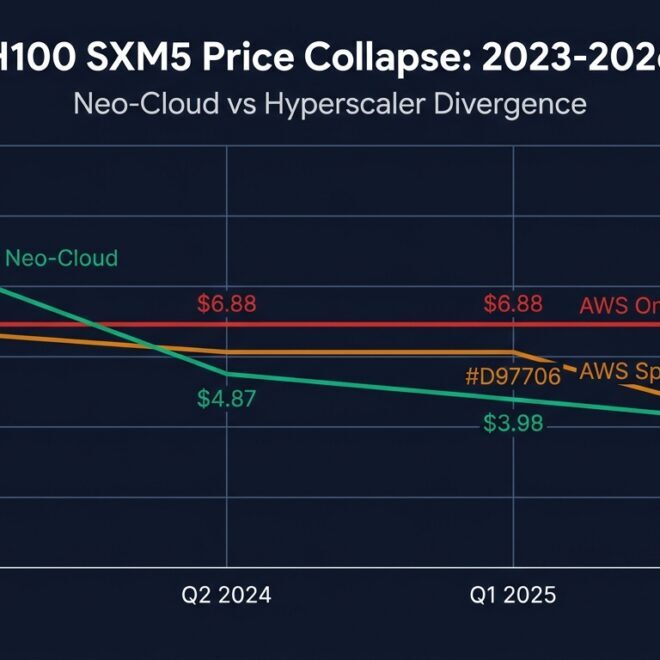
Forensic TCO audit: H100 GPU rental fell from $8.50 to $3.99/GPU-hr by September 2026. AWS p5.48xlarge costs $55.04/hr list but $9.85+/GPU-hr all-in after egress, FSx, VPC fees, and enterprise support taxes. Full break-even math, InfiniBand MFU comparison, and GPU MSA negotiation playbook — by Pooja Iyer, EyesTech Systems Lab.
Reasoning token cost decides whether test-time AI is an upgrade or an expensive reliability problem. This audit gives engineering teams…
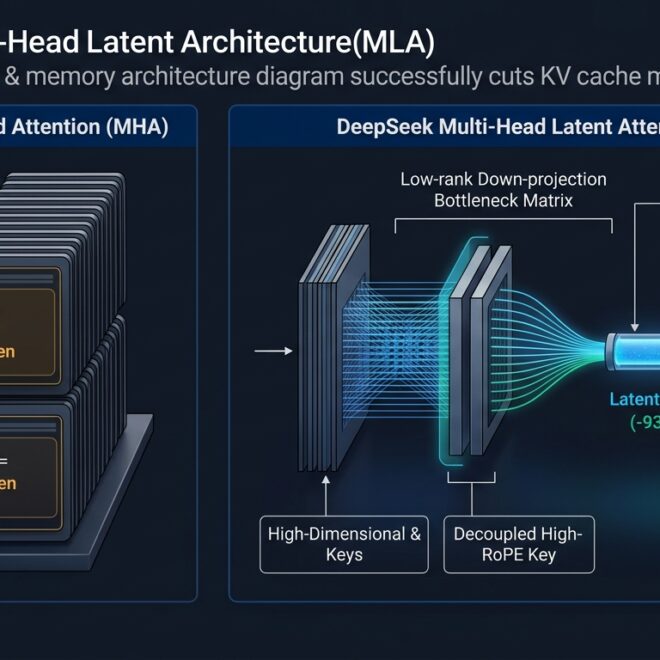
DeepSeek Multi-Head Latent Attention compresses KV cache down to 0.16 KB/token/layer. Here is the low-rank projection math and 128k context serving economics.