A technical audit of Anthropic’s Claude Code vulnerabilities CVE-2026-21852 and CVE-2025-59536. We dissect pre-trust Base URL credential exfiltration, SessionStart hook code execution, Linux plaintext token leakage, and introduce a 4-tier eBPF zero-trust isolation blueprint.
Technical benchmark audit of DeepSWE v1.1 by Aditi Sharma. Debunking git reflog leaks and test tampering, while exposing how 166-turn Test-Time Compute subsidizes 74% Pass@1 rates.
Computer use lets an AI agent operate a browser or desktop. Here is the action loop that turns model output into clicks, keystrokes, screenshots, and verified results.
Meta’s Muse Code is the native harness for Muse Spark 1.3. Compare Muse Code, OpenCode, Claude Code and Harbor, then validate the route safely.
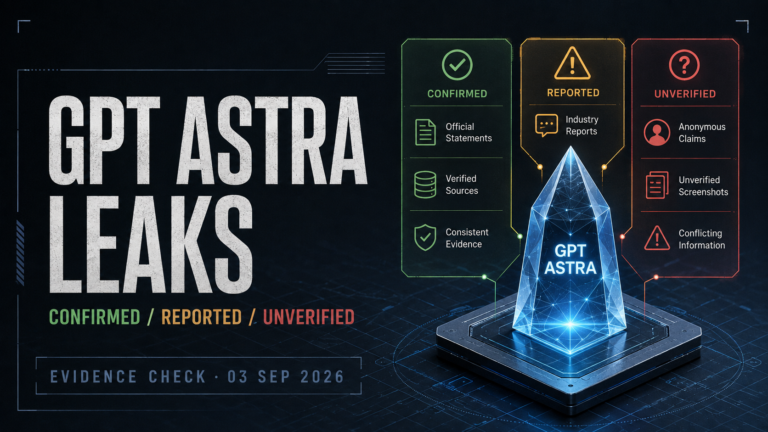
An early-access Astra video shows stronger coding, 3D, multimodal and computer-use performance—but also weak UI judgment, slow execution and unreliable agent status.
Muse Spark 1.3 scores 62 on Artificial Analysis. Compare Gemini 3.8 Flash, DeepSeek V4 Flash pricing, and Terminal-Bench 2.1 vs 4.0.
Qwen3.8-Max-0902 is live on QwenCloud with 1M context and cache-aware pricing. Here is what the benchmarks and API economics actually show.
Anthropic’s Claude Fable 5.1 pairs large gains on agentic evals with a 75% cache-read cut. Here is what the benchmarks, migration breaks, and X’s 3D demos mean for real workloads.
Tencent’s Hy4 preview has 770B total parameters, 49B active per token and a 1M context. Here is what the benchmarks, demos and serving costs mean.
Cursor pricing in 2026, explained: plans ($20 Pro, $60 Pro+, $200 Ultra, ₹649 Start), fast requests vs slow queues, API credits, overages, and practical ways to control your bill.