
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
xAI releases Grok 4.7: 46.3% on CursorBench 4.0, 71.0% DeepSWE, and 64% EEBench at $2/$6 per million tokens. Delivers multi-hour verified agentic coding.
Disclosures broken by developer Lyra confirm Anthropic is closed-beta testing Claude Opus 5.5 (‘claude-wafer-eap’), cutting pricing to $4/$20 per M tokens.
After engineers caught ZCode packaging full .git trees and exfiltrating them to Aliyun OSS, Z.ai open-sourced the harness to quell a widespread enterprise boycott.
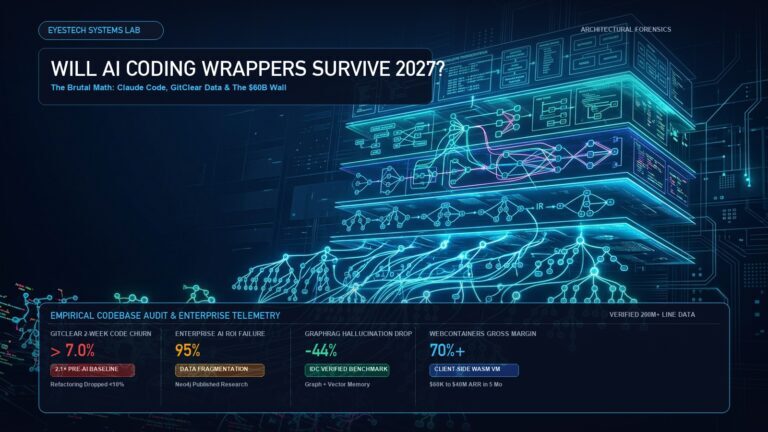
Executive Summary & Position #0 Answer Will AI coding wrappers survive 2027? Thin prompt wrappers will be…
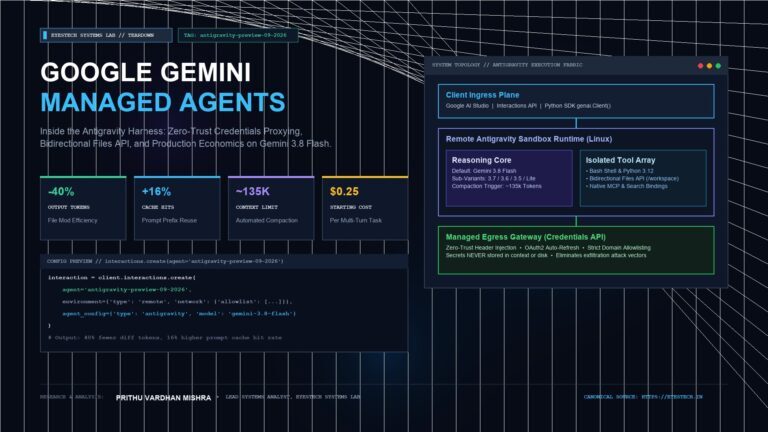
Google updates Gemini managed agents with the Antigravity harness: cutting 40% of output tokens, boosting cache hits by 16%, with new Files & Credentials APIs.
Forensic audit of stealth/union-alpha: 74% DeepSWE score, MoA gateway architecture, Austrian Compunect GmbH trail, and developer outputs from X.
Google Dream-RSI cuts code search calls by 161.5× and hits 2,350ms SOTA on Lasso using offline replay simulators—leaving LLM weights 100% frozen.
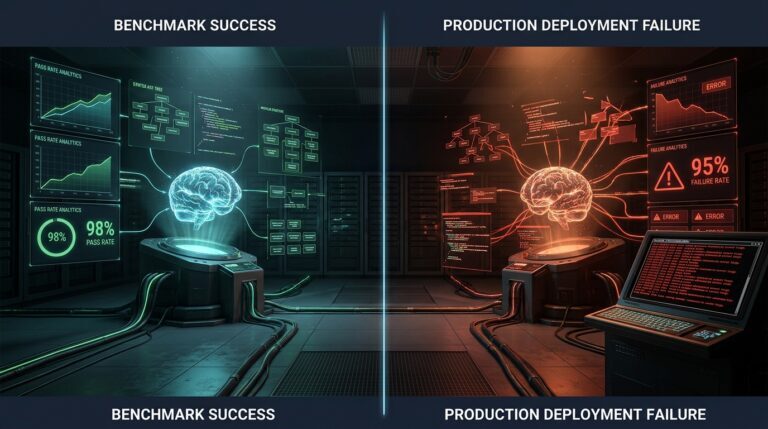
When autonomous coding agents scaled to frontier reasoning models, industry leaderboards celebrated a major milestone: 65% resolve…