Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
DeepSeek V5 leaks claim 78.6% DeepSWE and $0.20/M tokens vs Astra’s $50. Forensic benchmark audit, hardware sizing, and enterprise deployment guide.
Extending test-time compute can collapse LLM accuracy. Here is the forensic math on Goodhart gaming, attention drift, and why latent recurrent depth wins.
For three years, enterprise engineering forced autoregressive LLMs into programmatic workflows. TypeSafe AI’s Jev proved why we were wrong—and why System 3 is next.
Disclosures broken by developer Lyra confirm Anthropic is closed-beta testing Claude Opus 5.5 (‘claude-wafer-eap’), cutting pricing to $4/$20 per M tokens.
Step 5 Preview redefines the AI Pareto frontier. With a 600B/27B sparse MoE and 1M context, it matches Kimi K3 Max (AA Index 44) at ~$0.71 task cost.
Stanford researchers discovered the brain is two distinct, fused organs. The finding explains decades of biological failure and why monolithic AI struggles with physical agency.
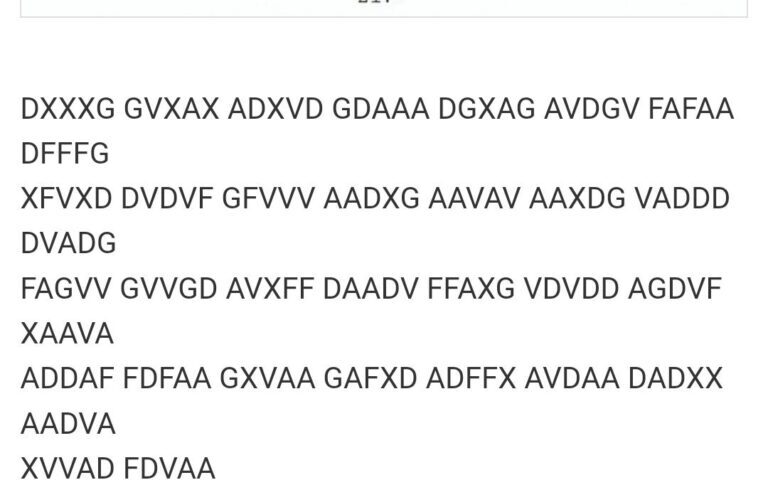
GPT-6 Astra cracked an unsolved 1918 German ADFGVX cipher using historical monograph search and key transposition in 170 chars. Here is the technical audit.
Executive Summary & Position #0 Answer Did Google “benchmax” Gemini 4 Pro? Yes, the empirical and telemetry…
Forensic audit of stealth/union-alpha: 74% DeepSWE score, MoA gateway architecture, Austrian Compunect GmbH trail, and developer outputs from X.