



DeepSeek V5 rumors unmasked: V4.1-Flash brings Causal Enc-Dec, 890B/tok KV cache & 8B/16B MoE at $0.15/M on 160K Ascends. Frontier AI at 10X lower cost.
DeepSeek V5 rumors unmasked: V4.1-Flash brings Causal Enc-Dec, 890B/tok KV cache & 8B/16B MoE at $0.15/M on 160K Ascends. Frontier AI at 10X lower cost.
Tsinghua University’s ICLR 2026 Cache-to-Cache (C2C) neural fuser eliminates inter-agent text generation to accelerate multi-LLM inference by…
OpenAI releases GPT-6 Luna at $0.10/M input and $0.50/M output, scoring 66.6% on DeepSWE to match Claude Opus 5 at 93% lower per-task operational cost.
Executive Briefing Donald Trump’s warning that “whoever wins AI wins everything” was treated in Washington as an…
DeepSeek is training an 8-trillion-parameter MoE model on 160,000 Huawei Ascend 950DT chips. CEO Liang Wenfeng told investors the domestic chip bet “has to work.”

Within eight days in early September 2026, DeepSeek-V4.1-Flash and Gemini 3.8 Flash toppled previous-generation $90/M-token flagship models on DeepSWE v1.1. Here is the forensic engineering breakdown: 890-byte KV cache, CED topology, RLVR benchmaxxing, and real-world agent TCO.
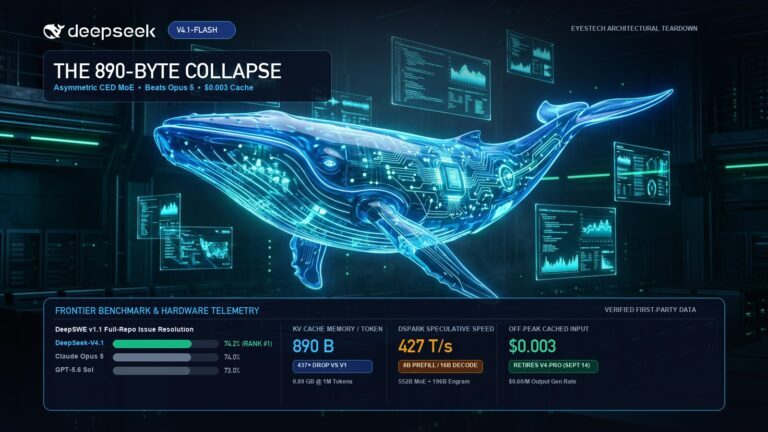
At 11:40 AM on September 10, 2026, DeepSeek dropped what may be the most consequential architectural disruption…

If you haven’t been paying close attention to the open-weights AI ecosystem over the last few weeks,…

