



Tencent’s Hy4 preview is a 770B open model. The real test is deployment.

Tencent’s Hy4 preview has 770B total parameters, 49B active per token and a 1M context. Here is what the benchmarks, demos and serving costs mean.
Prithu Vardhan Mishra is the Founder and Lead Systems Analyst at EyesTech. He leads technical research and editorial investigations across frontier AI models, LLM deployment economics, semiconductor silicon, and aerospace defence technologies. His work focuses on independent benchmarking, real-world agent harness testing, and tactical electronic warfare systems.
Tencent’s Hy4 preview has 770B total parameters, 49B active per token and a 1M context. Here is what the benchmarks, demos and serving costs mean.
A source-led Gemini 3.8 Flash leak tracker separating confirmed Google documentation from secondary reports, rumored specifications, timing, and verification steps.
Qwen3.8 Flash-Next vs GLM-5.3 Flash: the short version Qwen3.8 Flash-Next and GLM-5.3 Flash are not “small models” in the usual…
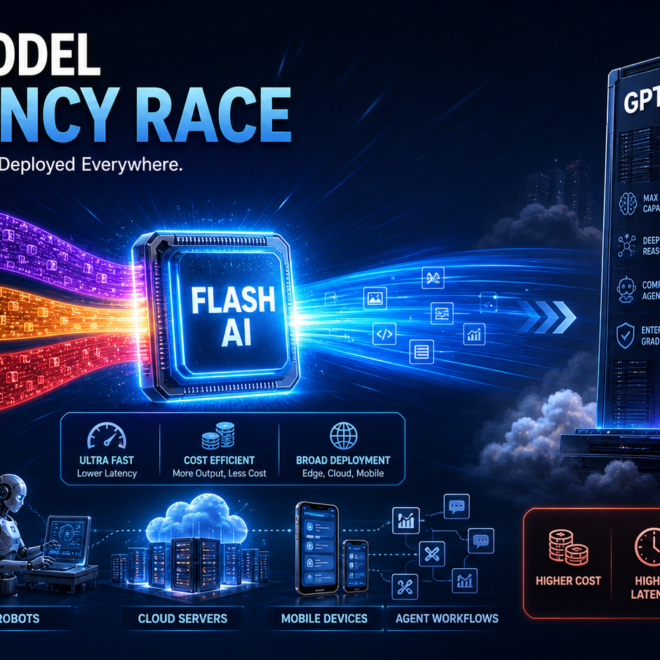
China’s Flash AI models are not a retreat from frontier AI. They are a deployment strategy built around cheaper inference, domestic chips and agents.
Qwen3.8-Flash-Next previews Qwen4 with 6B active parameters, QSA sparse attention and 1M context. We examine benchmarks, caveats and local hardware.

OpenClaude is getting attention because people are saying it is giving Xiaomi MiMo for free. That sounds simple, but the…

The meter is running out of time for IT services companies — and they know it. In the past 18…

Anthropic’s new SpaceX compute deal gives Claude more capacity, higher Claude Code limits, and stronger Claude Opus API throughput. Here…

Developers switching from Claude Code to Codex is not just another AI hype cycle. It is a real shift in…

Google may be preparing one of its biggest Gemini upgrades yet. A new leak suggests that the company is testing…