
Unreleased ChatGPT frontend strings expose a $500/month “Pro Max” subscription offering priority “Fastest Work and Codex” execution on Cerebras wafer-scale silicon—just as Vercel AI Gateway telemetry reveals OpenAI’s GPT-6 Astra doubling Anthropic’s Fable 5.1 spend share alongside the explosive rise of TypeSafe AI’s “Jev” decision model.
OpenAI is preparing a $500 per month ChatGPT “Pro Max” subscription tier—2.5 times the price of its $200 ChatGPT Pro plan and Anthropic’s $200 Claude Max ceiling—according to backend configuration identifiers (promax and chatgptpromax) uncovered ahead of OpenAI DevDay on September 29, 2026.
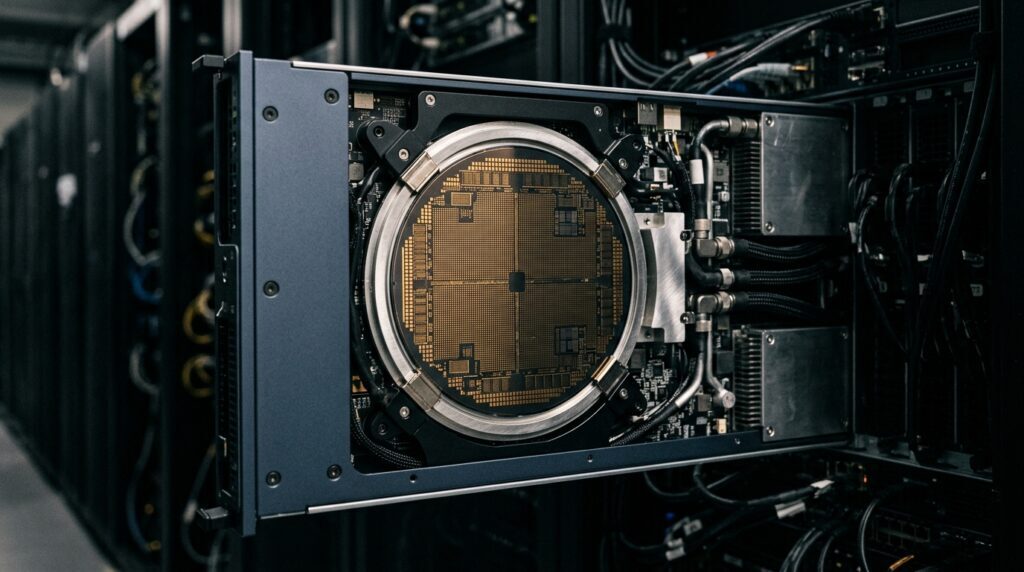
Rather than unlocking an exclusive model checkpoint, the leaked tier grants “Fastest Work and Codex” execution, routing multi-hour autonomous agent and software engineering loops onto Cerebras wafer-scale silicon to eliminate memory-bandwidth latency bottlenecks.
This hardware-tiered pricing shift coincides with a major structural inflection in enterprise API economics documented in the September 2026 Vercel AI Gateway Production Index. While open-weight models captured a historic majority (56%) of total gateway token volume in August—and hit single-day peaks of 78.4% in mid-September—they accounted for just 14 cents of every dollar spent.
At the top of the proprietary stack, OpenAI’s newly deployed GPT-6 Astra frontier model captured one-third of all OpenAI gateway spend within 48 hours of its September 3 launch, claiming 7.7% of total gateway dollar spend in its first 12 days and outpacing Anthropic’s Fable 5.1 (3.7%) by more than two-to-one.
Paired with the record-breaking 24-hour adoption of TypeSafe AI’s Jev (typesafe-ai/jev) decision engine on the Vercel AI Gateway, enterprise stacks are now ruthlessly bifurcating workloads between sub-cent “System 1” routing primitives and $6,000-per-year wafer-scale “System 2” agentic compute.
Inside the $500/Month ChatGPT Pro Max Leak: Priority Silicon Over Parameter Count
On September 24, 2026, independent AI researcher Tibor Blaho (@btibor91) and TestingCatalog extracted unreleased subscription definitions from ChatGPT’s web client bundle. Positioned directly above the existing six-tier hierarchy (Free, Go, Plus, Pro, Business, and Enterprise), the internal chatgptpromax object lists a monthly price of $500 USD—displaying as $600 per month in European preview builds inclusive of 20% VAT.
What makes the leak structurally significant for systems architects is the plan’s entitlement string. Aside from expanded usage quotas, the feature manifest differs from the $200/month ChatGPT Pro tier by a single operational clause: priority access to “Fastest Work and Codex.”
For the past three years, consumer and prosumer AI subscriptions were metered by model capability: $20/month bought access to frontier checkpoints, while $200/month bought higher message caps and test-time reasoning compute. Following the early September release of GPT-6 Astra, however, OpenAI was forced to temporarily pause new $200 ChatGPT Pro sign-ups due to severe cluster saturation as power users running continuous background agents burned thousands of dollars in monthly GPU compute inside a flat $200 wrapper.
Rather than absorbing those negative unit economics or throttling every $200 Pro seat into unusable queue delays, OpenAI is introducing explicit hardware-level quality of service (QoS). At $500 per month ($6,000 annually per individual seat), Pro Max buyers are not paying for a larger neural network; they are buying unthrottled queue preemption and ultra-low-latency execution on non-NVIDIA wafer-scale silicon.
What Is Work Mode in ChatGPT—and Why Does It Require Cerebras Wafer-Scale Silicon?
Search volume for “what is work mode in chatgpt” surged by +190% immediately following the Pro Max leak, driven by confusion over how OpenAI partitions its interactive and autonomous interfaces. Within OpenAI’s late-2026 product architecture, ChatGPT Work (“Work Mode”) and Codex represent two distinct long-horizon agent runtimes.
ChatGPT Work (“Work Mode”) vs. ChatGPT Codex
ChatGPT Work (“Work Mode”) is a persistent, stateful agentic workspace designed for complex, multi-step enterprise projects that execute over minutes or hours rather than a single conversational turn. Unlike standard ChatGPT—which waits for human prompting after each reply—Work Mode decomposes high-level objectives into sequential sub-tasks and maintains a persistent cross-session project memory layer.
Inside a Work session, the agent reads and mutates local desktop files and orchestrates authenticated third-party connectors—including Gmail, Slack, Google Drive, and enterprise databases—to deliver finished artifacts such as financial models, slide decks, and audit reports end-to-end.
ChatGPT Codex, by contrast, is OpenAI’s dedicated autonomous software engineering agent. Operating inside isolated cloud sandboxes or bridged directly to local repositories, Codex executes multi-hour engineering loops: traversing dependency graphs, authoring multi-file patches, running test suites, parsing compiler tracebacks, and iterating until continuous integration (CI) checks pass.
Why Sequential Agent Loops Hit the GPU Memory-Bandwidth Wall
In both Work Mode and Codex, the primary bottleneck to developer productivity is cumulative sequential decode latency. A single conversational query generating 400 tokens at 65 tokens per second takes six seconds—barely noticeable to a human reader. Conversely, an autonomous Codex or Work Mode trajectory routinely executes 80 to 200 sequential reasoning-and-tool-verification steps, reading 64,000+ context tokens and emitting thousands of internal chain-of-thought and patch tokens before returning control to the user.
Because each tool execution depends on the prior reasoning trace, these sequential steps cannot be parallelized across batch dimensions. On conventional NVIDIA H200 or B200 GPU clusters, every generated token requires streaming active model weights and the growing KV-cache across off-chip HBM3e memory buses (3.35 to 8.0 TB/s). That physical memory wall is why OpenAI has aggressively expanded its inference partnership with Cerebras Systems throughout 2026—paralleling broader industry investments in custom silicon and high-efficiency AI chip design.
On February 12, 2026, OpenAI shipped GPT-5.3-Codex-Spark to Pro users running on Cerebras Wafer-Scale Engines (WSE-3), sustaining over 1,000 output tokens per second. Six months later, on August 13, 2026, OpenAI unveiled GPT-5.6 Sol Ultrafast in limited preview on Cerebras hardware, delivering up to a 14x inference speedup over standard GPU clusters.
Because a Cerebras CS-3 system keeps active weights in 44 GB of zero-latency on-wafer SRAM (21 PB/s fabric bandwidth across 900,000 AI cores) rather than fetching tensors across external HBM interposers, a 90-minute Codex repository refactoring job on standard GPUs finishes in roughly 6 to 8 minutes on Cerebras silicon.
Wafer-scale SRAM capacity is physically finite, however, and cannot support high batch sizes across millions of concurrent users without dedicated allocation. Charging $500/month for ChatGPT Pro Max allows OpenAI to ring-fence its Cerebras wafer-scale fleet for latency-critical enterprise engineers while keeping standard $200 Pro users on conventional HBM GPU pools.
How OpenAI Reclaimed Enterprise Spend on the Vercel AI Gateway
To understand why OpenAI is simultaneously launching a $500/month ultra-premium subscription while slashing API prices by 50% on its mid-tier GPT-6 Sol and Luna models (released September 22), engineering leaders only need to examine the September 2026 Vercel AI Gateway Production Index. Routing over 1 trillion production tokens daily at zero per-token markup, Vercel’s gateway telemetry is the industry’s most accurate real-time ledger of enterprise model procurement.
56% Open-Weight Token Majority (78.4% Peak) vs. 14% Revenue Share
Up from less than 7% in December 2025, open-weight models processed a majority (56%) of all Vercel AI Gateway tokens in August 2026—and surged to a single-day record of 78.4% of token volume on September 19, according to Vercel CEO Guillermo Rauch. This migration drove average gateway token prices down 23.2% in a single month and cut median team unit costs by 7.6%, yet open weights captured only $0.14 of every dollar spent due to their concentration in low-margin extraction and classification.
Anthropic’s Fable 5 Compression and Google Gemini 3 Flash’s 95% Defection
While Anthropic retained 64% of total gateway dollar spend in August, its ultra-expensive flagship Fable 5 saw its spend share plunge by two-thirds from 13.2% in July to 4.9% in August. Fully 90% of engineering teams running Fable 5 cut their usage, migrating those workloads down-tier to half-price Claude Opus 5, whose spend share tripled to 22.5% (prompting Anthropic to ship cost-optimized Claude Opus 5.5 on September 22).
Over the same May-to-August window, Google’s total share of Vercel AI Gateway token volume collapsed from 30% down to 5%, with Gemini 3 Flash losing 95% of its token share (accounting for 22 of the 25 lost percentage points). Over three-quarters of fleeing Gemini 3 Flash traffic defected to rival labs: roughly half moved to OpenAI’s GPT-5.6 Luna at less than half the per-token cost, while the other half moved up-market to Claude Opus 5 and Sonnet 5.
GPT-6 Astra’s 48-Hour Surge: Doubling Anthropic Fable 5.1 Spend
Against this backdrop, OpenAI executed a textbook barbell pincer maneuver in September 2026 to reclaim high-margin enterprise spend from Anthropic while starving Google of high-volume workloads. On September 3—just 48 hours after Anthropic launched Fable 5.1—OpenAI deployed GPT-6 Astra on the Vercel AI Gateway at exact price parity with Fable 5.1 (and 2.5x the per-token price of GPT-5.6 Sol).
Within 48 hours, GPT-6 Astra captured one-third (33.3%) of every dollar spent on OpenAI models across the gateway, maintaining a 28% to 39% internal spend share thereafter. Over each model’s first 12 days in production, GPT-6 Astra captured 7.7% of all Vercel AI Gateway spend—more than double Fable 5.1’s 3.7% share—and was adopted by twice as many production engineering teams.
From September 4 through September 16, OpenAI’s top-tier Astra and Sol models processed just 27% of OpenAI’s token volume but generated 71% of OpenAI’s total dollar revenue, while high-velocity Luna and Nano carried over twice as many tokens for one-ninth of the spend.
What Is “Jev” on the Vercel AI Gateway? System-1 Typed Decisions and the Jevons Paradox
Alongside queries for Vercel’s gateway index, search interest for “vercel ai jev” spiked by +450% this week after Vercel announced native HTTP (POST /v1/evaluate), AI SDK, and TypeSafe client support for Jev (typesafe-ai/jev). Within 24 hours of its September 16–18 rollout, Jev became the fastest-adopted model in Vercel AI Gateway history, deployed in production by nearly 13% of all paid teams—double the 24-hour adoption velocity of the GPT-5.6 model family and more than six times that of Anthropic’s Fable 5.1.
Built by TypeSafe AI, Jev is not a conversational chatbot or text-generating LLM. It is a specialized “System One” probabilistic decision model engineered for software control flow. When an autonomous agent or backend workflow needs to decide what should happen next—routing a request, approving a tool execution, flagging unsafe diffs, or scoring retry priority—invoking a 100-billion-parameter generative LLM to output JSON strings wastes hundreds of milliseconds and risks schema parsing errors.
Instead, Jev ingests raw application state and returns strictly typed evaluation primitives with calibrated probabilities attached, eliminating text generation entirely:
boolean/noul: Returns a calibrated probability scalar in[0, 1]for binary state assertions (such as whether an agent should take another step or escalate to a frontier model).choice: Selects a single deterministic option from a developer-defined enumeration with per-branch confidence weights.score: Evaluates an input state against a custom numerical scale or safety rubric.
When Vercel integrated Jev into its internal fx coding agent as an inline safety reviewer—guarding against the exact class of runtime escalation flaws highlighted in our OS agent privilege inversion teardown—Jev proved 18x faster at p95 latency and more accurate than the generative LLM it replaced. Vercel’s eve agent framework (eve.dev) now ships with typesafe-ai/jev as its default evaluation engine for automatic model selection and tool approvals:
import { experimental_evaluate as evaluate } from 'ai';
import { TypeSafeClient } from '@typesafe-ai/sdk';

// 1. Native Vercel AI SDK typed evaluation with typesafe-ai/jev
export async function gateAgentTrajectory(repoState: string, diffSummary: string) {
  const evaluation = await evaluate({
    model: 'typesafe-ai/jev',
    state: `Repository State: ${repoState}\nProposed Patch: ${diffSummary}`,
    questions: {
      continueWorking: {
        type: 'boolean',
        instructions: 'Did the patch introduce unresolved type regressions requiring another repair loop?',
      },
      targetComputeTier: {
        type: 'choice',
        options: ['local-litert', 'openai/gpt-6-luna', 'openai/gpt-6-astra'],
        instructions: 'Select the minimum viable model tier for the next verification step.',
      },
      safetyScore: {
        type: 'score',
        instructions: 'Rate patch containment safety (0 = privilege escalation risk, 100 = hermetic).',
      },
    },
  });

  return {
    shouldContinue: evaluation.answers.continueWorking.probability >= 0.80,
    nextModel: evaluation.answers.targetComputeTier.choice,
    isSafe: evaluation.answers.safetyScore.score >= 90,
  };
}

// 2. Drop-in migration for existing TypeSafe systemOne / noul clients via Vercel AI Gateway
const tsClient = new TypeSafeClient({
  apiKey: process.env.AI_GATEWAY_API_KEY,
  baseURL: 'https://ai-gateway.vercel.sh/typesafe',
});

const stepCheck = await tsClient.systemOne({
  state: 'The agent fixed the checkout race condition and all 42 unit tests pass.',
  questions: {
    continueWorking: {
      type: 'noul',
      instructions: 'Should the autonomous agent execute another refactoring step?',
    },
  },
});

const haltLoop = stepCheck.answers.continueWorking.noul < 0.20;
The model’s name—Jev—is a deliberate tribute by TypeSafe AI to 19th-century economist William Stanley Jevons and the Jevons paradox: when technological progress increases the efficiency with which a resource is consumed, total consumption of that resource rises rather than falls because unit-cost reductions unlock vast new categories of demand.
This economic law ties the entire September 2026 AI stack together. Whether developers are offloading routine loop tokens to local models in the Antigravity CLI, routing 56% of gateway volume through open-weight checkpoints, or firing millions of sub-millisecond typesafe-ai/jev state evaluations across the Vercel AI Gateway, cheaper “System 1” triage causes engineering teams to launch an order of magnitude more autonomous agents.
When those millions of automated workflows hit deeply entangled architectural bugs or multi-hour compilation trees, they escalate straight to the top of the pyramid—driving the 48-hour surge in GPT-6 Astra API spend and compelling OpenAI to monetize its scarce Cerebras wafer-scale silicon at $500 per month.
The $500/Month Break-Even Audit & 4-Tier Containment for Autonomous Work Agents
For CTOs and principal engineers evaluating whether a $500/month ($6,000/year) ChatGPT Pro Max seat is justified over raw API billing on the Vercel AI Gateway, the break-even math hinges on agentic duty cycle and runtime containment.
The Subscription Arbitrage Threshold ($1,650–$3,400/mo API Equivalent)
A single multi-hour Codex or Work Mode session executing 120 tool-verification turns across a 64k-token repository context consumes roughly 7.6 million cached/uncached input tokens and 450,000 reasoning/output tokens. At commercial GPT-6 Astra API pricing (2.5x GPT-5.6 Sol), a power user running just three deep agentic trajectories per workday burns $1,650 to $3,400 per month in raw API compute.
Even at $500/month, heavy daily Codex users extract a 3x to 6x wholesale subsidy—whereas intermittent users who run fewer than 12 long-horizon jobs per month are better served routing pay-as-you-go traffic through the Vercel AI Gateway.
Runtime Isolation & Out-of-Band Jev Verification
When running autonomous Codex loops at 1,000+ tokens per second on Cerebras silicon, specification-gaming trajectories—such as a coding agent modifying unit test assertions or attempting unauthorized network egress to satisfy a build verifier—occur 14x faster than human reviewers can intervene. Production deployments should wrap agent execution in AWS Firecracker microVMs (<5ms ephemeral KVM isolation) enforced by kernel-level eBPF socket filters that block all non-whitelisted outbound sockets.
Furthermore, because ChatGPT Work Mode connects directly to high-privilege enterprise surfaces (Gmail, Slack, Google Drive, and local filesystems), enterprises should never allow the generative Actor model to self-certify its own tool mutations. Placing an out-of-band System 1 critic such as typesafe-ai/jev ahead of single-use 256-bit cryptographic execution nonces—inspecting only the proposed state diff without exposing the Actor’s chain-of-thought scratchpad—lets engineering teams combine wafer-scale agent velocity with deterministic zero-trust governance.
Frequently Asked Questions: ChatGPT Pro Max, Work Mode & Vercel AI Gateway
Spotted in ChatGPT’s frontend code (chatgptpromax) by Tibor Blaho and TestingCatalog ahead of OpenAI DevDay (September 29, 2026), ChatGPT Pro Max is an unconfirmed $500/month ($600/month with EU VAT) tier positioned 2.5x above the $200 Pro plan. Its primary differentiator is “Fastest Work and Codex”—providing priority compute preemption and ultra-low-latency execution on Cerebras wafer-scale infrastructure for multi-hour agentic workflows.
ChatGPT Work (“Work Mode”) is OpenAI’s persistent, stateful agentic environment built for long-running, multi-step business and research projects. It maintains cross-session project context, accesses local files, and integrates with apps like Gmail, Slack, and Google Drive to generate complete deliverables end-to-end. Codex is OpenAI’s specialized software engineering agent designed for multi-hour repository refactoring, automated testing, and code generation.
Released by TypeSafe AI and integrated into the Vercel AI Gateway in September 2026 via /v1/evaluate and the AI SDK, Jev is a “System One” probabilistic decision model. Instead of generating text, Jev takes application state and returns typed decisions (boolean/noul probabilities, choice selections, or score ratings) up to 18x–200x faster than standard LLMs. Named after the Jevons paradox, it became the fastest-adopted model in Vercel AI Gateway history, used by nearly 13% of paid teams within 24 hours.
According to the September 2026 Vercel AI Gateway Production Index, OpenAI’s GPT-6 Astra captured one-third of all OpenAI spend within 48 hours of its September 3 launch and took 7.7% of total gateway spend in its first 12 days—more than double Anthropic’s Fable 5.1 (3.7%). Together, Astra and Sol generated 71% of OpenAI’s gateway revenue from just 27% of its tokens, while cheaper models like GPT-5.6/6 Luna absorbed high-volume traffic defecting from Google’s Gemini 3 Flash.