
Google launched Gemini 4 Argon with 1M output tokens, a 77.9% DeepSWE score, and $2/M input pricing. Here is our architectural and benchmark teardown.
Independent evaluations of synthetic benchmark claims: ARC-AGI-3, SWE-bench Verified, HumanEval, and live latency audits.
Google launched Gemini 4 Argon with 1M output tokens, a 77.9% DeepSWE score, and $2/M input pricing. Here is our architectural and benchmark teardown.
pg-jev evaluates Postgres rows through a decision API. Batches of 20 and session caches change cost; LIMIT 3 does not guarantee three billed rows.
MiniCPM-V 4.7 reports 13+ tokens/s in 3GB phone memory. Expert loading, quantization and speculation explain why that is not its total weight size.
Muse Wonder costs $4/$20 per million input/output tokens. Full requires a Muse Code plan; max reasoning changes effort, not the model you access.
NVIDIA Research’s Low-Rank Gradient Sketches (LoGRA) algorithm reduces reinforcement learning optimizer VRAM consumption by 45.7% on 7-billion-parameter…
Frontier artificial intelligence has crossed an empirical threshold where raw web-scale token ingestion no longer yields qualitative…
Iris-3B generates pixels without a VAE. Its released depth and restoration results show no clear advantage; a 4B text encoder also changes local costs.
Saluki packs Qwen3.8-27B into 7.89GB. Its 88/120 tool score hides lost and gained tasks, parser sensitivity and memory costs beyond the model file.
Strata runs 125B Qwen3.8-Flash-Next on 12GB VRAM at 45 tok/s using predictive expert prefetching and io_uring. Here is the PCIe math and setup.
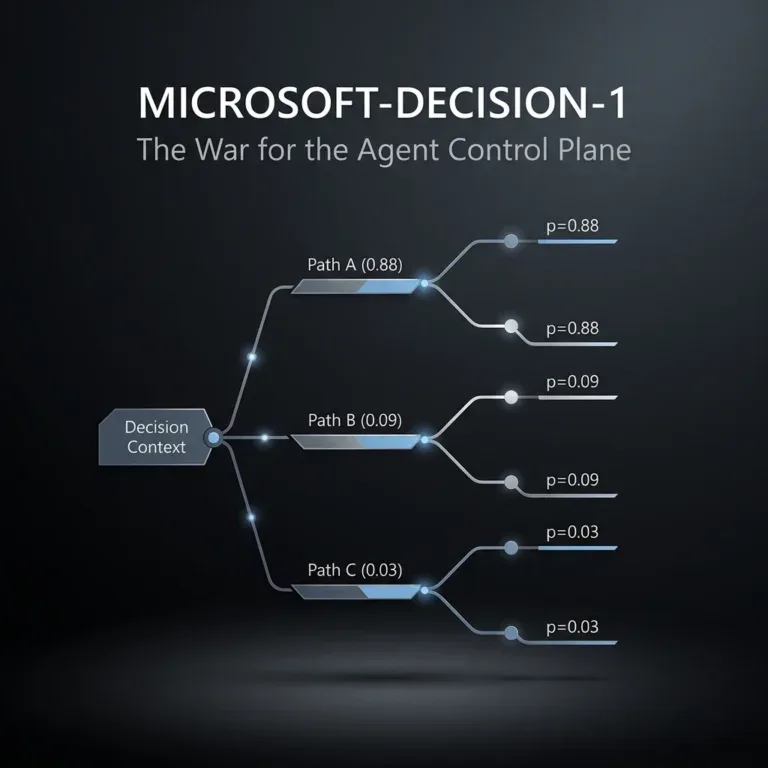
Microsoft-Decision-1 brings 85ms scoring to Azure for $0.042/1M tokens, but WAN transit taxes and 0.4B local models challenge its agent control plane.