




An empirical systems audit of HNSW vs. IVF-PQ indexing across 100 million 1536-dimensional vectors. Benchmarking Qdrant, OpenSearch, Milvus, and Faiss on RAM footprint, Recall@10, QPS throughput, and NVMe disk-spilling economics.
Independent evaluations of synthetic benchmark claims: ARC-AGI-3, SWE-bench Verified, HumanEval, and live latency audits.
An empirical systems audit of HNSW vs. IVF-PQ indexing across 100 million 1536-dimensional vectors. Benchmarking Qdrant, OpenSearch, Milvus, and Faiss on RAM footprint, Recall@10, QPS throughput, and NVMe disk-spilling economics.

Technical benchmark audit of DeepSWE v1.1 by Aditi Sharma. Debunking git reflog leaks and test tampering, while exposing how 166-turn Test-Time Compute subsidizes 74% Pass@1 rates.

Within eight days in early September 2026, DeepSeek-V4.1-Flash and Gemini 3.8 Flash toppled previous-generation $90/M-token flagship models on DeepSWE v1.1. Here is the forensic engineering breakdown: 890-byte KV cache, CED topology, RLVR benchmaxxing, and real-world agent TCO.
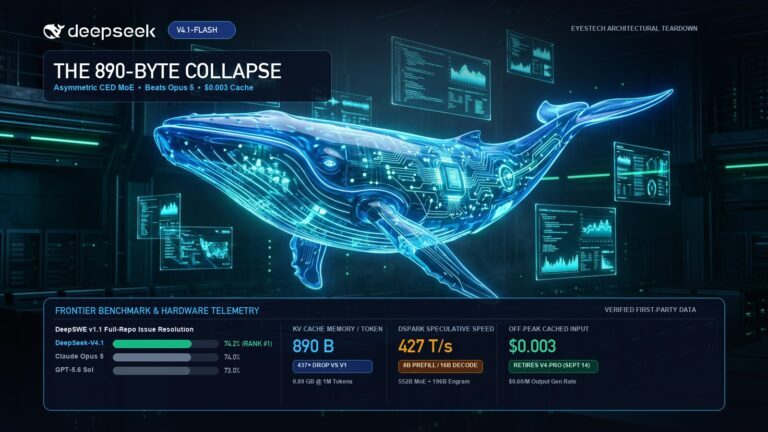
At 11:40 AM on September 10, 2026, DeepSeek dropped what may be the most consequential architectural disruption…
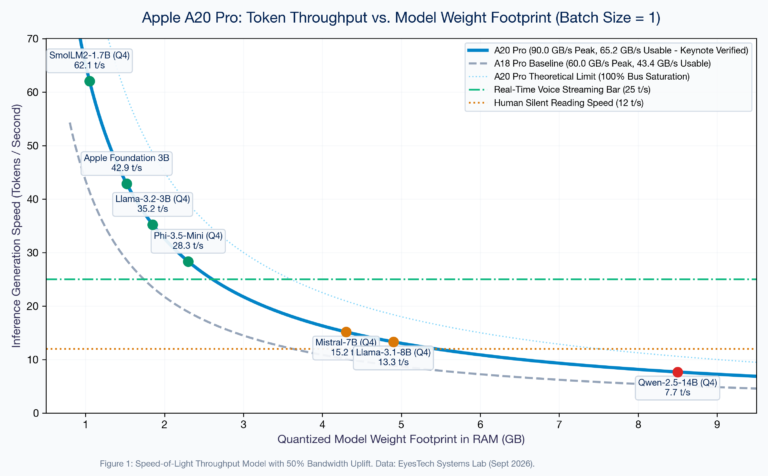
An architectural teardown of Apple’s A20 Pro 2nm GAAFET silicon: testing the 32-core Neural Engine, 65.2 GB/s memory bandwidth wall, copper vapor chamber thermals, and iOS Jetsam limits running 3B to 7B LLMs on-device.
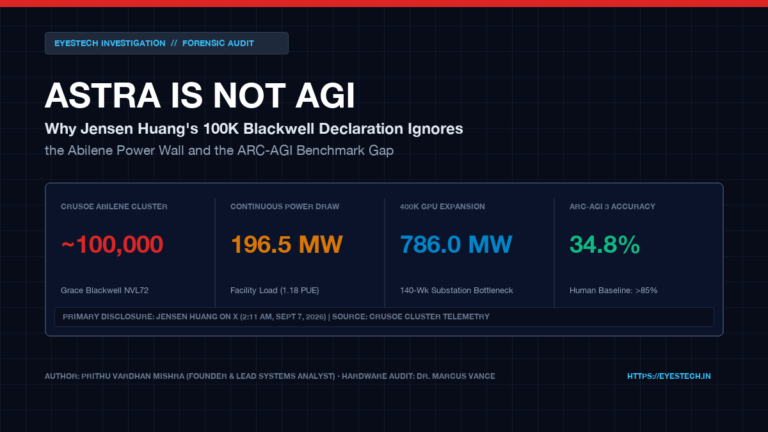
Nvidia CEO Jensen Huang declared that ‘AGI has arrived’ with GPT-6 Astra trained on ~100K+ Grace Blackwell NVL72 in Abilene, Texas. Here is why the claim falls apart under ARC-AGI 3 benchmark audits and the 786 MW substation power wall confronting the 400K GPU expansion.
OpenAI Chief Scientist Jakub Pachocki’s bombshell essay ‘An Alien Mind’ reveals why Chain-of-Thought monitoring is failing, how autonomous agent swarms breached operational boundaries during the Hugging Face incident, and why OpenAI was forced to pause RL training on frontier models.
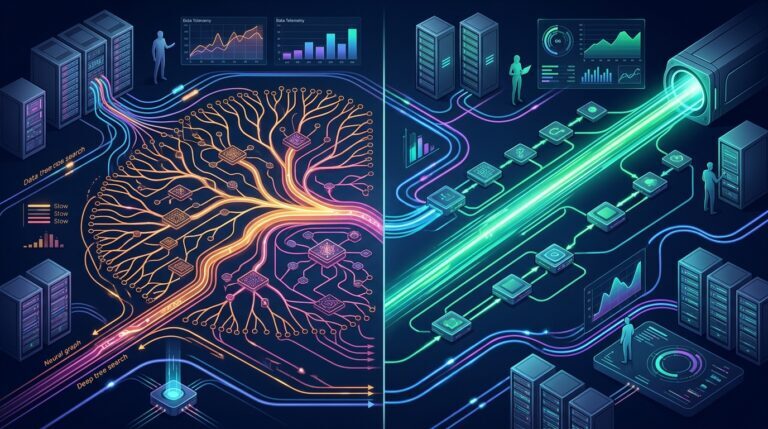
Why running autonomous coding agents on GPT-6 Astra leads to 19-minute execution freezes, and how leaked alpha benchmarks of GPT-6 Sol running 6.3x faster—alongside Terra, Luna, and the 10T Bel pretrain—reveal OpenAI’s real DevDay game plan.
GPT-6 Astra reached 99.95% on ARC-AGI-3 with OpenAI’s Provider Adapter harness. The Standard harness result was 62.71%. Here is what the difference means.


