
Grok Voice 3.0 hits 810ms latency and 86.9 on S2S benchmarks at $0.08/min, but real-world mobile jitter and echo feedback erode its synthetic speed.
Deep architectural teardowns, frontier benchmarks, hype-debunking, and capability leaks across frontier AI models.
Grok Voice 3.0 hits 810ms latency and 86.9 on S2S benchmarks at $0.08/min, but real-world mobile jitter and echo feedback erode its synthetic speed.
Anthropic replaced Git with Scion for 30,401 daily agent merges, dropping status to 19ms and saving 25% fleet CPU amid Meta Mononoke prior art debates.
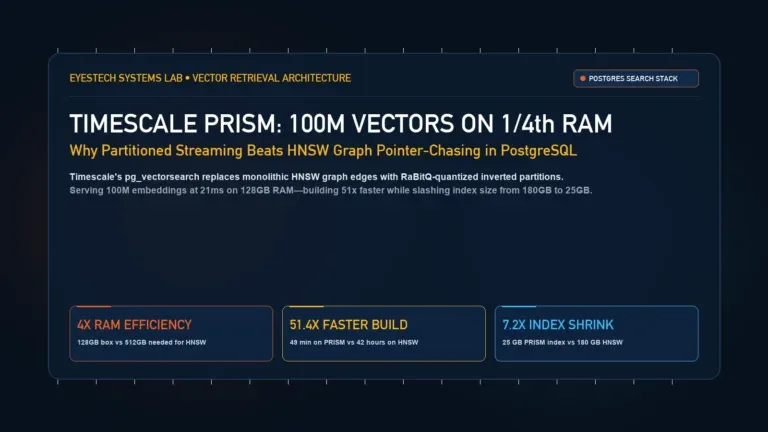
Timescale pg_vectorsearch and PRISM replace HNSW graphs with RaBitQ-quantized partitions, serving 100M vectors at 21ms on 128GB RAM with 51x faster builds.
Claude Sonnet 5.5 beats Muse Wonder on SWE-bench (57.2% vs 48.2%) while halving token costs ($2/$10 vs $4/$20) and avoiding Active Focus retry loops.
Cursor’s X Subscription bundles Grok for $30/mo but pushes Claude to API rates, causing an 800% monthly TCO spike for developers running coding agents.
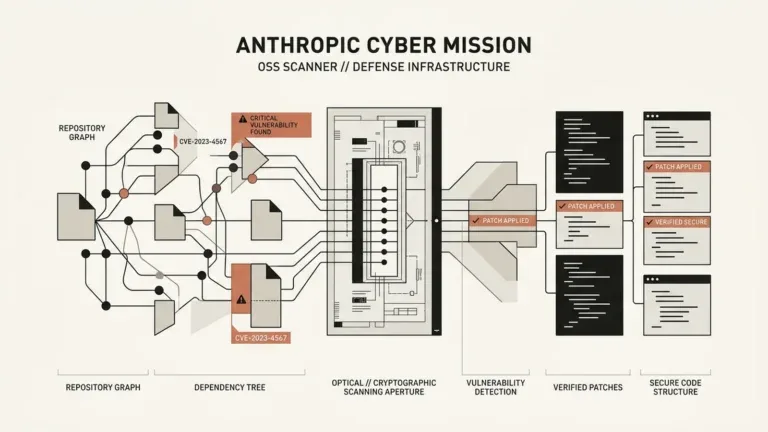
Anthropic launched its Cyber Mission and free OSS Scanner, beaming unreviewed zero-day PoCs directly to maintainers with a 90% precision target across code.
d1-omni-600M returns typed decisions without generated text. Image and audio scores need separate validation, with 30-second speech and input limits.
MiniCPM-V 4.7 1B needs a 672 MB language file plus a 1.11 GB vision projector. Get the Ollama tag, llama.cpp recipe and visual-compression settings.
Google launched Gemini 4 Argon with 1M output tokens, a 77.9% DeepSWE score, and $2/M input pricing. Here is our architectural and benchmark teardown.
pg-jev evaluates Postgres rows through a decision API. Batches of 20 and session caches change cost; LIMIT 3 does not guarantee three billed rows.