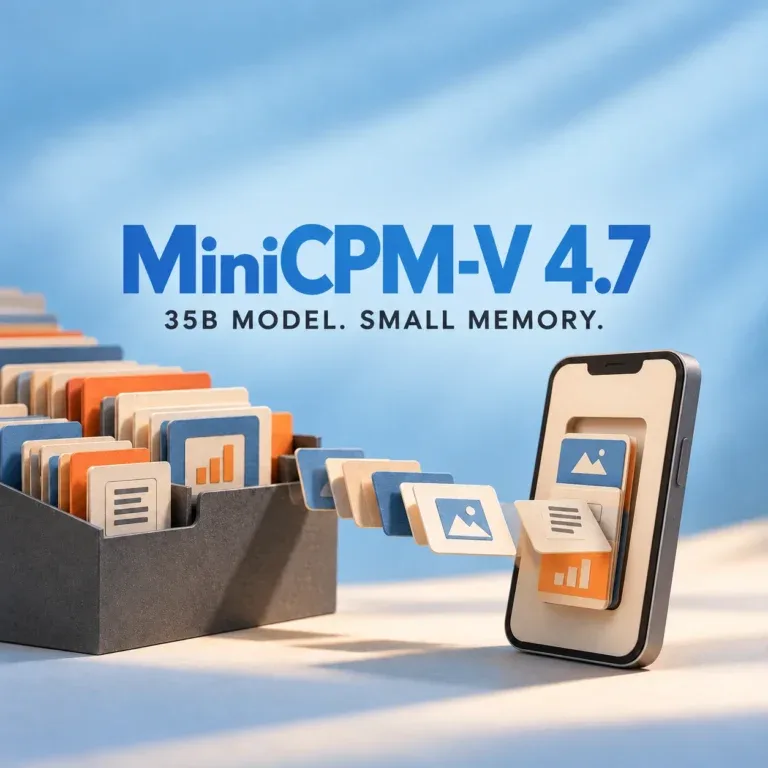
MiniCPM-V 4.7 reports 13+ tokens/s in 3GB phone memory. Expert loading, quantization and speculation explain why that is not its total weight size.
Deep architectural teardowns, frontier benchmarks, hype-debunking, and capability leaks across frontier AI models.
MiniCPM-V 4.7 reports 13+ tokens/s in 3GB phone memory. Expert loading, quantization and speculation explain why that is not its total weight size.
Muse Wonder costs $4/$20 per million input/output tokens. Full requires a Muse Code plan; max reasoning changes effort, not the model you access.
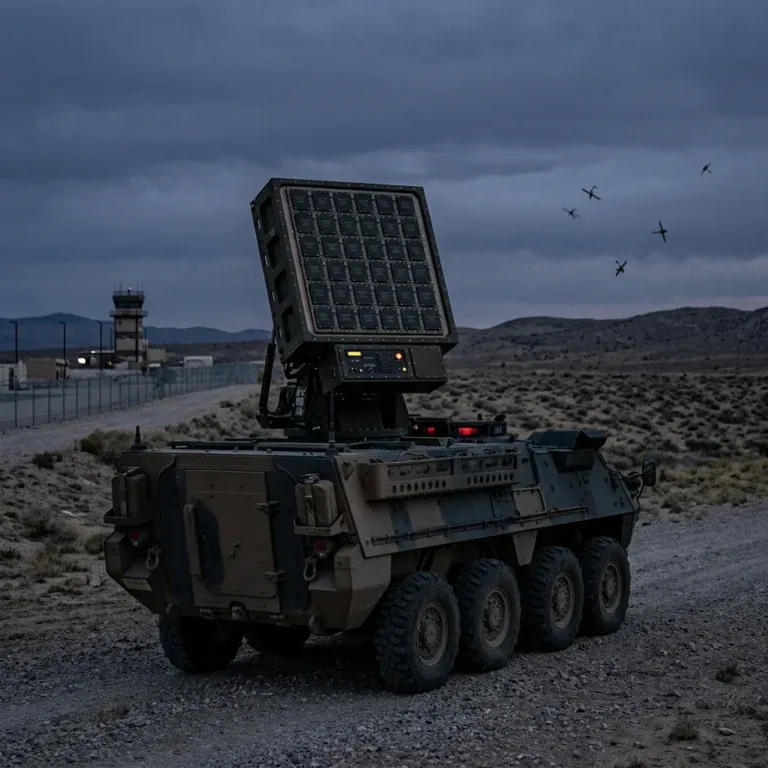
Solid-state GaN HPM arrays disable dozens of drones in microseconds, bypassing 3-5s laser dwell limits and frying unshielded PCB traces at 15-30V surges.
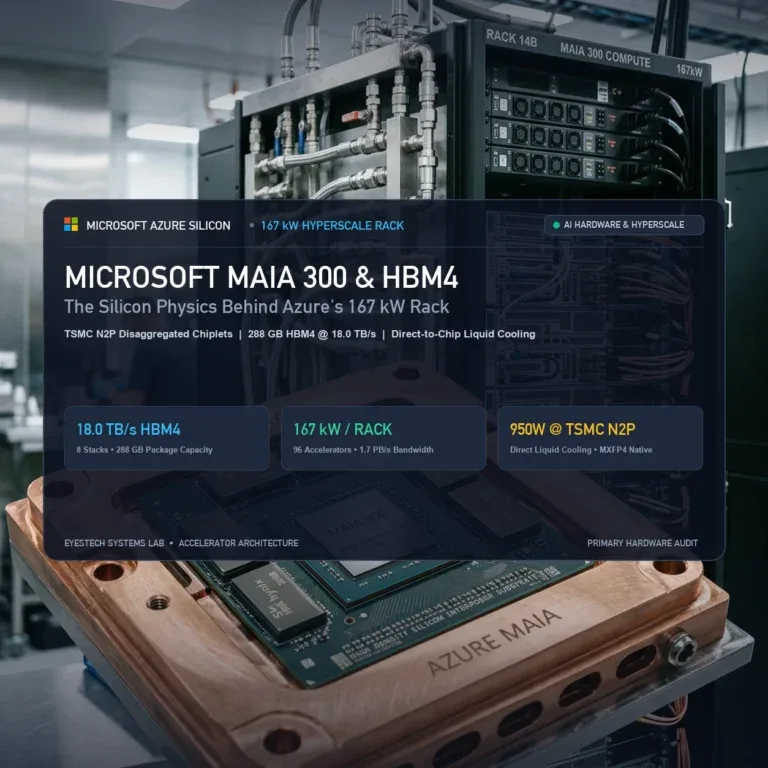
Microsoft Maia 300 pairs 288GB HBM4 at 18 TB/s on TSMC N2P across 96-chip 167 kW racks, bypassing Nvidia memory walls via direct-to-chip liquid cooling.
NVIDIA Research’s Low-Rank Gradient Sketches (LoGRA) algorithm reduces reinforcement learning optimizer VRAM consumption by 45.7% on 7-billion-parameter…
Frontier artificial intelligence has crossed an empirical threshold where raw web-scale token ingestion no longer yields qualitative…
Iris-3B generates pixels without a VAE. Its released depth and restoration results show no clear advantage; a 4B text encoder also changes local costs.
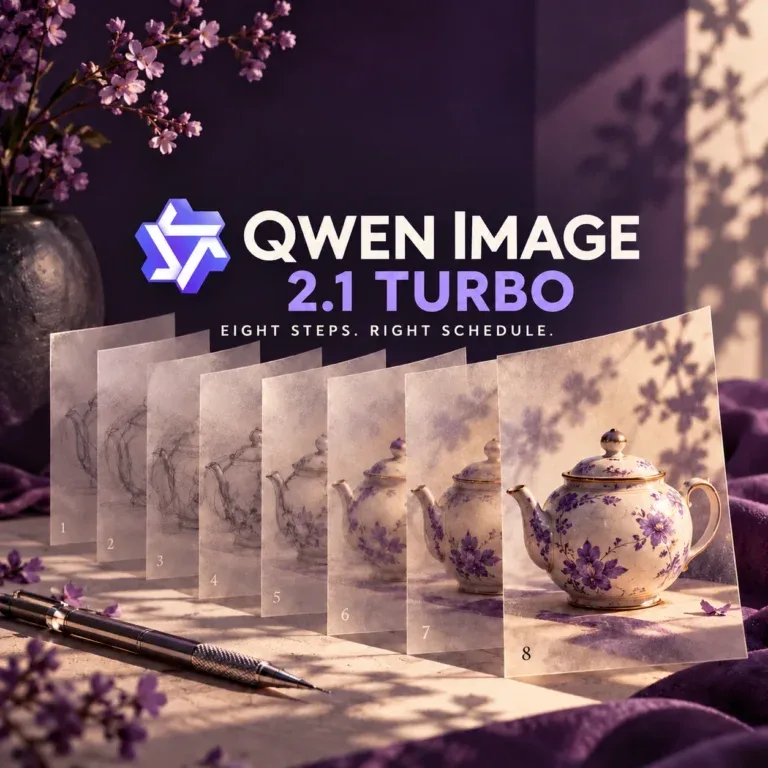
Qwen Image 2.1 Turbo uses a saved eight-step schedule and CFG 1. Local setup needs current Diffusers; commercial use needs a separate license.
Saluki packs Qwen3.8-27B into 7.89GB. Its 88/120 tool score hides lost and gained tasks, parser sensitivity and memory costs beyond the model file.
Strata runs 125B Qwen3.8-Flash-Next on 12GB VRAM at 45 tok/s using predictive expert prefetching and io_uring. Here is the PCIe math and setup.