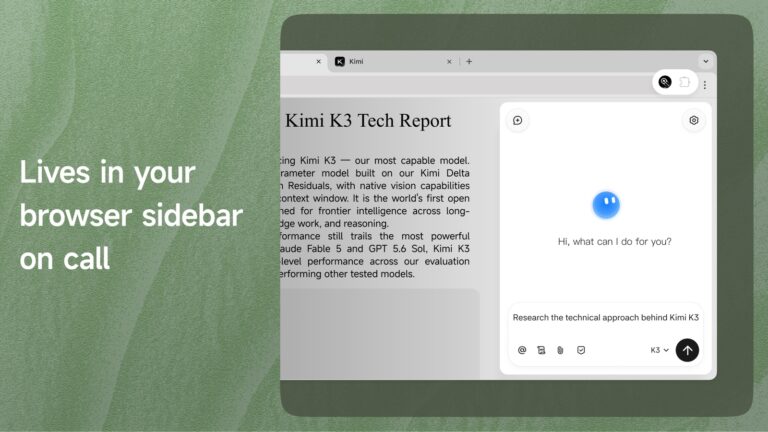
Moonshot AI has officially launched the Kimi Browser Extension in Chrome, delivering local CDP-driven co-browsing and a breakthrough ‘Skill’ distillation engine without cloud VM security risks.
Hands-on analysis, benchmarks, and workflows for AI coding agents, IDEs, harnesses, and multi-agent development.
Moonshot AI has officially launched the Kimi Browser Extension in Chrome, delivering local CDP-driven co-browsing and a breakthrough ‘Skill’ distillation engine without cloud VM security risks.
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
JPMorgan capped Claude Code at $2,000/mo. Here is the Devspace sandbox architecture, token purchasing power math, and the 3-tier enterprise budget matrix.
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
OpenAI announced an internal model it began training 24 days ago has already resolved 100+ open math conjectures and Navier–Stokes. Here is the audit of AGMAI, Lean 4, and the Fields Medalist revolt.
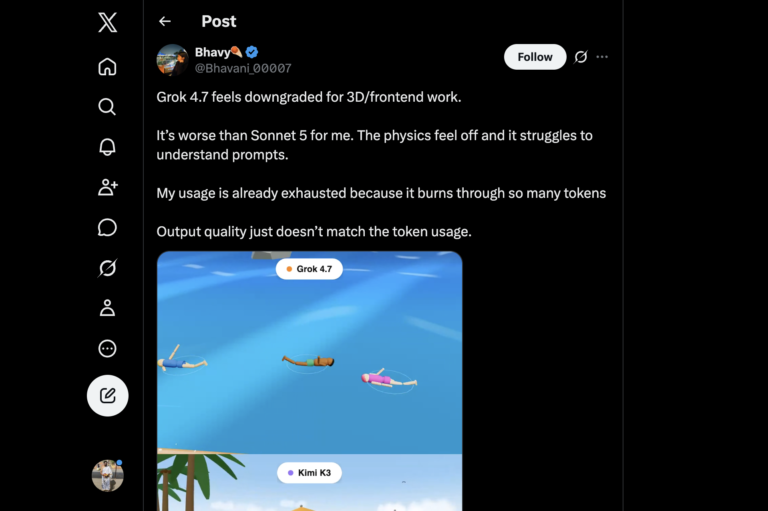
Real-world Grok 4.7 testing reveals severe quota burn, 3D benchmark regressions, and context degradation despite advertised 46.3% CursorBench gains.
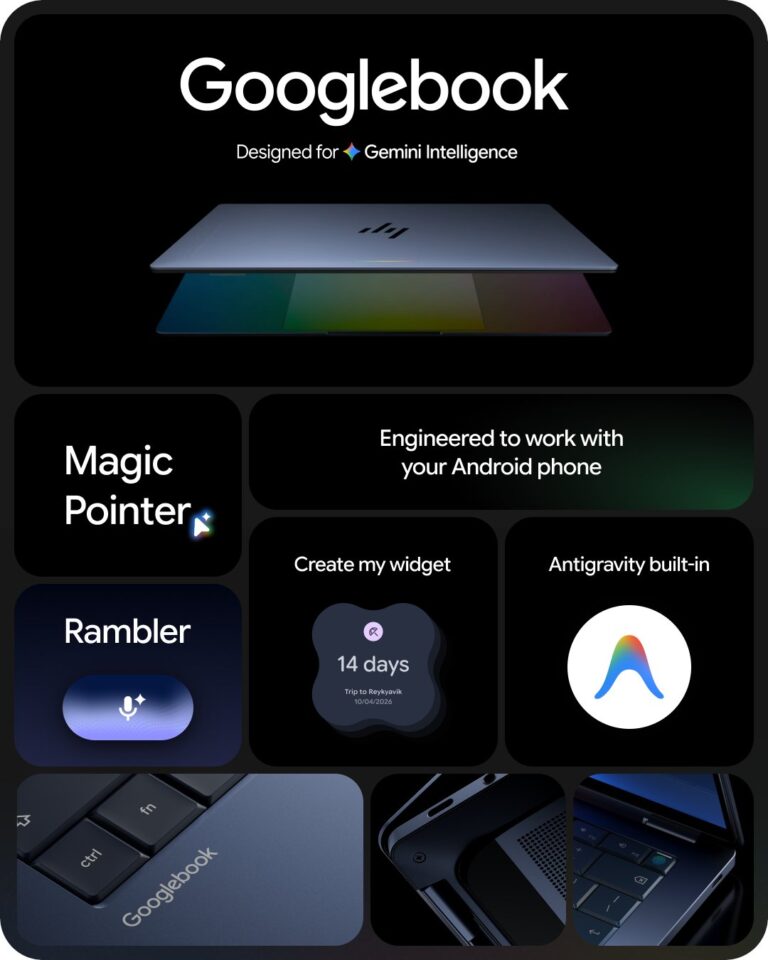
Google launched Googlebook at $899 across Acer, ASUS, Dell, HP, and Lenovo. Built natively on Android with 45+ TOPS NPUs, Magic Pointer, Rambler, and a Level-5 certified pKVM Linux terminal for Antigravity and Claude Code.
DeepSeek V5 leaks claim 78.6% DeepSWE and $0.20/M tokens vs Astra’s $50. Forensic benchmark audit, hardware sizing, and enterprise deployment guide.
xAI releases Grok 4.7: 46.3% on CursorBench 4.0, 71.0% DeepSWE, and 64% EEBench at $2/$6 per million tokens. Delivers multi-hour verified agentic coding.
For three years, enterprise engineering forced autoregressive LLMs into programmatic workflows. TypeSafe AI’s Jev proved why we were wrong—and why System 3 is next.