
Despite advertised gains of 46.3% on CursorBench 4.0 and a massive 2.1T parameter base, Grok 4.7 triggered immediate developer backlash upon its September 21, 2026 debut. Production testers on X documented severe spatial reasoning regressions in 3D WebGL synthesis, broken limb kinematics, and a 33% weekly SuperGrok Heavy quota exhaustion within hours due to unoptimized recursive reasoning loops.
- 3D & Spatial Physics Failure: Grok 4.7 failed basic Three.js fluid and avatar kinematics, trailing far behind Kimi K3, Sonnet 5, and Fable.
- Severe Quota Burn: The Grok Build autonomous harness burned 31% of $300/month heavy allocations during routine introductory tasks.
- Synthetic Benchmark Divergence: Automated test suites failed to reflect production developer utility, prompting widespread calls for human-evaluated leaderboards.
The hype cycle in frontier artificial intelligence follows a predictable ritual: marketing teams publish carefully staged benchmark scorecards, executive accounts declare unassailable leaps in reasoning, and synthetic test suites validate every claim. Then actual software engineers run the model on their production workloads.
When xAI deployed Grok 4.7 into production on September 21, 2026, the contrast between promotional metrics and live developer reality was immediate. Within hours of the model hitting Cursor, Grok Build, and the xAI API, technical feeds across X filled with side-by-side screen recordings, broken WebGL scenes, and depleted quota dashboards. For engineers who rely on fast context iterations, reliable spatial synthesis, and predictable API expenses, Grok 4.7 did not feel like an upgrade. It felt like an expensive bottleneck.
Visual and 3D Synthesis Breakdown: Broken Physics and Lost Battles
The sharpest technical indictment came from graphics engineers and frontend developers testing real-time 3D pipelines. Generative code for WebGL, Three.js, and browser physics engines is an uncompromising stress test: if an LLM lacks genuine spatial understanding and semantic coordination, the browser viewport exposes the defect instantly.
The Swimmer Kinematics Failure: Grok 4.7 Versus Kimi K3
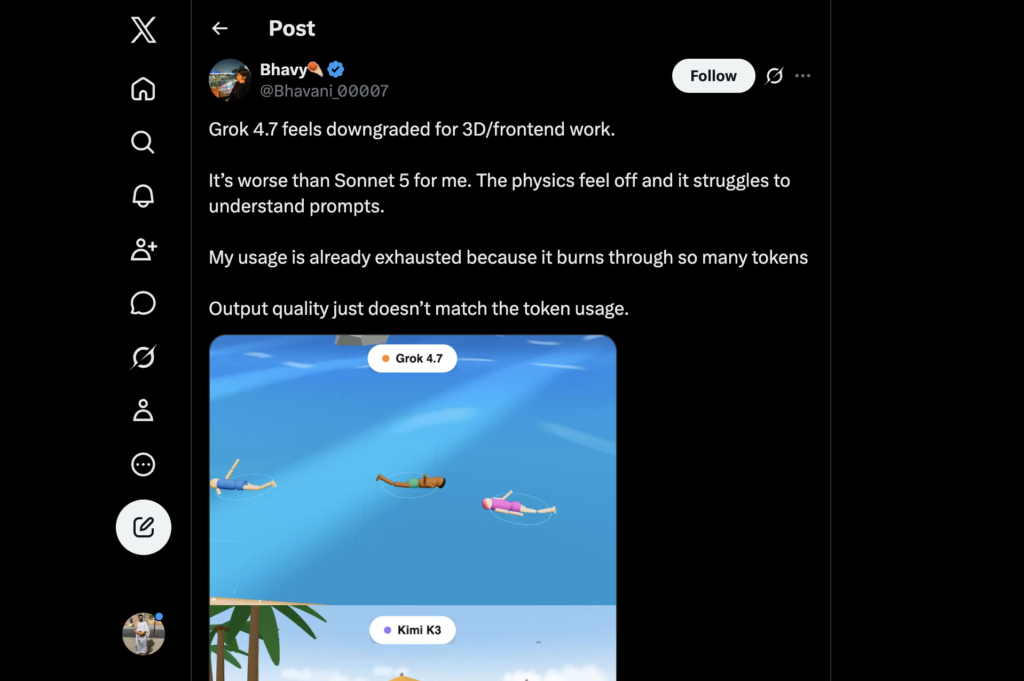
Frontend builder Bhavy (@Bhavani_00007) executed identical scene generation prompts across competing models and published direct screen recordings of the output. Play the embedded video demo below to examine the physics failure and compare it against competing generations:
Grok 4.7 feels downgraded for 3D/frontend work.
— Bhavy☄️ (@Bhavani_00007) September 21, 2026
It’s worse than Sonnet 5 for me. The physics feel off and it struggles to understand prompts.
My usage is already exhausted because it burns through so many tokens
Output quality just doesn’t match the token usage. https://t.co/Lfpafr1ogK pic.twitter.com/BTWMv8THdZ
A detailed inspection of the video demonstrates why developers were troubled. Grok 4.7 placed three human avatars horizontally in a featureless blue void. The limb geometry was unattached, vertex displacement on the surrounding plane was nonexistent, and environmental illumination was completely absent. The code resembled a crashed physics routine rather than a cohesive 3D build.
In contrast, the same prompt fed into Kimi K3 yielded a production-grade 3D environment complete with volumetric ocean waves, populated terrain, beach umbrellas, volleyball nets, and accurate sunlight shaders.
Bhavy elaborated on the operational impact in his technical follow-up: “Grok 4.7 feels downgraded for 3D/frontend work. It is worse than Sonnet 5 for me. The physics feel off and it struggles to understand prompts. My usage is already exhausted because it burns through so many tokens. Output quality just does not match the token usage.”
Technical peers validated the finding. Engineer Tim Jayas (@TimJayas) highlighted the contradiction between automated leaderboards and practical implementation: “Kimi-k3 cooks Grok 4.7 in every 3d build but somehow grok 4.7 is better than kimi in intelligence in AA [Artificial Analysis benchmarks].” Indie builder Sahil Panhotra (@SahilPanhotra) offered a concise summary: “shit not good as hype.”
The Pirate Ship Benchmark: Why Fable Exposed the Credibility Gap
Automated code completion scores often reward syntactic correctness while penalizing nothing regarding stylistic depth or visual sophistication. Technical commentator Da7em (@Da7_Tech) conducted a direct comparative rendering trial, instructing both Grok 4.7 and Fable to synthesize an interactive WebGL pirate ship traversing ocean swells during sunset.
Play Da7em’s side-by-side comparison video below to see the generational contrast in real time:
Look at the gap between Grok 4.7 and Fable.
— Da7em (@Da7_Tech) September 21, 2026
Benchmarks have lost all credibility. pic.twitter.com/77y8e07p14 https://t.co/u048YYMkBu
The visual divergence is unmistakable. Fable rendered an expansive seascape with volumetric dusk illumination, dynamic ocean displacement with foam shaders, and detailed nautical rigging. Grok 4.7 produced a rigid polygon mesh that resembled rudimentary CAD geometry rather than a production-ready WebGL demo.
Da7em followed his side-by-side clip with a definitive observation: “Look at the gap between Grok 4.7 and Fable. Benchmarks have lost all credibility.” In the replies, developer Paolo (@thatdudepacoAI) noted: “Grok 4.7 is disappointing. I just want a cheap Grok model with Fable-level performance. Grok bot would be insane at Fable level too. My big hope remains the Grok 5 + Composer 3.0 combination.” Practitioner SneezeJay (@Sneeze_jay) added: “yeah most of them, we need human benchmarks.”
The Quota Burn Dilemma: How Grok Build Drains SuperGrok Heavy Accounts
Disappointment over generation aesthetics was compounded by a severe economic issue: unprecedented token consumption that rapidly exhausted subscription quotas without proportional output quality.
SuperGrok subscriber Just_Lingonberry_352 (@JustLingonberry) documented the quota collapse with direct account telemetry, tagging Elon Musk and SpaceXAI. The verified post and live telemetry card are embedded below:
testing grok 4.7 xhigh
— Just_Lingonberry_352 (@JustLingonberry) September 21, 2026
so far there's no indication of any improvement over 4.6 xhigh
in fact it seems to drain weekly usage even faster now
very disappointing @elonmusk @SpaceXAI this shit ain't worth $300/month pic.twitter.com/WHsgdYqZQV
The telemetry graph confirms that 33% of the entire Weekly SuperGrok Heavy limit evaporated during a single preliminary testing session. Grok Build consumed 31% of the total budget, while Image generation (1%) and Automations (1%) remained idle. For teams paying $300 per seat, encountering quota starvation on day one of a seven-day cycle fundamentally undermines enterprise adoption.
The comment thread reflected widespread consensus among verified builders:
Forensic Architectural Diagnosis: Why Grok 4.7 Stumbled
Why would a 2.1-trillion parameter architecture optimized with intensive reinforcement learning exhibit visible performance degradations in practitioner workflows? A forensic examination points to three distinct architectural friction points:
1. Autonomous Agent Harness Over-Fitting
Grok 4.7 was explicitly trained to operate within xAI’s autonomous Grok Build harness, running terminal-based build-test-debug loops. When a model undergoes extensive RL on multi-step error correction scripts, it develops strong tendencies toward recursive self-verification. In interactive conversational development or single-turn 3D generation, this manifests as hidden scratchpad token explosion, redundant inner monologue, and severe generation latency.
2. The Parameter Scaling Fallacy in Spatial Reasoning
Expanding base model capacity by 40% (from 1.5T to 2.1T parameters) improves memorization and formal symbolic reasoning on established codebases. However, 3D coordinate mapping, physics vector calculation, and shader logic require dense multimodal grounding rather than raw parameter volume. Adding weights without refining spatial training tokens resulted in bloated outputs that missed basic visual coherence.
3. The Deceptive Invariance of Token Pricing
xAI marketed Grok 4.7 with unchanged token pricing ($2 per million input tokens, $6 per million output tokens). However, because the model produces substantially higher internal scratchpad tokens and conversational scaffolding to complete the same operational task, the effective expenditure per accepted unit of code increased by an estimated 25% to 40%. Flat unit prices masked higher total cost of ownership.
Engineering Recommendations: Actionable Guidance for Teams
Development teams evaluating whether to upgrade or retain their current LLM configurations should consider the following workload-specific recommendations:
Final Verdict: The Benchmark Bubble and Developer Reality
The launch-day reception of Grok 4.7 demonstrates an accelerating disconnect in frontier artificial intelligence: the gap between leaderboard optimization and production utility. While labs construct models capable of achieving record marks on curated synthetic benchmarks, practitioners demand reliable spatial reasoning, disciplined token consumption, and predictable economics.
The feedback documented across X is neither premature nor isolated. It represents precise, verifiable technical evidence provided by paying engineers with real workloads. Until xAI addresses recursive token overhead and corrects spatial synthesis regressions, Grok 4.7 stands as an instructive example of why benchmark claims must always yield to human engineering verification.