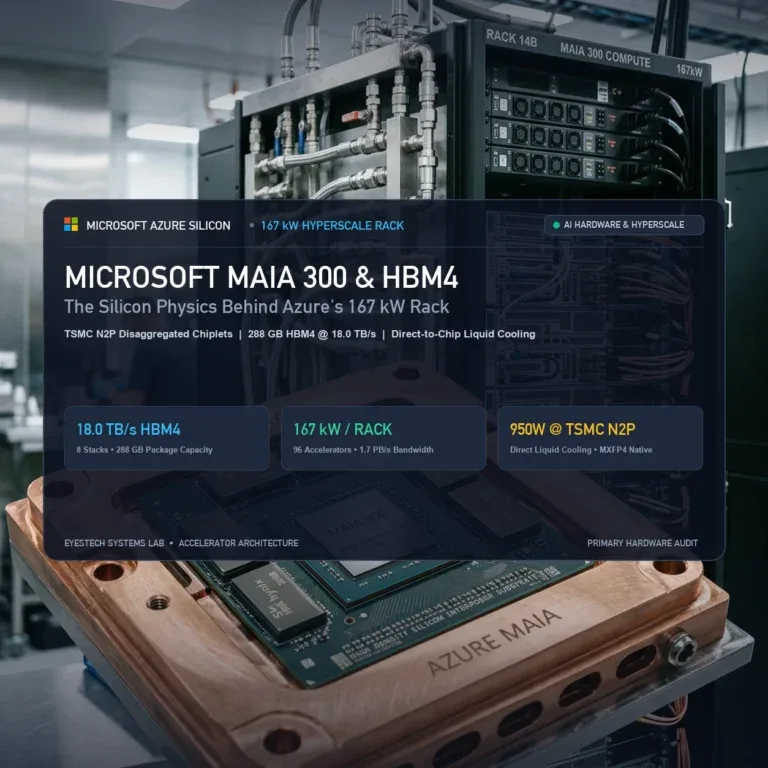
Microsoft Maia 300 pairs 288GB HBM4 at 18 TB/s on TSMC N2P across 96-chip 167 kW racks, bypassing Nvidia memory walls via direct-to-chip liquid cooling.
Microsoft Maia 300 pairs 288GB HBM4 at 18 TB/s on TSMC N2P across 96-chip 167 kW racks, bypassing Nvidia memory walls via direct-to-chip liquid cooling.
NVIDIA Research’s Low-Rank Gradient Sketches (LoGRA) algorithm reduces reinforcement learning optimizer VRAM consumption by 45.7% on 7-billion-parameter…
Strata runs 125B Qwen3.8-Flash-Next on 12GB VRAM at 45 tok/s using predictive expert prefetching and io_uring. Here is the PCIe math and setup.
Drone strikes knocked out two Yandex hyperscale AI data centers and 40% of its fleet. Under Western sanctions, ruined H100 clusters cannot be replaced.
FeSens openTPU runs LFM2.5 at 85.8 tok/s on Kintex-7 FPGA silicon via agent-designed RTL, but off-chip DDR bandwidth caps multi-billion models at 1-4 tok/s.
Apple’s M5 Ultra Mac Studio introduces a quad-die silicon packaging topology delivering 1.2 TB/s of unified memory…
Google’s Project Suncatcher evaluates deploying Trillium TPUs to orbit. We analyze vacuum heat rejection, proton radiation, and 10 Tbps free-space optical DWDM.
Benchmarking Apple M5 Max/Ultra Mac Studio (oMLX, Qwen 3.8 27B, Bonsai 2 27B, qwen-image-2.1) against Thunderobot’s Ryzen AI Max+ 395 120B MoE SSD laptop.
Leaked $500/mo ChatGPT Pro Max targets Fastest Work and Codex on Cerebras silicon as OpenAI GPT-6 Astra doubles Fable 5.1 spend on Vercel AI Gateway.
Sarvam Vision 2.1 sets a new Pareto frontier in document intelligence, scoring 87.3% on olmOCR and 94.97% on OmniDocBench with 87.39% Indic word accuracy.