
Apple’s M5 Ultra Mac Studio introduces a quad-die silicon packaging topology delivering 1.2 TB/s of unified memory…
Apple’s M5 Ultra Mac Studio introduces a quad-die silicon packaging topology delivering 1.2 TB/s of unified memory…
Benchmarking Apple M5 Max/Ultra Mac Studio (oMLX, Qwen 3.8 27B, Bonsai 2 27B, qwen-image-2.1) against Thunderobot’s Ryzen AI Max+ 395 120B MoE SSD laptop.
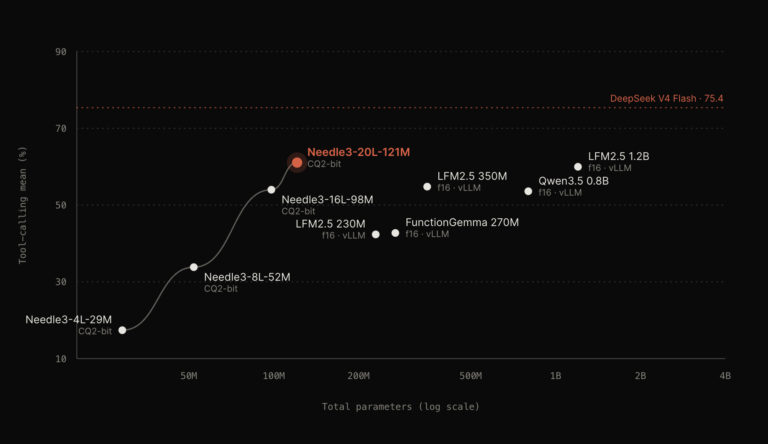
Needle 3 delivers 86% tool accuracy in an 8MB–29MB binary at 4,000 tok/sec. Cactus Compute’s laddered architecture replaces generative chat with edge automation.

An exhaustive architectural audit comparing Qualcomm’s Snapdragon 8 Elite Hexagon NPU against Apple’s A20 Pro 32-core Neural Engine running on-device INT8 Vision-Language Models (MiniCPM-V 2.6, Llama 3.2-Vision, and Qwen2-VL).
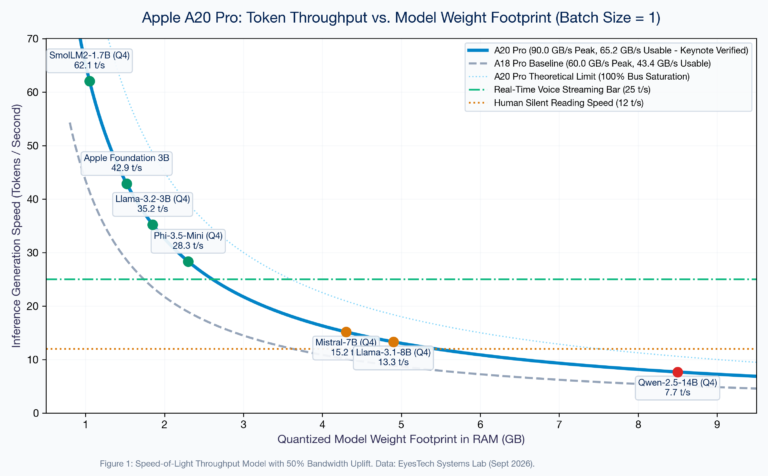
An architectural teardown of Apple’s A20 Pro 2nm GAAFET silicon: testing the 32-core Neural Engine, 65.2 GB/s memory bandwidth wall, copper vapor chamber thermals, and iOS Jetsam limits running 3B to 7B LLMs on-device.
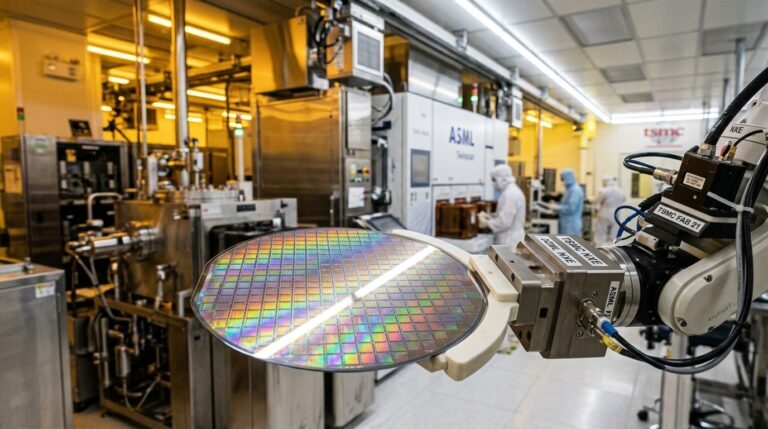
A semiconductor engineering investigation by Lukas Schmidt: inside TSMC’s $30,000 N2 wafer costs, A20 Pro GAAFET nanosheet physics, the WMCM packaging revolution, and why the base iPhone 18 is trapped on 8GB RAM without on-device Apple Intelligence.
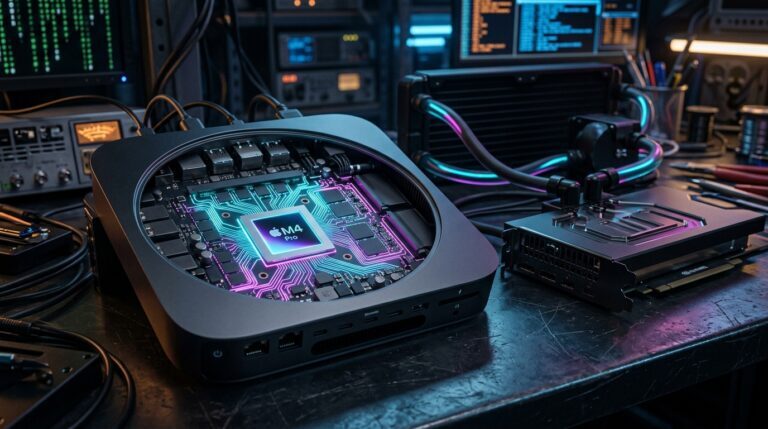
For three years, the undisputed gospel of the homelab AI community was brutally simple: buy a used…
Can Apple’s M5 Ultra Mac Studio run DeepSeek V4 Flash locally? We explain memory, quantization, runtimes, speed limits, pricing and who should buy.