



On September 17, 2026, Z.ai (Zhipu AI) revealed the first empirical, production-grade milestone of Recursive Self-Improvement (RSI):…
On September 17, 2026, Z.ai (Zhipu AI) revealed the first empirical, production-grade milestone of Recursive Self-Improvement (RSI):…
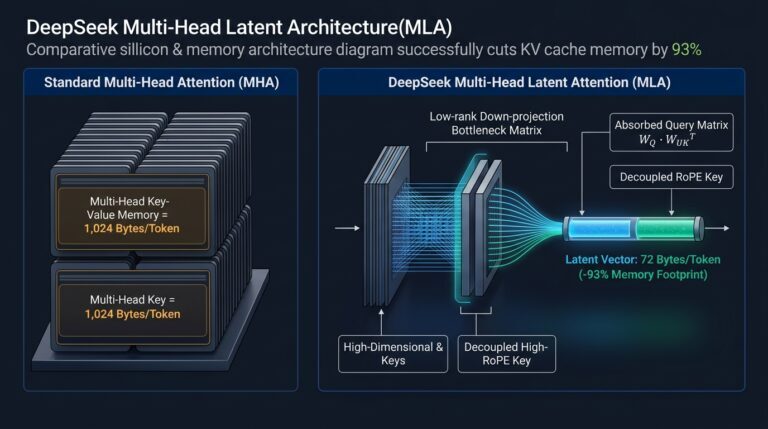
DeepSeek Multi-Head Latent Attention compresses KV cache down to 0.16 KB/token/layer. Here is the low-rank projection math and 128k context serving economics.
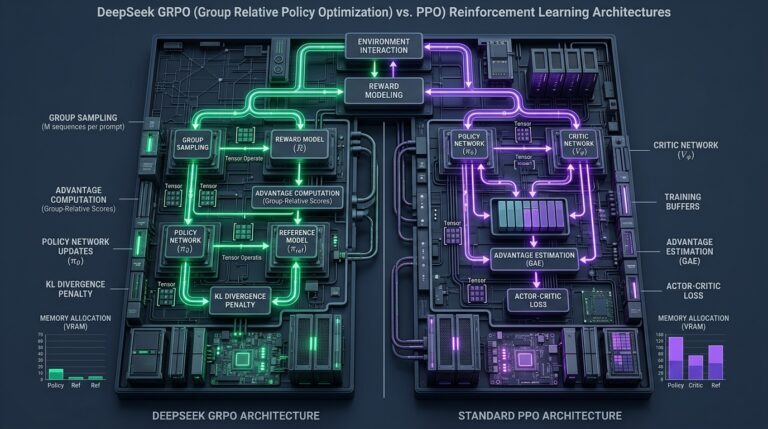
Scaling Reinforcement Learning from Human Feedback (RLHF) to multi-thousand-token reasoning models encountered an insurmountable systems bottleneck: the…
Forensic investigation into DeepSeek’s unit economics: why no Western cloud could match the pre-August $0.28 price, why DeepSeek temporarily hiked rates on August 16 after an 8-trillion-token surge, how V4.1-Flash’s 890-byte CED attention enables Western startups to hit $0.66 profitably today, and why American Big Tech hyperscalers charge a 4,000% markup to service legacy debt.
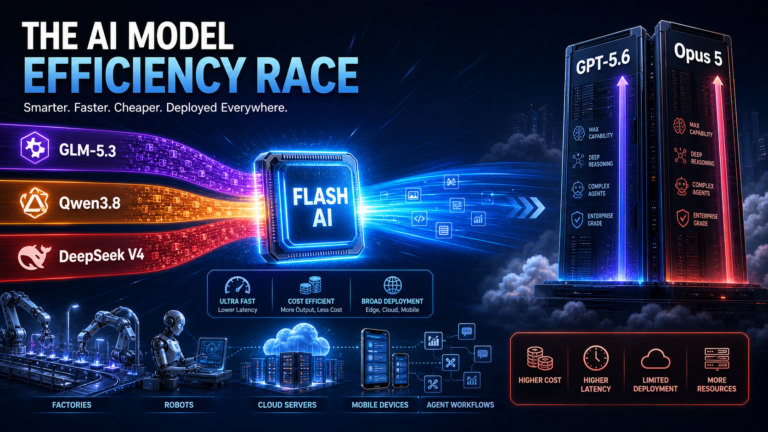
China’s Flash AI models are not a retreat from frontier AI. They are a deployment strategy built around cheaper inference, domestic chips and agents.

Claude Sonnet has been one of the safest defaults for developers building with AI. It is polished,…

If you haven’t been paying close attention to the open-weights AI ecosystem over the last few weeks,…

The question keeps returning in geopolitical debates, market briefings, and defense circles: will China invade Taiwan in…

Imagine a world where you can deploy a model with the reasoning depth of Claude 4.5 Opus,…

If you have been reading the headlines over the last few months, you might be convinced that…


