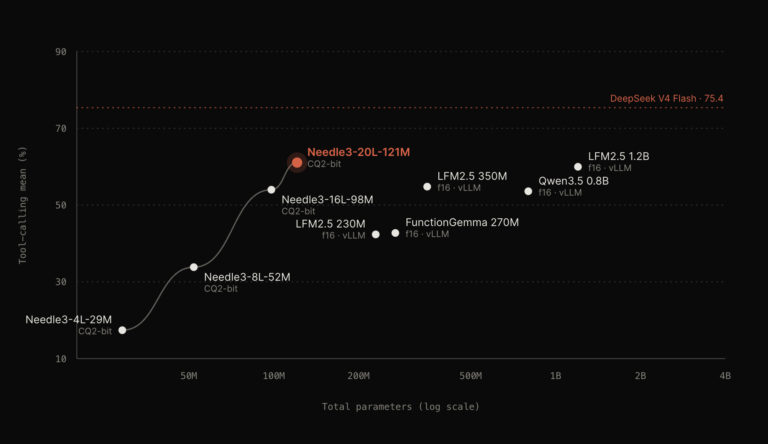
Needle 3 delivers 86% tool accuracy in an 8MB–29MB binary at 4,000 tok/sec. Cactus Compute’s laddered architecture replaces generative chat with edge automation.
Needle 3 delivers 86% tool accuracy in an 8MB–29MB binary at 4,000 tok/sec. Cactus Compute’s laddered architecture replaces generative chat with edge automation.
OpenAI releases GPT-6 Luna at $0.10/M input and $0.50/M output, scoring 66.6% on DeepSWE to match Claude Opus 5 at 93% lower per-task operational cost.
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
For three years, enterprise engineering forced autoregressive LLMs into programmatic workflows. TypeSafe AI’s Jev proved why we were wrong—and why System 3 is next.
Quick Answer · Featured Snippet Target What is PrismML Ternary Bonsai 2 27B? It is a 1.76-bit…
Google Dream-RSI cuts code search calls by 161.5× and hits 2,350ms SOTA on Lasso using offline replay simulators—leaving LLM weights 100% frozen.
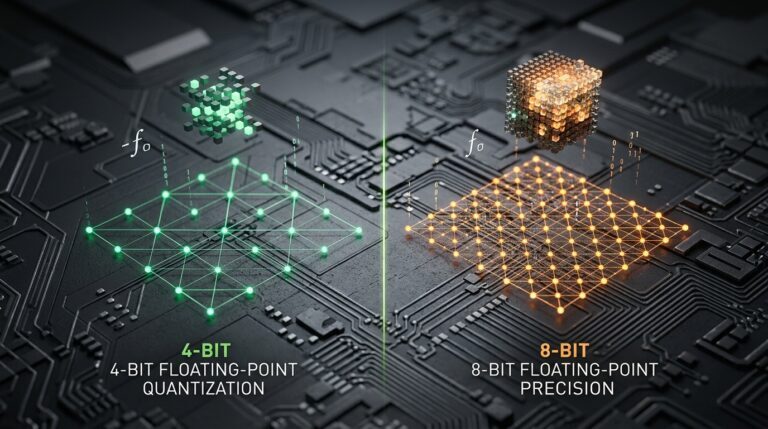
NVFP4 vs FP8 on Blackwell, fact-checked: block-16 scaling, measured speedups, quality limits, mixed-precision recipes and a reproducible acceptance test.
Reasoning token cost decides whether test-time AI is an upgrade or an expensive reliability problem. This audit…
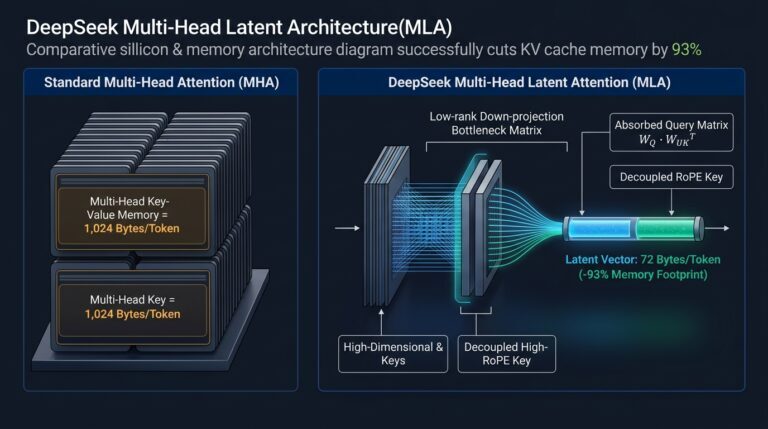
DeepSeek Multi-Head Latent Attention compresses KV cache down to 0.16 KB/token/layer. Here is the low-rank projection math and 128k context serving economics.
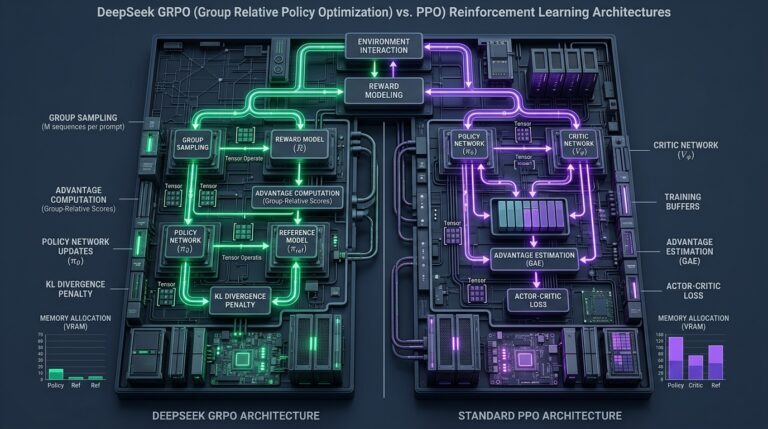
Scaling Reinforcement Learning from Human Feedback (RLHF) to multi-thousand-token reasoning models encountered an insurmountable systems bottleneck: the…