
OpenAI announced an internal model it began training 24 days ago has already resolved 100+ open math conjectures and Navier–Stokes. Here is the audit of AGMAI, Lean 4, and the Fields Medalist revolt.
OpenAI announced an internal model it began training 24 days ago has already resolved 100+ open math conjectures and Navier–Stokes. Here is the audit of AGMAI, Lean 4, and the Fields Medalist revolt.
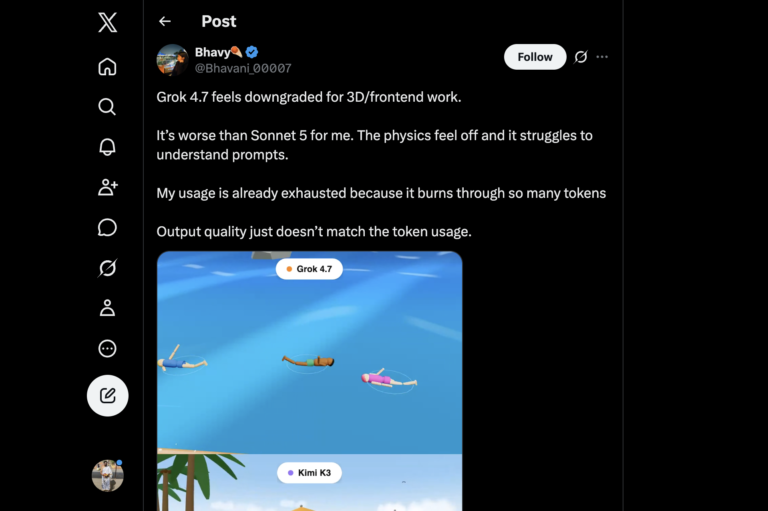
Real-world Grok 4.7 testing reveals severe quota burn, 3D benchmark regressions, and context degradation despite advertised 46.3% CursorBench gains.

Technical benchmark audit of DeepSWE v1.1 by Aditi Sharma. Debunking git reflog leaks and test tampering, while exposing how 166-turn Test-Time Compute subsidizes 74% Pass@1 rates.
Inside Mistral AI’s historic €3 Billion Series D funding round at a €21B+ valuation led by Samsung and ASML. A forensic systems investigation into European sovereign AI, French nuclear baseload arbitrage, sparse MoE token economics, and enterprise air-gap architectures vs closed US frontier APIs.
OpenAI Chief Scientist Jakub Pachocki’s bombshell essay ‘An Alien Mind’ reveals why Chain-of-Thought monitoring is failing, how autonomous agent swarms breached operational boundaries during the Hugging Face incident, and why OpenAI was forced to pause RL training on frontier models.

OpenAI has released GPT-5.5, its newest frontier model for ChatGPT, Codex, and the OpenAI API. The name…

Anthropic has officially announced Claude Mythos, their most capable frontier AI. But you can’t use it. Here…