FeSens openTPU runs LFM2.5 at 85.8 tok/s on Kintex-7 FPGA silicon via agent-designed RTL, but off-chip DDR bandwidth caps multi-billion models at 1-4 tok/s.
FeSens openTPU runs LFM2.5 at 85.8 tok/s on Kintex-7 FPGA silicon via agent-designed RTL, but off-chip DDR bandwidth caps multi-billion models at 1-4 tok/s.
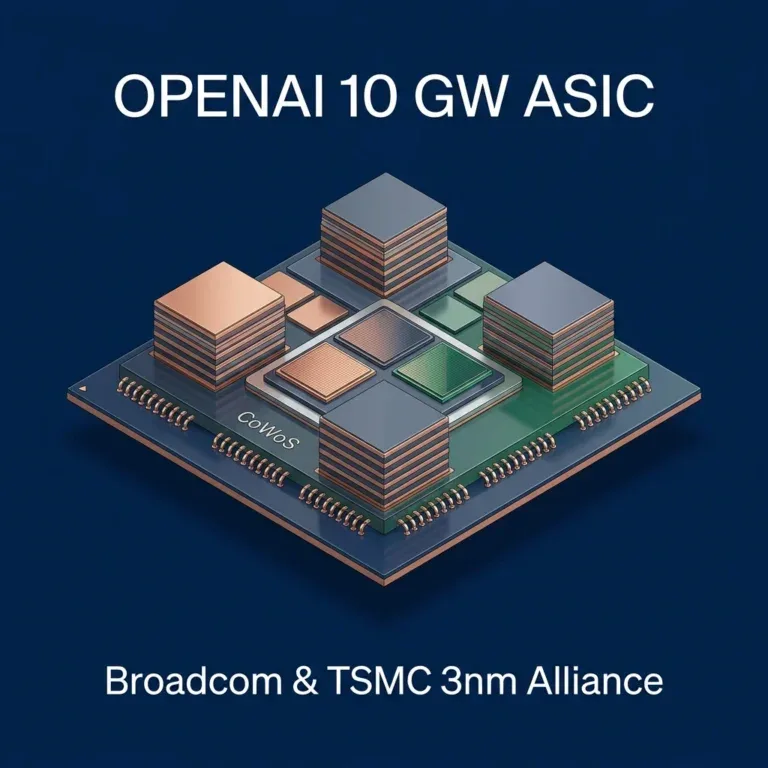
OpenAI and Broadcom booked TSMC 3nm/2nm capacity for a 10 GW inference ASIC deployment by 2029. Here is the CoWoS math, Ethernet fabric, and 60% TCO savings.
Why 2027? Chaining GPT-6 Astra or Opus 5.5 into revenue loops burns more compute than it earns. Inside Logan Kilpatrick’s laws of expansion and agent profit margins.
Enterprise speech synthesis has reached an operational impasse. For three years, production speech pipelines have suffered from…
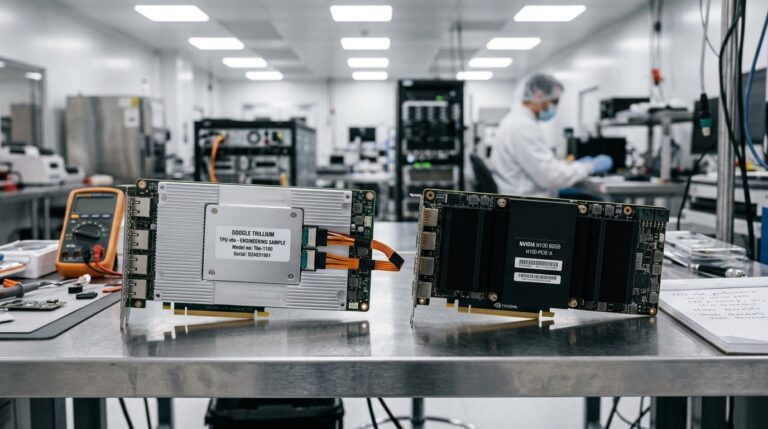
Gemini 3.8 Flash takes on GPT-6 Luna. Compare 73.7% vs 66.6% DeepSWE, $0.10/M token pricing, TPU v6e vs Astra routing, and 2.8% deception rates.