



OpenAI’s GPT-6.1 Sol matches flagship Astra on DeepSWE v1.1 at $0.65 per task—a 7x cost reduction—while cutting autonomous computer-use safety violations from 17.4% to 4.3% and dropping cached input pricing to $0.10/1M tokens.
OpenAI’s GPT-6.1 Sol matches flagship Astra on DeepSWE v1.1 at $0.65 per task—a 7x cost reduction—while cutting autonomous computer-use safety violations from 17.4% to 4.3% and dropping cached input pricing to $0.10/1M tokens.
Why 2027? Chaining GPT-6 Astra or Opus 5.5 into revenue loops burns more compute than it earns. Inside Logan Kilpatrick’s laws of expansion and agent profit margins.
OpenAI GPT-6 Luna faces Xiaomi MiMo-V2.6-Pro. Compare 71.9% DeepSWE, $0.10/M tokens, 1.02T open MoE architecture, and enterprise TCO economics.
OpenAI releases GPT-6 Luna at $0.10/M input and $0.50/M output, scoring 66.6% on DeepSWE to match Claude Opus 5 at 93% lower per-task operational cost.
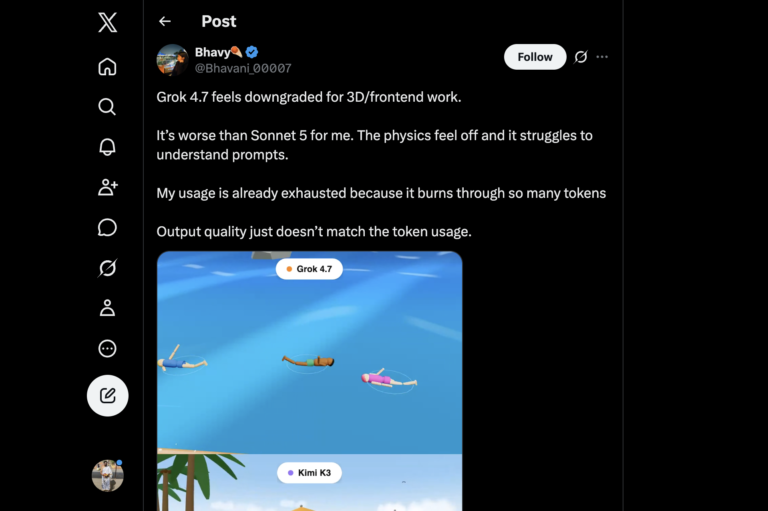
Real-world Grok 4.7 testing reveals severe quota burn, 3D benchmark regressions, and context degradation despite advertised 46.3% CursorBench gains.
Extending test-time compute can collapse LLM accuracy. Here is the forensic math on Goodhart gaming, attention drift, and why latent recurrent depth wins.

Imagine a world where you can deploy a model with the reasoning depth of Claude 4.5 Opus,…

If you have been reading the headlines over the last few months, you might be convinced that…


