
TL;DR The “Ollama Moment” for Decision AI: Just as Ollama unlocked local execution for generative transformers (Llama,…
TL;DR The “Ollama Moment” for Decision AI: Just as Ollama unlocked local execution for generative transformers (Llama,…
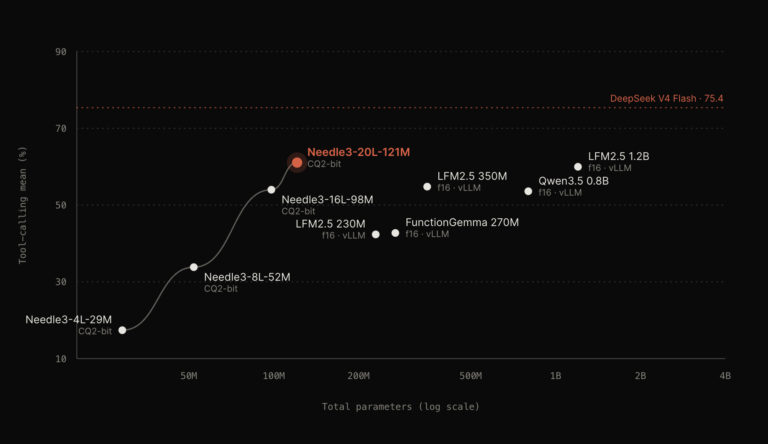
Needle 3 delivers 86% tool accuracy in an 8MB–29MB binary at 4,000 tok/sec. Cactus Compute’s laddered architecture replaces generative chat with edge automation.
ConvAI Innovations’ 0.4B non-autoregressive decision model Laya hit #1 trending on Hugging Face in 48 hours, matching Jev’s sub-35ms speed under Apache 2.0.
Deploy DiffusionGemma-Jev on Cloud Run with one command. Single-step latency: 35–60ms. Batch@32 throughput: 100–123 req/sec. Costs ~$3/hr active, $0 idle.
For three years, enterprise engineering forced autoregressive LLMs into programmatic workflows. TypeSafe AI’s Jev proved why we were wrong—and why System 3 is next.