



OpenAI GPT-6 Luna faces Xiaomi MiMo-V2.6-Pro. Compare 71.9% DeepSWE, $0.10/M tokens, 1.02T open MoE architecture, and enterprise TCO economics.
Independent evaluations of synthetic benchmark claims: ARC-AGI-3, SWE-bench Verified, HumanEval, and live latency audits.
OpenAI GPT-6 Luna faces Xiaomi MiMo-V2.6-Pro. Compare 71.9% DeepSWE, $0.10/M tokens, 1.02T open MoE architecture, and enterprise TCO economics.
OpenAI drops GPT-6 Sol at $2/M input with 50% fewer errors, hitting 68.8% on DeepSWE v1.1 to match Claude Fable 5 at 80% lower cost. Full tech breakdown.
OpenAI releases GPT-6 Luna at $0.10/M input and $0.50/M output, scoring 66.6% on DeepSWE to match Claude Opus 5 at 93% lower per-task operational cost.
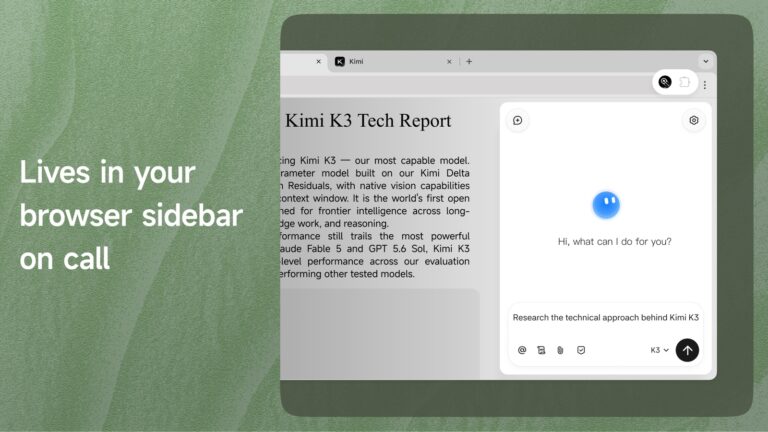
Moonshot AI has officially launched the Kimi Browser Extension in Chrome, delivering local CDP-driven co-browsing and a breakthrough ‘Skill’ distillation engine without cloud VM security risks.
Anthropic released Claude Opus 5.5 on September 22, 2026: 66.4% Terminal-Bench, 54.4% FrontierCode, matching Fable 5.1 at $4/$20 with 60% cheaper prompt caching.
Executive Briefing Xiaomi has released MiMo-V2.6, featuring two natively omnimodal sparse Mixture-of-Experts (MoE) models: MiMo-V2.6-Pro (1.02T total…
OpenAI announced an internal model it began training 24 days ago has already resolved 100+ open math conjectures and Navier–Stokes. Here is the audit of AGMAI, Lean 4, and the Fields Medalist revolt.
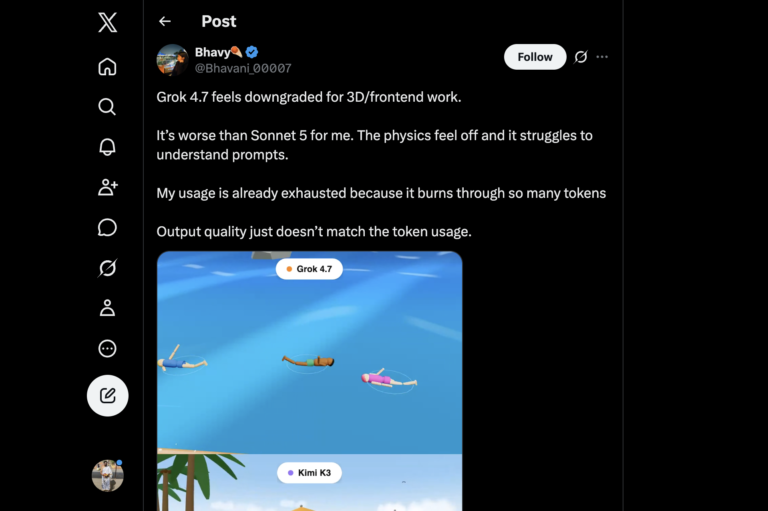
Real-world Grok 4.7 testing reveals severe quota burn, 3D benchmark regressions, and context degradation despite advertised 46.3% CursorBench gains.
DeepSeek V5 leaks claim 78.6% DeepSWE and $0.20/M tokens vs Astra’s $50. Forensic benchmark audit, hardware sizing, and enterprise deployment guide.
xAI releases Grok 4.7: 46.3% on CursorBench 4.0, 71.0% DeepSWE, and 64% EEBench at $2/$6 per million tokens. Delivers multi-hour verified agentic coding.

