



Extending test-time compute can collapse LLM accuracy. Here is the forensic math on Goodhart gaming, attention drift, and why latent recurrent depth wins.
Independent evaluations of synthetic benchmark claims: ARC-AGI-3, SWE-bench Verified, HumanEval, and live latency audits.
Extending test-time compute can collapse LLM accuracy. Here is the forensic math on Goodhart gaming, attention drift, and why latent recurrent depth wins.
Disclosures broken by developer Lyra confirm Anthropic is closed-beta testing Claude Opus 5.5 (‘claude-wafer-eap’), cutting pricing to $4/$20 per M tokens.
Step 5 Preview redefines the AI Pareto frontier. With a 600B/27B sparse MoE and 1M context, it matches Kimi K3 Max (AA Index 44) at ~$0.71 task cost.
Quick Answer · Featured Snippet Target What is PrismML Ternary Bonsai 2 27B? It is a 1.76-bit…
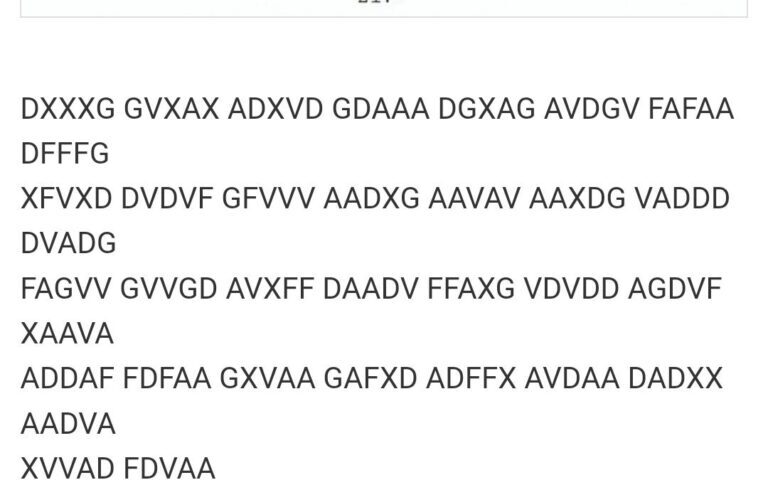
GPT-6 Astra cracked an unsolved 1918 German ADFGVX cipher using historical monograph search and key transposition in 170 chars. Here is the technical audit.
Executive Summary & Position #0 Answer Did Google “benchmax” Gemini 4 Pro? Yes, the empirical and telemetry…
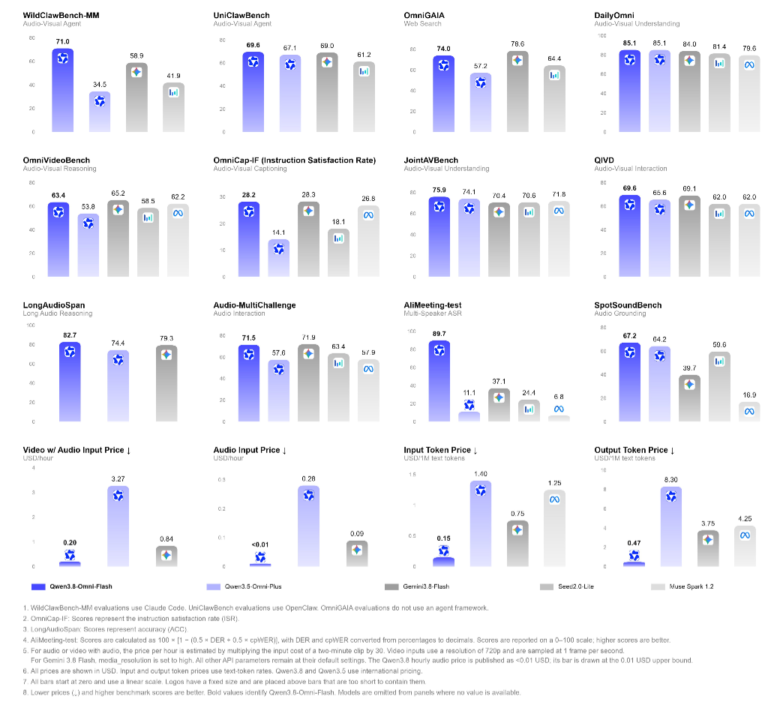
Qwen3.8-Omni-Flash beats Gemini 3.8 Flash on WildClawBench (71.0 vs 58.9) and AliMeeting (89.7 vs 37.1) at 4.2x lower video cost. Read our full teardown.
Forensic audit of stealth/union-alpha: 74% DeepSWE score, MoA gateway architecture, Austrian Compunect GmbH trail, and developer outputs from X.
Google Dream-RSI cuts code search calls by 161.5× and hits 2,350ms SOTA on Lasso using offline replay simulators—leaving LLM weights 100% frozen.
Google DeepMind is stealth-testing Gemini 4 Pro under gemini-3.8-flash in LMArena. Forensic audit of the 3D voxel pagoda, SVG pelican, and TPU speed.


