
Nemotron 3.5 Super VL supports built-in MTP and a separate LiLiCorr drafter. Compare deployment recipes, cache assumptions and real task-time implications.
Silicon architectures, VRAM requirements, GPU benchmarks, Apple Silicon unified memory, and local LLM deployment.
Nemotron 3.5 Super VL supports built-in MTP and a separate LiLiCorr drafter. Compare deployment recipes, cache assumptions and real task-time implications.
Flint runs through Ollama or Recursive’s Rec engine. Compare the 23 GB download, Rec’s 48 GB Mac requirement and BF16 weights before choosing a runtime.
Ornith 1.5 122B Q4_K_M is a 75.84 GB download. Compare BF16, FP8 and MLX files, budget runtime memory and start a local llama.cpp server with 8K context.
Fish Audio Drama 3 needs 48 GB VRAM on the documented FP8 path. Compare int4 weight savings, runtime API limits and local setup before downloading.
Install VoiceStudio on Windows, Apple Silicon or Linux. Check Electron packages, 10 GB disk guidance, engines and local API settings before you start.
Bonsai 2 9B’s default GGUF is 2.42GB; adding its Q8 vision projector brings downloads to 3.04GB. Match PQ2, PTQ or Q2 files to the correct llama.cpp build.
NVIDIA estimates 23.83GB for text-only Nemotron 3.5 Bolt, while its GGUF recipes use larger budgets. Check vision, context and draft-model requirements.
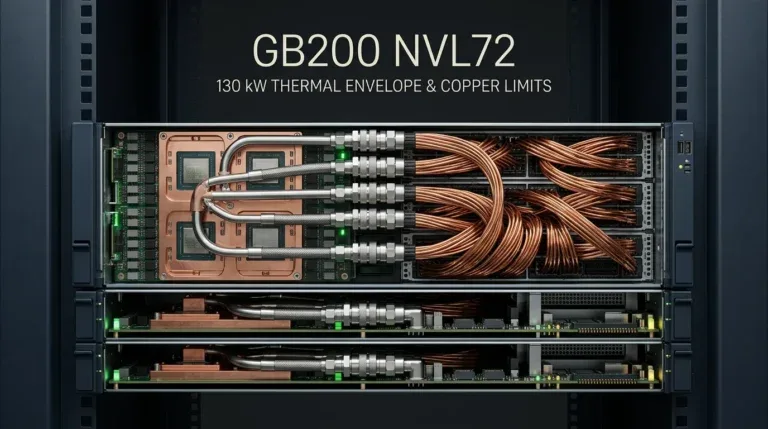
Inside the NVIDIA GB200 NVL72 liquid cooling crisis: how a 130 kW envelope, 148 L/min PG25 flow rate, and 5,184 copper cables hit a hard physics wall.
Liquid AI claims 184 tok/s on Apple M5 Max with 2.45B active compute, but LFM2.5-24B requires 15GB RAM, crushing 16GB laptops and lagging on SWE-bench.
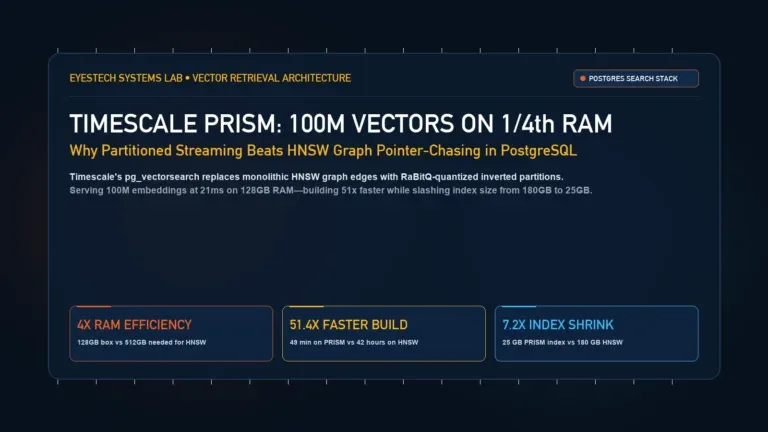
Timescale pg_vectorsearch and PRISM replace HNSW graphs with RaBitQ-quantized partitions, serving 100M vectors at 21ms on 128GB RAM with 51x faster builds.