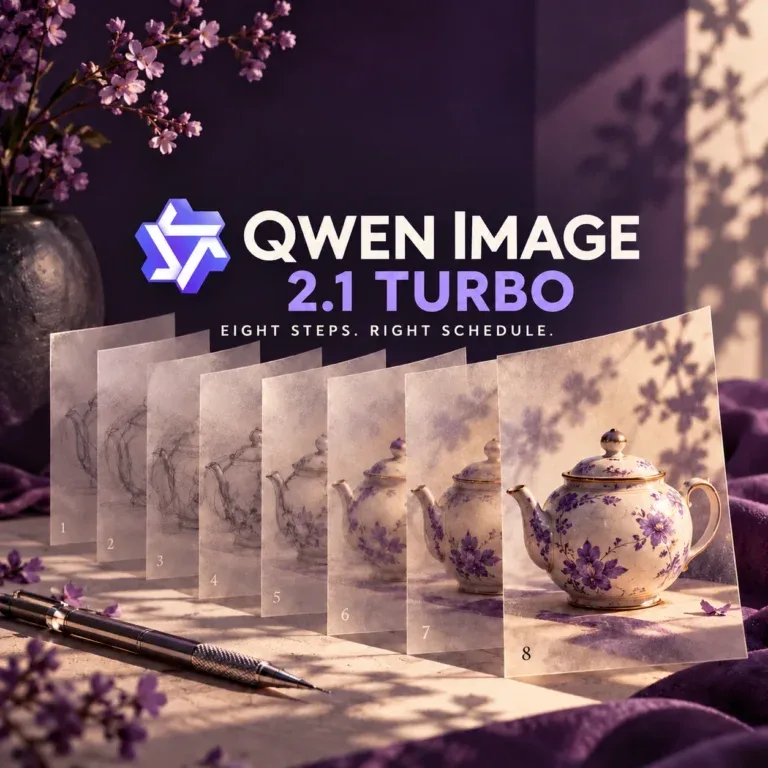

Qwen Image 2.1 Turbo uses a saved eight-step schedule and CFG 1. Local setup needs current Diffusers; commercial use needs a separate license.
Silicon architectures, VRAM requirements, GPU benchmarks, Apple Silicon unified memory, and local LLM deployment.
Qwen Image 2.1 Turbo uses a saved eight-step schedule and CFG 1. Local setup needs current Diffusers; commercial use needs a separate license.
Saluki packs Qwen3.8-27B into 7.89GB. Its 88/120 tool score hides lost and gained tasks, parser sensitivity and memory costs beyond the model file.
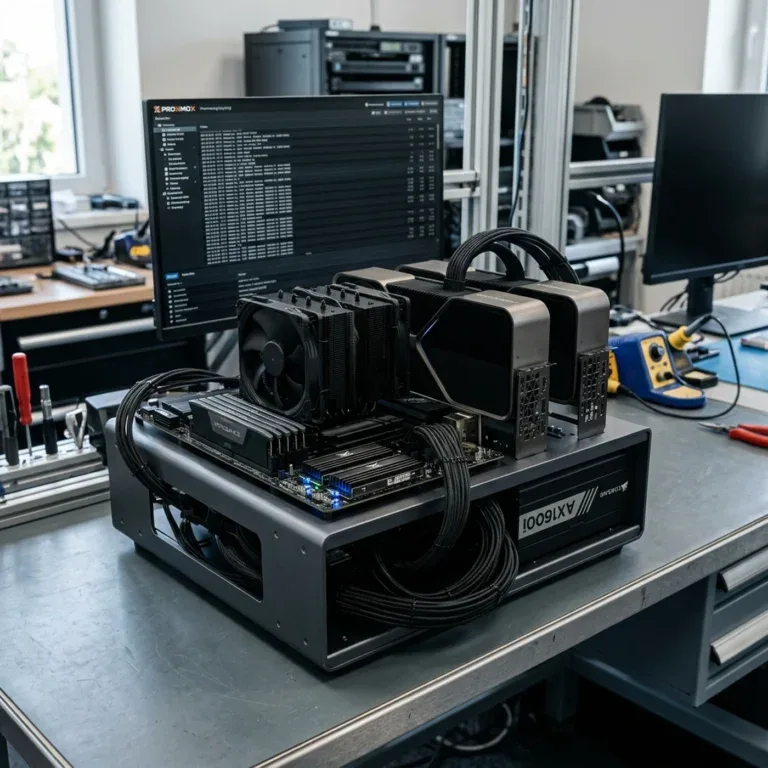
Strata runs 125B Qwen3.8-Flash-Next on 12GB VRAM at 45 tok/s using predictive expert prefetching and io_uring. Here is the PCIe math and setup.
At Open Source Summit Europe 2026, Microsoft Director Ryan Waite warned enterprises against proprietary model capture: do not surrender your organizational learning loops to closed APIs. Here is how to architect infrastructure mobility across open-weight models.
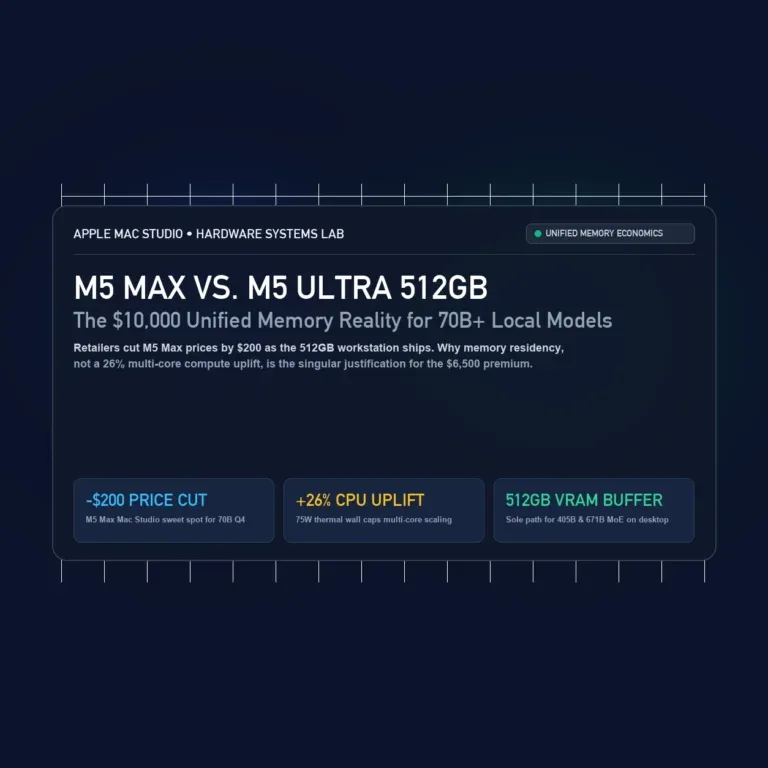
Retailers cut M5 Max Mac Studio prices by $200 as the 512GB M5 Ultra ships at $10,000+. Here is why VRAM residency, not a 26% CPU uplift, dictates the buy.
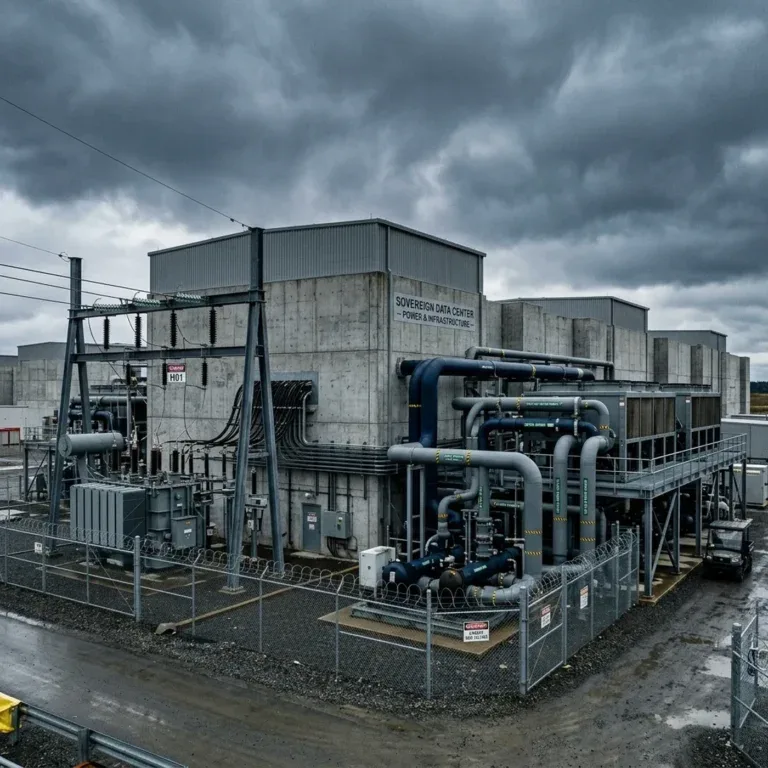
Drone strikes knocked out two Yandex hyperscale AI data centers and 40% of its fleet. Under Western sanctions, ruined H100 clusters cannot be replaced.
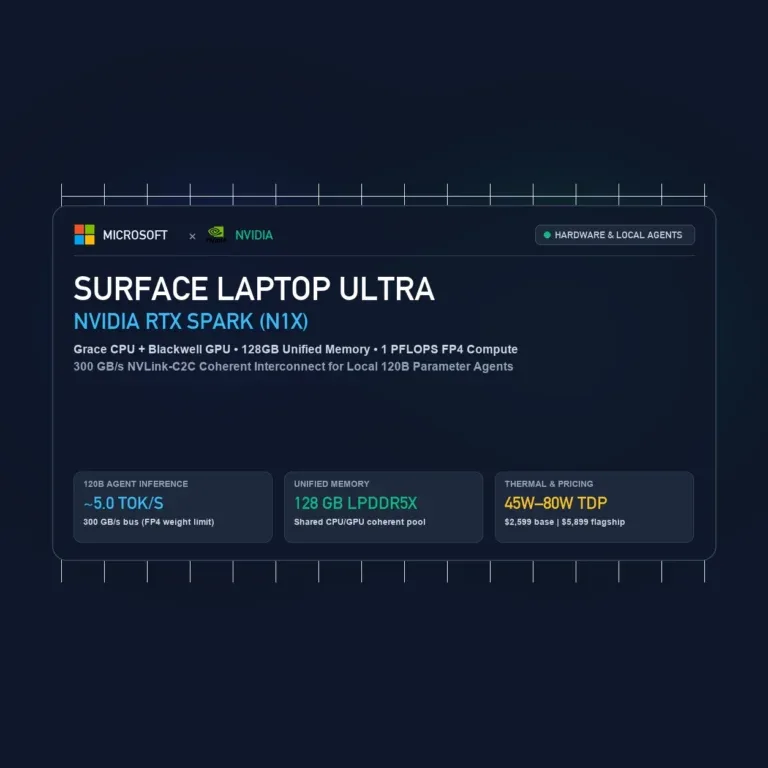
Microsoft and NVIDIA’s Surface Laptop Ultra pairs an Arm Grace CPU and Blackwell GPU via 300 GB/s NVLink-C2C. Here is what 128GB unified memory and 1 PFLOPS FP4 mean for 120B local agents.
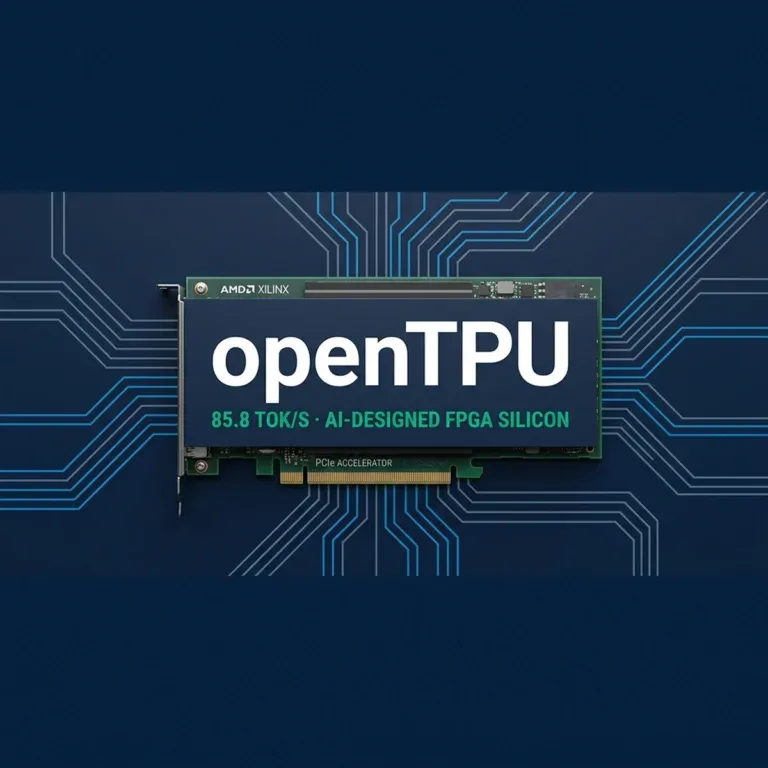
FeSens openTPU runs LFM2.5 at 85.8 tok/s on Kintex-7 FPGA silicon via agent-designed RTL, but off-chip DDR bandwidth caps multi-billion models at 1-4 tok/s.
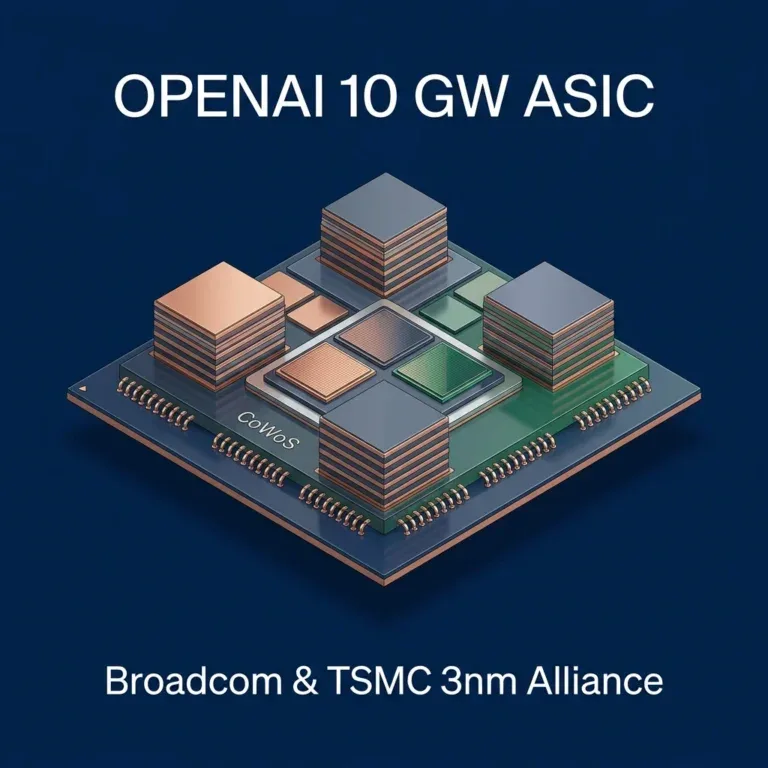
OpenAI and Broadcom booked TSMC 3nm/2nm capacity for a 10 GW inference ASIC deployment by 2029. Here is the CoWoS math, Ethernet fabric, and 60% TCO savings.
Paradigma reports 94.01% on AIME 2026 for its 1B math model. Off-scope failures and specific prompt and runtime requirements define its practical use.