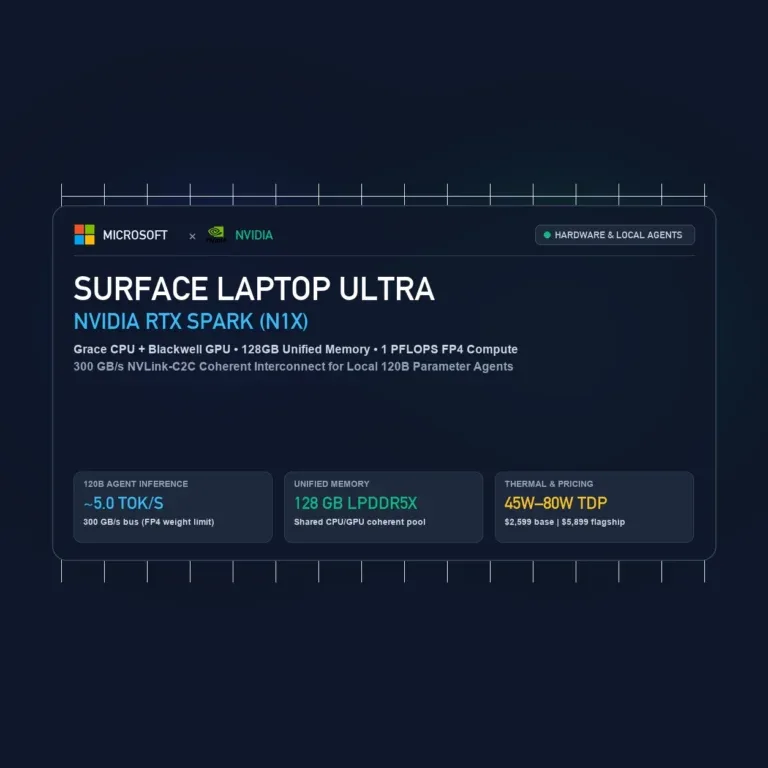

Microsoft and NVIDIA’s Surface Laptop Ultra pairs an Arm Grace CPU and Blackwell GPU via 300 GB/s NVLink-C2C. Here is what 128GB unified memory and 1 PFLOPS FP4 mean for 120B local agents.
Silicon architectures, VRAM requirements, GPU benchmarks, Apple Silicon unified memory, and local LLM deployment.
Microsoft and NVIDIA’s Surface Laptop Ultra pairs an Arm Grace CPU and Blackwell GPU via 300 GB/s NVLink-C2C. Here is what 128GB unified memory and 1 PFLOPS FP4 mean for 120B local agents.
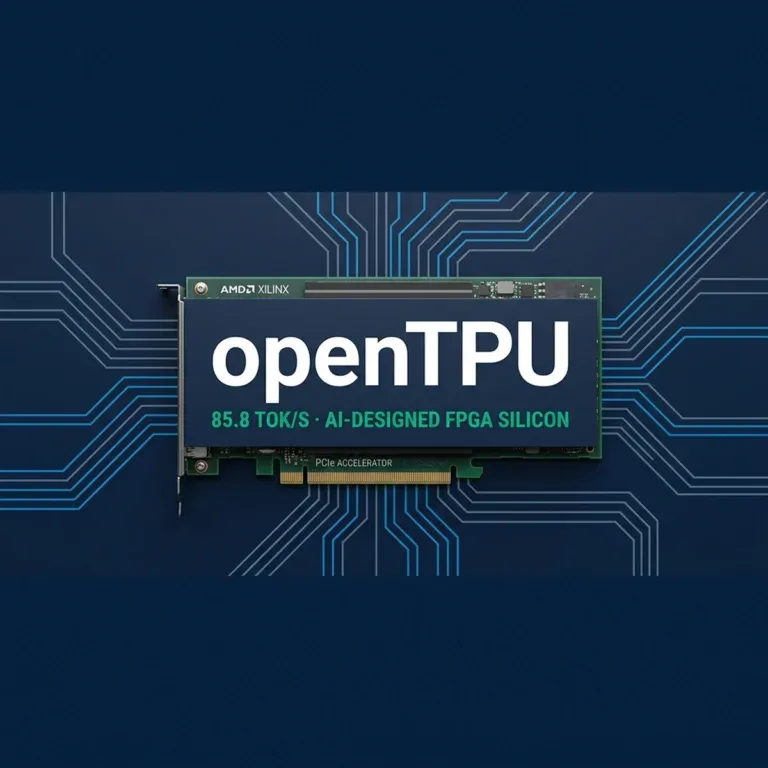
FeSens openTPU runs LFM2.5 at 85.8 tok/s on Kintex-7 FPGA silicon via agent-designed RTL, but off-chip DDR bandwidth caps multi-billion models at 1-4 tok/s.
OpenAI and Broadcom booked TSMC 3nm/2nm capacity for a 10 GW inference ASIC deployment by 2029. Here is the CoWoS math, Ethernet fabric, and 60% TCO savings.
Paradigma reports 94.01% on AIME 2026 for its 1B math model. Off-scope failures and specific prompt and runtime requirements define its practical use.
Janus bundles llama.cpp Vulkan DLLs into a 50MB Go binary for cross-vendor GGUF local LLM inference across AMD, Intel, and Nvidia GPUs without Python or Docker.
DeepGEMM Ascend brings familiar APIs to Huawei Ascend 950. TileLang adds a native backend; 99.8% utilization describes a kernel, not whole-model speed.
DeepSeek has published Ascend 950 versions of two pieces of its model infrastructure: DeepEP-Ascend for moving mixture-of-experts…
Kyutai’s Voice of Reason takes a spoken math question and generates an answer through a speech-native model…
Backblaze reports 1.73% annualized failures for Q2 2026. Drive-days, fleet age and sample size explain why that figure is not a home-NAS forecast.
AMD’s $8.2 billion World Labs deal is pending. Atlas connects spatial context and diffusion; buyers still need measured accelerator performance.