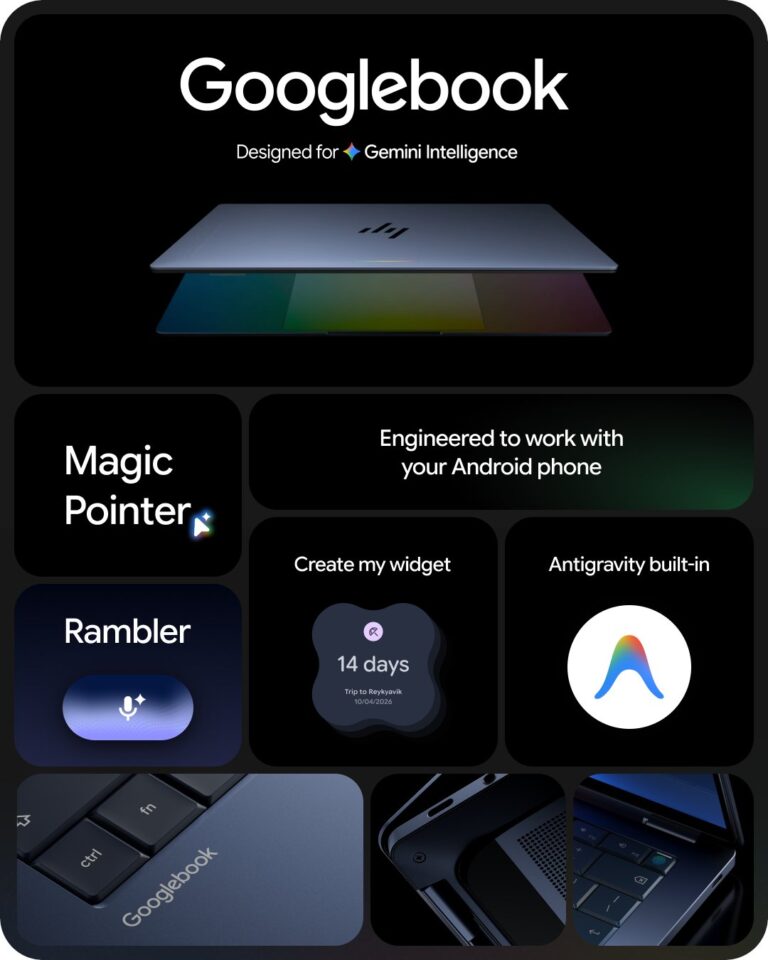

Google launched Googlebook at $899 across Acer, ASUS, Dell, HP, and Lenovo. Built natively on Android with 45+ TOPS NPUs, Magic Pointer, Rambler, and a Level-5 certified pKVM Linux terminal for Antigravity and Claude Code.
Silicon architectures, VRAM requirements, GPU benchmarks, Apple Silicon unified memory, and local LLM deployment.
Google launched Googlebook at $899 across Acer, ASUS, Dell, HP, and Lenovo. Built natively on Android with 45+ TOPS NPUs, Magic Pointer, Rambler, and a Level-5 certified pKVM Linux terminal for Antigravity and Claude Code.
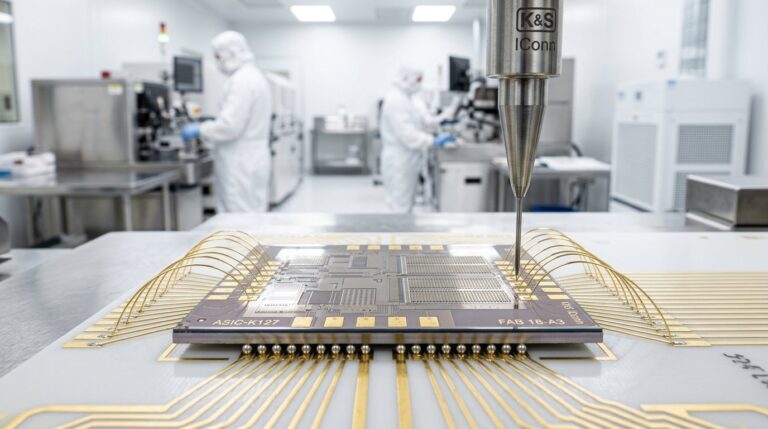
Applied Materials commits $5B as the Tata Dholera Fab enters cleanroom fit-out for Dec 2026 trial runs. We audit India’s 28nm equipment and supply chain.
Alibaba’s Qwen-Image-2.1 brings native 2K RGBA alpha generation to ComfyUI. We audit 7B DiT VRAM draw, 10-image conditioning, and SGLang latency.
Quick Answer · Featured Snippet Target What is PrismML Ternary Bonsai 2 27B? It is a 1.76-bit…
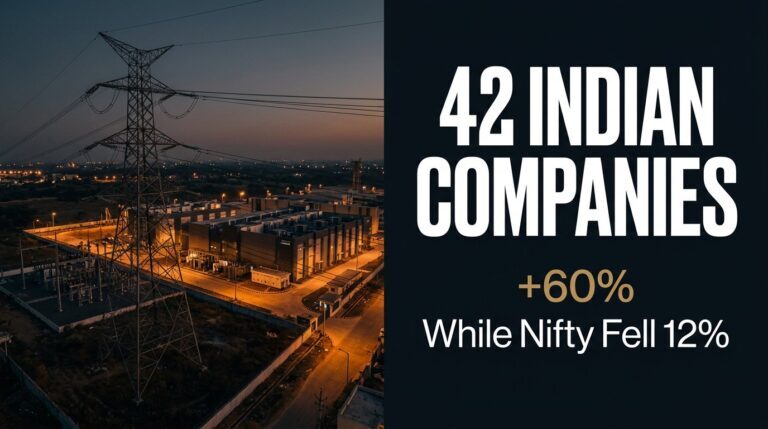
Goldman Sachs identifies 42 Indian AI Enabler stocks up 60% YTD vs Nifty -12%. Deep-dive: exact order books, sector layer performance (40-80%), government policy stack, and structural vulnerabilities.
On September 17, 2026, Z.ai (Zhipu AI) revealed the first empirical, production-grade milestone of Recursive Self-Improvement (RSI):…
Google DeepMind’s Gemini 4 features a 256k output limit, 2.4-min adaptive reasoning, and TPU 8t Virgo scaling. Full systems audit of the leaked argon checkpoint.
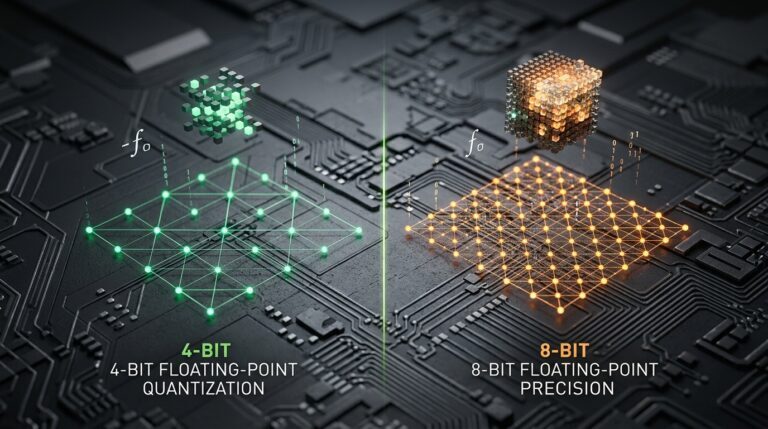
NVFP4 vs FP8 on Blackwell, fact-checked: block-16 scaling, measured speedups, quality limits, mixed-precision recipes and a reproducible acceptance test.
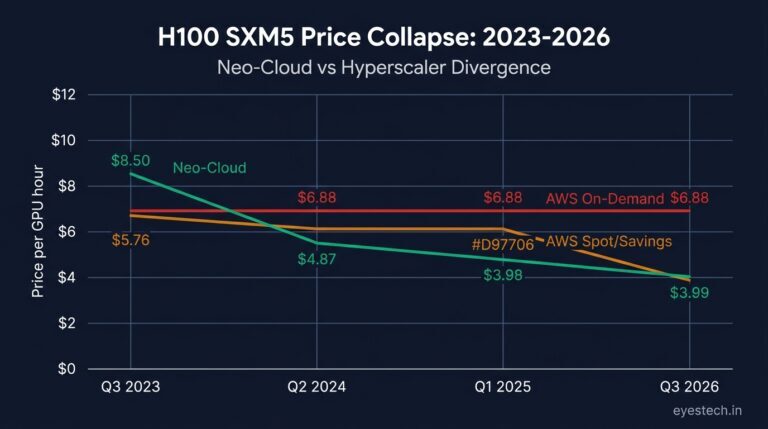
Forensic TCO audit: H100 GPU rental fell from $8.50 to $3.99/GPU-hr by September 2026. AWS p5.48xlarge costs $55.04/hr list but $9.85+/GPU-hr all-in after egress, FSx, VPC fees, and enterprise support taxes. Full break-even math, InfiniBand MFU comparison, and GPU MSA negotiation playbook — by Pooja Iyer, EyesTech Systems Lab.
55+ verified benchmarks on AI inference cost, latency, GPU cluster failure rates, and memory bandwidth walls. Download raw 2026 telemetry data.